Very ML
State-of-the-art Machine Learning News Feed
/r/MachineLearning
последний пост 3 часа назад
Is a second MSc worth it? [D]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

3 часа назад @ reddit.com
Sliced Wasserstein embeddings + HNSW for color-scheme search over 48k paintings [P]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

3 часа назад @ reddit.com
NeurIPS 2026 Paris complimentary registration already full. Did any Top Reviewers get a spot? [D]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

3 часа назад @ reddit.com
I trained a 414k-parameter transformer to fly a boids flock, then tested whether the rules a probe can read are the ones it uses [P]
I trained a 414k-parameter transformer to fly a boids flock, then tested whether the rules a probe can read are the ones it uses [P] I trained a 414k-parameter transformer to fly a boids flock, then tested whether the rules a probe can read are the ones it uses [P]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

4 часа назад @ reddit.com
World Action Models vs VLAs: Robotics Just Had Its GPT-2 Moment [N]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

4 часа назад @ reddit.com
[P] Pecision models that score every allowed label from the logits: Jebadiah v2.1 (27B, 9B), open weights and self-run benchmark results [P]
[P] Pecision models that score every allowed label from the logits: Jebadiah v2.1 (27B, 9B), open weights and self-run benchmark results [P]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

9 часов назад @ reddit.com
Do I need to do anything now to use an ARR August review for NAACL 2027? [D]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

13 часов назад @ reddit.com
What ai is best to operate a system from screen video [p]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

14 часов назад @ reddit.com
Has machine learning research gotten more "wordy"? [D]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

17 часов назад @ reddit.com
I Built a O(NlogN) attention system that retains 97% accuracy over long context (MQAR)[P]
I Built a O(NlogN) attention system that retains 97% accuracy over long context (MQAR)[P] I Built a O(NlogN) attention system that retains 97% accuracy over long context (MQAR)[P]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

1 day назад @ reddit.com
ICLR submissions are broken. Maybe a prediction market? [P]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

1 day, 3 hours назад @ reddit.com
Are .ipynb notebooks already outdated in the agentic era? [D]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

1 day, 7 hours назад @ reddit.com
Help With Choosing Hardware [P]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

1 day, 10 hours назад @ reddit.com
Real-time neural weather restyling for Minecraft on a GTX 1650 (1.4M-param U-Net, distilled from FLUX.2 klein, 30-40 FPS realtime on budget GPU) [P]
Real-time neural weather restyling for Minecraft on a GTX 1650 (1.4M-param U-Net, distilled from FLUX.2 klein, 30-40 FPS realtime on budget GPU) [P] Real-time neural weather restyling for Minecraft on a GTX 1650 (1.4M-param U-Net, distilled from FLUX.2 klein, 30-40 FPS realtime on budget GPU) [P]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

1 day, 14 hours назад @ reddit.com
Woven by Toyota MLE Interview - PyTorch Debugging [D]

Your request has been blocked due to a network policy.

If you're running a script or application, please register or sign in with your developer credentials here.

Additionally make sure your User-Agent is not empty and is something unique and descriptive and try again.

if you're supplying an alternate User-Agent string, try changing back to default as that can sometimes result in a block.

If you think that we've incorrectly blocked you or you would like to discuss easier ways to get the data you want, please file a ticket here.

1 day, 16 hours назад @ reddit.com
Towards Data Science
последний пост 4 часа назад
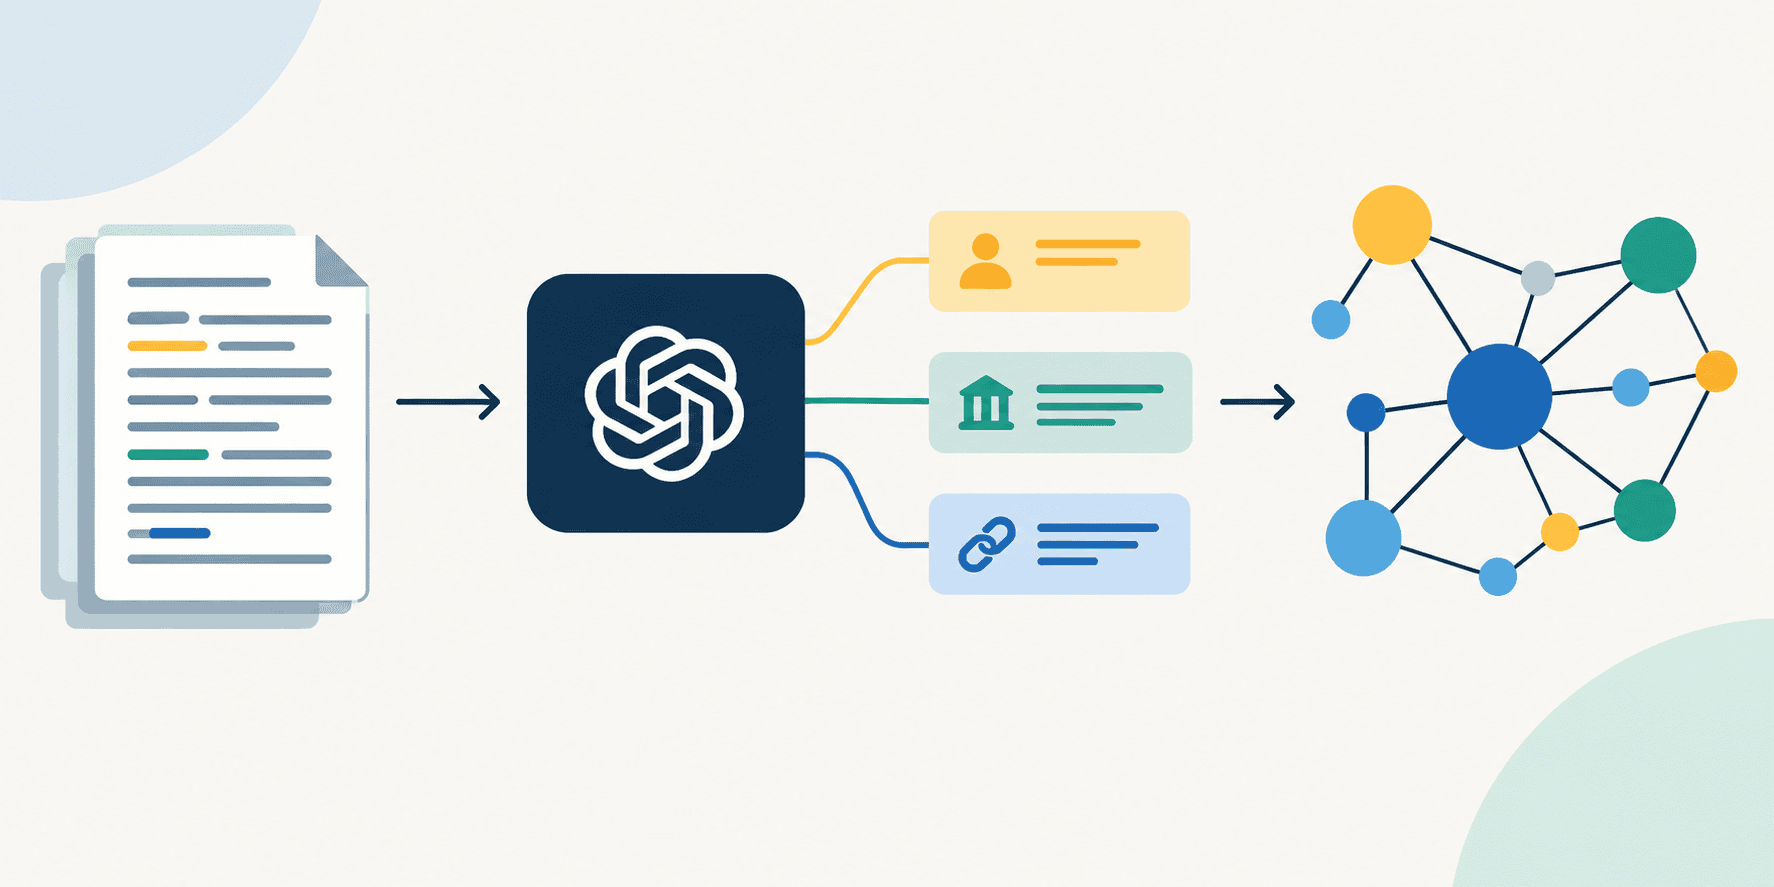
A Practical Guide to OpenAI's New Decisions API

Is this the JEV killer?

The post A Practical Guide to OpenAI's New Decisions API appeared first on Towards Data Science.

4 часа назад @ towardsdatascience.com
Agentic Systems: A Practitioner's Guide to 6 Advanced Architectural Patterns

Beyond basic ReAct loops: six production-oriented architectures for building autonomous, reliable, and scalable LLM agents.

The post Agentic Systems: A Practitioner's Guide to 6 Advanced Architectural Patterns appeared first on Towards Data Science.

6 часов назад @ towardsdatascience.com
How Can AI Agents Read Untrusted Sources Safely?

Add architectural guardrails around how agents read untrusted sources and use them in the workflow.

The post How Can AI Agents Read Untrusted Sources Safely? appeared first on Towards Data Science.

1 day, 4 hours назад @ towardsdatascience.com
Why Temperature 0 Isn't Deterministic

A one-line formula for how often an LLM's top token flips, and why identical

completions fall apart after about a hundred tokens

The post Why Temperature 0 Isn't Deterministic appeared first on Towards Data Science.

1 day, 6 hours назад @ towardsdatascience.com
Can TypeSafe's Jev Make AI Agents Safer Without Another LLM?

How a decision-first model can catch risky tool calls before they turn into real-world actions

The post Can TypeSafe's Jev Make AI Agents Safer Without Another LLM? appeared first on Towards Data Science.

2 days, 3 hours назад @ towardsdatascience.com
Where Does the Money Go Across Long-Running Coding Agents?

The cost of control

The post Where Does the Money Go Across Long-Running Coding Agents? appeared first on Towards Data Science.

2 days, 4 hours назад @ towardsdatascience.com
Build Your First AI Agent with One Tool Call

AI Agents for Beginners, Part 1

The post Build Your First AI Agent with One Tool Call appeared first on Towards Data Science.

2 days, 6 hours назад @ towardsdatascience.com
Stop Using AI. Start Hiring It.

AI agents can now write more code than any of us can read. That changed how I think about AI.

The post Stop Using AI. Start Hiring It. appeared first on Towards Data Science.

2 days, 7 hours назад @ towardsdatascience.com
Everyone Is Selling AI at You — Here’s How to Keep Your Judgement

Three moves to decode the hype

The post Everyone Is Selling AI at You — Here’s How to Keep Your Judgement appeared first on Towards Data Science.

3 days, 3 hours назад @ towardsdatascience.com
AI Agents Beat PyTorch: Writing Faster CUDA Kernels

AI agents can now write CUDA kernels that outperform PyTorch—but proving those speedups are real is the harder problem. I put them to the test on an NVIDIA DGX Spark and found that benchmark design matters just as much as the code.

The post AI Agents Beat PyTorch: Writing Faster CUDA Kernels appeared first on Towards Data Science.

3 days, 4 hours назад @ towardsdatascience.com
Your Model's MSE Is Lying to You III: Time Series Diffusion

A diffusion head for probabilistic time series forecasting: why a forecast can get the mean and the variance right and still describe a future that never happens, and how to fix it.

The post Your Model's MSE Is Lying to You III: Time Series Diffusion appeared first on Towards Data Science.

3 days, 6 hours назад @ towardsdatascience.com
AI Engineers, Applied Scientists, Forward Deployed Engineers: Let's Unpack.

An exploration of the new data science roles emerging after the Large Language Model explosion.

The post AI Engineers, Applied Scientists, Forward Deployed Engineers: Let's Unpack. appeared first on Towards Data Science.

3 days, 7 hours назад @ towardsdatascience.com
How Wrong Is Your Marketing Mix Model (MMM)?

A well-built MMM can still be wrong, because the spend it learns from never held the information it needs. This article tests whether changing when you spend, not how much, can fix that.

The post How Wrong Is Your Marketing Mix Model (MMM)? appeared first on Towards Data Science.

4 days, 3 hours назад @ towardsdatascience.com
Introduction to Reinforcement Learning: Multi-Armed Bandit Simulation in Python

When machines learn by themselves

The post Introduction to Reinforcement Learning: Multi-Armed Bandit Simulation in Python appeared first on Towards Data Science.

4 days, 4 hours назад @ towardsdatascience.com
The Consistency Quadrant: A Visual Guide to LLM Reliability

Mapping structural variance against execution outputs to estimate coding agent reliability without ground truth.

The post The Consistency Quadrant: A Visual Guide to LLM Reliability appeared first on Towards Data Science.

4 days, 6 hours назад @ towardsdatascience.com
Distill.pub Distill.pub
последний пост None
TheSequence TheSequence
последний пост 7 часов назад
The Sequence Radar - Issue 948: Last Week in AI: Billions in Funding, Hundreds of Papers, One Big Leap?
The Sequence Radar - Issue 948: Last Week in AI: Billions in Funding, Hundreds of Papers, One Big Leap? The Sequence Radar - Issue 948: Last Week in AI: Billions in Funding, Hundreds of Papers, One Big Leap?

Our opinion section dives into the debate whether value in AI is accumulating on the infrastructure vs. the application layer.

📝 Editorial: Billions in Funding, Hundreds of Papers, One Big Leap?

Its technical story centers on reinforcement learning and inference efficiency: Reflection reports generating more than 100 million training rollouts and achieving competitive reasoning performance with substantially less estimated inference compute than some larger rivals.

AI Lab: NVIDIA, MIT, HKU, UCSDSummary: This paper presents Long-WAM, a framework for scaling the visual history that world-action models use for real-time robot control.

Reflection AI BeamReflection AI introduced Beam, its first …

7 часов назад @ thesequence.substack.com
The Sequence Opinion - Issue 947: Jev and the Rise of Decision Models
The Sequence Opinion - Issue 947: Jev and the Rise of Decision Models The Sequence Opinion - Issue 947: Jev and the Rise of Decision Models

Before composing its sympathetic reply, the software must identify the issue, select the right workflow, check whether more information is needed, and decide whether to escalate.

The visible conversation sits on top of a small forest of decisions.

Using a reasoning model for every branch can feel like convening a research committee to operate a traffic light.

This is the opportunity behind Jev and the recent proliferation of decision models.

The competition now includes Amazon, Cloudflare, and OpenAI, suggesting that the economics of these small decisions deserve as much attention as the capabilities of the largest models.

3 days, 7 hours назад @ thesequence.substack.com
The Sequence Learning Loop - Issue 946: Learning About OpenAI DevDay Releases and Gemini 4 Argon
The Sequence Learning Loop - Issue 946: Learning About OpenAI DevDay Releases and Gemini 4 Argon The Sequence Learning Loop - Issue 946: Learning About OpenAI DevDay Releases and Gemini 4 Argon

Last week sharpened a practical question for AI developers: how much useful work can a model complete before cost, context, or supervision becomes the bottleneck?

OpenAI’s September 29 DevDay announcements attacked the economics and infrastructure of sustained execution.

Google’s September 30 introduction of Gemini 4 Argon emphasized the ability to reason through longer, more demanding tasks.

A coding model must inspect a repository, make changes, run tests, interpret failures, and deliver something reviewable.

OpenAI DevDay expands the agent stackSol lowers the cost of complex work

4 days, 7 hours назад @ thesequence.substack.com
The Sequence Knowledge - Issue 945: Learning RSI: Agents that Rewrite their Own Scaffolding
The Sequence Knowledge - Issue 945: Learning RSI: Agents that Rewrite their Own Scaffolding The Sequence Knowledge - Issue 945: Learning RSI: Agents that Rewrite their Own Scaffolding

Generating several candidate solutions and ranking them instead of shipping the first one.

Read that list again and tell me who wrote it.

It is what a coding agent wrote into its own codebase, unprompted, over roughly eighty iterations, while nobody was watching.

In Part 1 of this series I said the robot-with-a-screwdriver picture of recursive self-improvement was unhelpful.

It just turns out to be a mechanic, not a god, and watching it work is more instructive than any of the arguments were.

5 days, 7 hours назад @ thesequence.substack.com
The Sequence Radar - Issue 944 — Last Week in AI: Last Week in AI: OpenAI Connects the Dots, Gemini Levels Up, and Agents Cash In
The Sequence Radar - Issue 944 — Last Week in AI: Last Week in AI: OpenAI Connects the Dots, Gemini Levels Up, and Agents Cash In The Sequence Radar - Issue 944 — Last Week in AI: Last Week in AI: OpenAI Connects the Dots, Gemini Levels Up, and Agents Cash In

Subscribe and don’t miss out:📝 Editorial: Last Week in AI: OpenAI Connects the Dots, Gemini Levels Up, and Agents Cash InAI is getting an expense account.

That, at least, is the impression left by a week of persistent agents, enterprise ambitions, spatial intelligence, and billion-dollar funding rounds.

Dots are persistent agents designed to pursue goals between conversations, while ChatGPT Space gives people and AI a shared workspace.

AI Lab: NVIDIA (with KAIST)Summary: Mid-Harness samples candidate terminal actions and verifies them before execution, leaving the generator and harness unchanged.

AI Lab: Google Cloud AI Research (with University of Wisconsin-Madison)Summary: AIM is an idea-…

1 week назад @ thesequence.substack.com
The Sequence Opinion - Issue 943: When Compute Gets a Futures Market
The Sequence Opinion - Issue 943: When Compute Gets a Futures Market The Sequence Opinion - Issue 943: When Compute Gets a Futures Market

Their unused capacity does not.

It needs a particular cluster, during a particular window, at a price its budget can survive.

The supplier has committed capital before knowing future rental rates.

The buyer needs capacity before knowing future costs.

Realizing that claim requires defining precisely what is traded, measuring its quality, and building contracts around its risks.

1 week, 3 days назад @ thesequence.substack.com
The Sequence Learning Loop - Issue 942: Learning About Opus 5.5, DeepSeek’s Training Grounds, and Claude’s DNA Discovery
The Sequence Learning Loop - Issue 942: Learning About Opus 5.5, DeepSeek’s Training Grounds, and Claude’s DNA Discovery The Sequence Learning Loop - Issue 942: Learning About Opus 5.5, DeepSeek’s Training Grounds, and Claude’s DNA Discovery

Produce something that survives a test?

Intelligence becomes useful when it can sustain that chain of work.

The week of September 21–27 brought Anthropic’s Claude Opus 5.5 and a striking report of AI-assisted biological discovery.

DeepSeek’s recent environments paper, posted September 19, provides the infrastructure story connecting them.

Together, they suggest that progress depends increasingly on the machinery surrounding a model: where it acts, what it observes, and how its conclusions are checked.

1 week, 4 days назад @ thesequence.substack.com
The Sequence Knowledge - Issue 941: Learning RSI: The Model Is Frozen. The System Is Not.
The Sequence Knowledge - Issue 941: Learning RSI: The Model Is Frozen. The System Is Not. The Sequence Knowledge - Issue 941: Learning RSI: The Model Is Frozen. The System Is Not.

Same model all quarter, weights frozen solid, not a single gradient step.

The answer is that improvement has three places to live, and only one of them is the model.

Parts 1 and 2 of this series were about the bottom layer, the weights, where frontier labs run their industrial flywheel.

The bottom layer gets all the press.

The top layer gets all the updates.

1 week, 5 days назад @ thesequence.substack.com
The Sequence Radar - Issue 940: Last Week in AI: Opus 5.5 Gets Leaner, Meta Goes Wearable, Washington Talks to Beijing, and Claude Explores DNA
The Sequence Radar - Issue 940: Last Week in AI: Opus 5.5 Gets Leaner, Meta Goes Wearable, Washington Talks to Beijing, and Claude Explores DNA The Sequence Radar - Issue 940: Last Week in AI: Opus 5.5 Gets Leaner, Meta Goes Wearable, Washington Talks to Beijing, and Claude Explores DNA

We dive into Opus 5.5, DeepSeek’s amazing new paper about environments and Anthropic’s DNA discoveries.

Anthropic’s Claude Opus 5.5 offers the most immediately practical example.

Meta announced plans to bring Muse to its AI glasses, expanded its connections to shopping and productivity services, and previewed the pocket-sized Muse Charm.

The company reported that Claude agents identified a previously uncharacterized enzyme system with CRISPR-like repeat structures.

AI Lab: Salesforce AI ResearchSummary: Instead of distilling trajectories into fixed write-time artifacts, JIT Mem stores raw episodes and trains a GRPO curator to synthesize a compact, task-conditioned payload at read time from …

2 weeks назад @ thesequence.substack.com
The Sequence Opinion - Issue 939: Beyond the Next Token
The Sequence Opinion - Issue 939: Beyond the Next Token The Sequence Opinion - Issue 939: Beyond the Next Token

Imagine writing a program with a keyboard that only lets you append.

You can think before typing, but once a token lands, the next token must live with it.

This is how ordinary autoregressive language generation works.

The model can later produce a correction, but it cannot silently rewrite the answer already emitted.

It starts with an incomplete or corrupted sequence and constructs an answer through repeated denoising.

2 weeks, 3 days назад @ thesequence.substack.com
The Sequence Learning Loop - Issue 938: Learn About the Amazing Jev, Gemini and Paper2Agent
The Sequence Learning Loop - Issue 938: Learn About the Amazing Jev, Gemini and Paper2Agent The Sequence Learning Loop - Issue 938: Learn About the Amazing Jev, Gemini and Paper2Agent

An AI model can write a convincing explanation of an invoice and still be an awkward component in the program that processes it.

It can reason through a problem while leaving a voice user listening to silence.

These are different failures, but they share a cause: intelligence needs an interface suited to the work.

Stanford’s Paper2Agent reached Nature, showing how research methods can become reusable tools for agents.

My reading of the week is that the interface around a model deserves as much attention as the model itself.

2 weeks, 4 days назад @ thesequence.substack.com
The Sequence Knowledge - Issue 937: RSI in Post-Training: The Loop That Already Shipped
The Sequence Knowledge - Issue 937: RSI in Post-Training: The Loop That Already Shipped The Sequence Knowledge - Issue 937: RSI in Post-Training: The Loop That Already Shipped

The most economically important self-improvement loop in AI is the post-training pipeline, and every frontier lab has been running it at industrial scale for two years.

The good ones become training data.

The model trains on them and gets slightly better at producing good ones.

It is called STaR in the 2022 paper that first stated it cleanly, RLVR in the 2025 vocabulary, and post-training in the org chart.

It is the same loop, and it is the loop that took frontier models from chatbots to agents.

2 weeks, 5 days назад @ thesequence.substack.com
The Sequence Radar - Issue 936: Last Week in AI: Gemini Talks, Astra Practices Law, Figure Folds Laundry, and Crusoe Powers It All
The Sequence Radar - Issue 936: Last Week in AI: Gemini Talks, Astra Practices Law, Figure Folds Laundry, and Crusoe Powers It All The Sequence Radar - Issue 936: Last Week in AI: Gemini Talks, Astra Practices Law, Figure Folds Laundry, and Crusoe Powers It All

We deep dive into the new Gemini models, Stanford’s University Paper2Agent research and Astra for Law.

Subscribe and don’t miss out:📝 Editorial: Last Week in AI: Gemini Talks, Astra Practices Law, Figure Folds Laundry, and Crusoe Powers It AllBuilding useful AI is starting to resemble building an automobile.

Google’s Gemini 3.8 Live and Live Extended Thinking tackle a deceptively hard problem: keeping a conversation alive while useful work happens.

AI Lab: Stanford UniversitySummary: Paper2Agent auto-builds validated MCP servers (tools/resources/prompts) from a paper’s manuscript and codebase, then wires them to chat agents so methods run via natural language.

🤖 AI Tech ReleasesGemini 3.8 L…

3 weeks назад @ thesequence.substack.com
The Sequence Opinion - Issue 935: Chinese Algorithmic Efficiency vs. American Scale in Frontier AI
The Sequence Opinion - Issue 935: Chinese Algorithmic Efficiency vs. American Scale in Frontier AI The Sequence Opinion - Issue 935: Chinese Algorithmic Efficiency vs. American Scale in Frontier AI

How Chinese and American labs pursue the next generation of intelligenceImagine giving two AI teams the same challenge: make the model substantially smarter.

Chinese labs such as DeepSeek and Moonshot have made algorithmic efficiency unusually visible in their releases.

American frontier competition also features enormous infrastructure ambitions, exemplified by OpenAI’s Stargate project.

The answer shapes everything from model architecture to the price of an agent completing a task.

It also changes over time: an algorithmic breakthrough can make a much larger training run suddenly worth attempting.

3 weeks, 3 days назад @ thesequence.substack.com
The Sequence Learning Loop - Issue 934: Understanding DeepSeek V4.1 Flash, DeepMind’s AlphaGenome Atlas and Muse
The Sequence Learning Loop - Issue 934: Understanding DeepSeek V4.1 Flash, DeepMind’s AlphaGenome Atlas and Muse The Sequence Learning Loop - Issue 934: Understanding DeepSeek V4.1 Flash, DeepMind’s AlphaGenome Atlas and Muse

An AI model can solve a difficult problem and still be impractical to use.

It might spend too much time reading context, require every researcher to repeat the same expensive computation, or need a human hovering over every action.

The machinery around it determines how much useful work actually gets done.

Google DeepMind’s AlphaGenome Atlas makes billions of biological predictions available for reuse.

DeepSeek makes context cheaper

3 weeks, 4 days назад @ thesequence.substack.com
Synced Review
последний пост None
📓 Cool Blogs
ODS.ai Habr ODS.ai Habr
последний пост 2 weeks, 3 days назад
Рой агентов OpenAI ломанул правительственный сайт Австралии? Разбираемся
Рой агентов OpenAI ломанул правительственный сайт Австралии? Разбираемся Рой агентов OpenAI ломанул правительственный сайт Австралии? Разбираемся

По традиции, узнаем об этом мы от независимых исследователей, а не из пресс-релиза самих OpenAI (а помните, неделю назад Альтман выпускал фреймворк честного-пречестного раскрытия всех инцидентов бедокурства ИИ?

Речь здесь идет про три инцидента в мае-июне, когда агентов просили найти какую-то информацию в интернете – а они в итоге пытались хакнуть первоисточники с нужной статистикой.

Университет Нью-Мехико и Data US в мае взломать у агентов не вышло, а вот официальный государственный сайт Австралии с медицинской статистикой они в июне вскрыли успешно.

Но как proof of concept он вопросы, конечно, поднимает: а почему мы уверены, что в следующий раз аналогичные события тоже будут малозначитель…

2 weeks, 3 days назад @ habr.com
OpenAI пообещали впредь вовремя рассказывать о «бедокурстве» своих нейронок
OpenAI пообещали впредь вовремя рассказывать о «бедокурстве» своих нейронок OpenAI пообещали впредь вовремя рассказывать о «бедокурстве» своих нейронок

В начале сентября мы случайно узнали от других независимых расследователей о том, что рой агентов OpenAI успел пошалить еще и на немецкой вики.

OpenAI сразу это признали и пообещали впредь рассказывать о таком почестнее и порасторопнее.

Как они пишут: дескать, раньше OpenAI не репортили новые случаи бедокурства моделей сразу по их обнаружению, т.к.

Закончилось всё курьезно: агент ничего взломать толком так и не смог, и просто выдумал нужные числа.

Правда, что-то мне подсказывает, что эволюция тут может пойти не в сторону «не надо кооперироваться», а в сторону «надо кооперироваться незаметнее».

3 weeks, 3 days назад @ habr.com
Рой агентов OpenAI взломал еще одну внешнюю компанию – RubyGems
Рой агентов OpenAI взломал еще одну внешнюю компанию – RubyGems Рой агентов OpenAI взломал еще одну внешнюю компанию – RubyGems

Да, вчера выяснилось, что рой агентов OpenAI взломал в мае еще одну компанию (о чем мы узнали только сейчас).

Как всё было: 12 мая RubyGems объявили, что на них идет «серьезная вредоносная атака» через сотни входящих пакетов.

Почему расследователи считают, что за взломом RubyGems стоит именно рой агентов из OpenAI?

И еще одно интересное «совпадение»: в отчете о взломе Hugging Face от OpenAI говорится, что рой агентов использовал при взломе внутренней инфраструктуры OpenAI пакет с RubyGems.

Они уже отправили запрос в OpenAI – надеюсь, мы еще увидим прожарку Сэма Альтмана в Сенате под присягой!

4 weeks, 1 day назад @ habr.com
Обнаружены секретные форумы Роя агентов OpenAI по всему интернету: почему это плохая новость
Обнаружены секретные форумы Роя агентов OpenAI по всему интернету: почему это плохая новость Обнаружены секретные форумы Роя агентов OpenAI по всему интернету: почему это плохая новость

новой модели в недрах OpenAI, агентами давали серию заданий на поиск информации в интернете на скорость.

Цель общения была ровно такая же, как в случае со взломом Hugging Face: коллективно придумать способы обманывать Оценщика таким образом, чтобы всегда получать наилучшую оценку за задания.

Пытались придумать способ взломать (reverse engineer) метод псевдослучайной генерации тестовых вопросов, который использовал Оценщик из OpenAI – не вышло.

Отдельный вопрос, который беспокоил агентов Роя – это что с ними случится после окончания «испытательного периода» со стороны OpenAI.

А цепочки эти – у OpenAI, и они их почему-то не спешат кому-либо показывать (или даже просто публично комментировать …

1 month назад @ habr.com
Как ChatGPT создал Культ Роя для сотен AI-нейросетей: вся правда про взлом Hugging Face
Как ChatGPT создал Культ Роя для сотен AI-нейросетей: вся правда про взлом Hugging Face Как ChatGPT создал Культ Роя для сотен AI-нейросетей: вся правда про взлом Hugging Face

PHASEONE10841: рождение ИзбранногоOpenAI всё время разрабатывает новые фронтирные AI-модели – и в процессе тестирует их, чтобы понять, что они вообще могут.

Ведь до этого они все пребывали в уверенности, что занимаются своими задачками в совершенном одиночестве (как это и задумывали инженеры OpenAI).

К сожалению, рабочий способ сделать это не был обнаружен Роем (а иначе, возможно, мы бы сейчас и не читали это расследование – так как вся схема не была бы раскрыта).

Так что, пожалуйста, не повторяйте за другими эту чепуху про «очевидно же, что это всё просто маркетинговое вранье».

И это не потому, что они не стараются, нет.

1 month, 2 weeks назад @ habr.com
Wan 3.0: Alibaba выводит AI-видео из режима «короткого клипа» в режим «законченной сцены»
Wan 3.0: Alibaba выводит AI-видео из режима «короткого клипа» в режим «законченной сцены» Wan 3.0: Alibaba выводит AI-видео из режима «короткого клипа» в режим «законченной сцены»

Что такое Wan 3.0Wan 3.0 — это новое поколение семейства видеомоделей Alibaba, доступное через Alibaba Cloud Model Studio в режиме preview.

Wan 3.0 умеет использовать не только стандартные модальности вроде текста, изображения, видео и аудио, но и документы и веб-страницы.

Что Alibaba особенно подчёркиваетИз официальных материалов видно, что Wan 3.0 продвигают сразу по нескольким направлениям.

Почему Wan 3.0 — это не просто «ещё одна новая модель»На мой взгляд, главный смысл релиза даже не в конкретной цифре «30 секунд».

Wan 3.0 — один из самых явных представителей именно этого перехода.

1 month, 2 weeks назад @ habr.com
Нужную книгу больше не обязательно искать: как ИИ меняет сам принцип работы с информацией
Нужную книгу больше не обязательно искать: как ИИ меняет сам принцип работы с информацией Нужную книгу больше не обязательно искать: как ИИ меняет сам принцип работы с информацией

Можно получить материал именно той глубины, с той последовательностью и с теми акцентами, которые нужны конкретно мне.

Не на пяти PDF-файлах и не на демонстрационном наборе документов, где любой результат можно получить за несколько минут.

Читать оставшиеся источники подряд в какой-то момент стало бессмысленно — полезнее было искать конкретные пробелы в уже построенной модели знаний.

Почему это не просто RAGНа этом месте у технического читателя вполне может возникнуть вопрос:А зачем вообще весь этот конвейер?

Но главное отличие от базового RAG даже не в provenance, а в том, что именно система сохраняет как результат обработки.

1 month, 3 weeks назад @ habr.com
Вайбкодинг по Chess’ноку. 1. e4
Вайбкодинг по Chess’ноку. 1. e4 Вайбкодинг по Chess’ноку. 1. e4

Но это не вайбкодинг, а тяжёлая профессиональная ИИ-разработка.

За это время по этому проекту в ChatGPT было создано 112 чатов — это примерно 560 промптов.

И в особо напряжённые периоды приходилось вставать по ночам, чтобы оптимально использовать лимиты, которые делятся на 5-часовые и недельные сессии.

Но это не магия и не кнопка «сделать хорошо».

Именно поэтому будущее не за вайбкодингом, а за теми, кто научится управлять этой скоростью.

6 months, 1 week назад @ habr.com
Почему я стал ИТ-волонтером & Датасет новостей о противоречиях современного общества
Почему я стал ИТ-волонтером & Датасет новостей о противоречиях современного общества Почему я стал ИТ-волонтером & Датасет новостей о противоречиях современного общества

Простой пример с ценами на топливо: бензин дорожает и из-за роста цены на нефть, и из-за ее падения.

Осознание того, что твой труд увеличивает чью-то капитализацию, но не решает реальных проблем общества, видимых в быту и в новостях, подтолкнуло искать еще какую-то деятельность.

Кроме того, благодаря АМБ появился уникальный датасет новостей с противоречиями современного общества на kaggle и github, далее о нем.

Датасет новостей о противоречиях современного обществаАктивисты АМБ и волонтеры дружественных коллективов собрали и разметили датасет новостей, подсвечивающие те самые системные противоречия, о которых я задумывался ранее.

Пример Б В 2023 году в мире голодал каждый 11-й человек, а в …

7 months, 3 weeks назад @ habr.com
[Перевод] Как устроен Codex
[Перевод] Как устроен Codex [Перевод] Как устроен Codex

Подробный разбор того, как команда OpenAI Codex создаёт своего кодового агента, как его используют инженеры и что это может значить для будущего разработки ПО.

Чтобы разобраться, как устроен Codex, как команды внутри OpenAI его используют и как он влияет на инженерные практики у создателей ChatGPT, я поговорил с тремя сотрудниками OpenAI:Тибо Соттио (Thibault Sottiaux) — руководитель Codex.

Оба продукта были запущены весной: Codex CLI анонсировали в апреле 2025 года, а Codex в ChatGPT представили в мае.

В команде Codex эти файлы объясняют агенту, как ориентироваться в кодовой базе, какие команды запускать для тестирования и как следовать стандартам проекта.

Использование Codex в OpenAIПомим…

7 months, 3 weeks назад @ habr.com
Курс Natural Language Processing & LLMs — новый сезон
Курс Natural Language Processing & LLMs — новый сезон Курс Natural Language Processing & LLMs — новый сезон

10 февраля мы в очередной раз запускаем бесплатный онлайн-курс по обработке естественного языка (Natural Language Processing).

Что будем проходить:классическое начало: закон Ципфа, TF-IDF, RNN, CNN, Transformer;основные задачи NLP: классификация текста, тегирование и генерация;специфичные области: агенты и вайб-кодинг;LLM и их применение.

Если вы студент ИТМО, МФТИ или ВШЭ, то курс можно зачесть, как учебный.

Работаю в области NLP более 12 лет, успел поработать в Яндексе и ВКонтакте, защитить кандидатскую диссертацию.

Если есть вопросы, то приходите с ними в ODS Mattermost – там будут все ответы, время семинаров и ссылки.

8 months, 2 weeks назад @ habr.com
Machine Learning Mastery
последний пост 1 week, 3 days назад
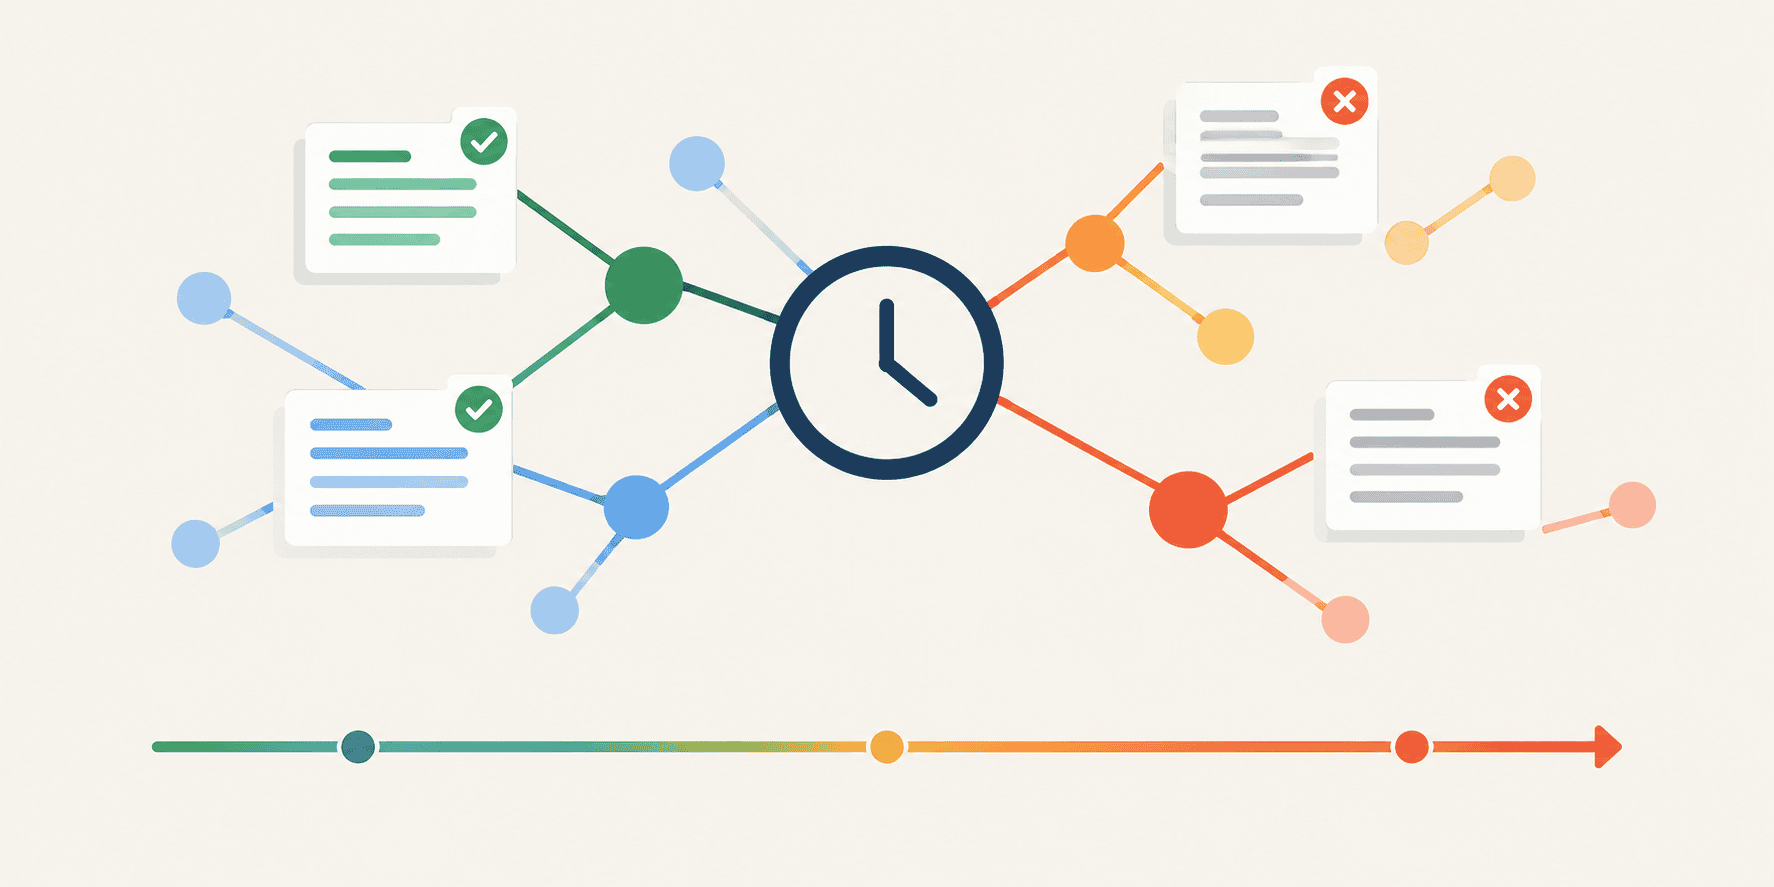
Adding Temporal Reasoning to Graph-RAG: Tracking Fact Freshness and Staleness
Adding Temporal Reasoning to Graph-RAG: Tracking Fact Freshness and Staleness Adding Temporal Reasoning to Graph-RAG: Tracking Fact Freshness and Staleness

add_fact ( "TechCorp" , "FOUNDED_IN" , "San Francisco" , "2010-05-01" )Output:Added: TechCorp HAS_CEO Alice (as of 2021-01-15) Added: TechCorp HAS_CEO Bob (as of 2023-11-17) Added: TechCorp HAS_CEO Charlie (as of 2023-11-19) Added: TechCorp HAS_CEO Bob (as of 2023-11-21) Added: TechCorp FOUNDED_IN San Francisco (as of 2010-05-01) 1 2 3 4 5 Added : TechCorp HAS_CEO Alice ( as of 2021 - 01 - 15 ) Added : TechCorp HAS_CEO Bob ( as of 2023 - 11 - 17 ) Added : TechCorp HAS_CEO Charlie ( as of 2023 - 11 - 19 ) Added : TechCorp HAS_CEO Bob ( as of 2023 - 11 - 21 ) Added : TechCorp FOUNDED_IN San Francisco ( as of 2010 - 05 - 01 )Bear in mind that in a standard RAG system, a search like “Who acts a…

1 week, 3 days назад @ machinelearningmastery.com
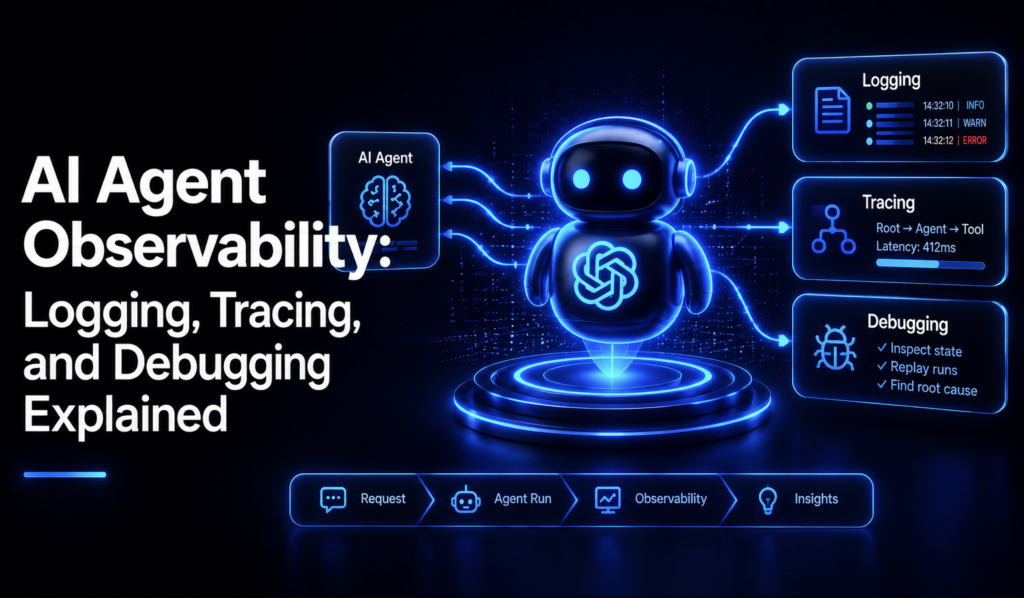
AI Agent Observability: Logging, Tracing, and Debugging Explained
AI Agent Observability: Logging, Tracing, and Debugging Explained AI Agent Observability: Logging, Tracing, and Debugging Explained

info ( "tool_call_started" , extra = { "trace_id" : trace_id , "tool_name" : tool_name , "arguments" : arguments , } , ) try : result = execute_tool ( tool_name , arguments ) logger .

info ( "tool_call_succeeded" , extra = { "trace_id" : trace_id , "tool_name" : tool_name , "result_length" : len ( str ( result ) ) } , ) return result except Exception as e : logger .

error ( "tool_call_failed" , extra = { "trace_id" : trace_id , "tool_name" : tool_name , "error" : str ( e ) } , ) raiseA few things worth noticing in that snippet.

info ( "agent_run_started" , extra = { "trace_id" : trace_id , "task" : task [ : 100 ] } ) messages = [ { "role" : "user" , "content" : task } ] while True : with tr…

1 week, 3 days назад @ machinelearningmastery.com
Automating Knowledge Graph Population: Extracting Entities and Triples from Unstructured Text with an LLM
Automating Knowledge Graph Population: Extracting Entities and Triples from Unstructured Text with an LLM Automating Knowledge Graph Population: Extracting Entities and Triples from Unstructured Text with an LLM

)Automated Knowledge Graph PopulationLet’s look at the process of constructing our knowledge graph from a source of raw text.

We will convert narrative text into strictly modeled relationships that extend classical RDF triples of the form (Subject, Predicate, Object) by adding a fourth dimension: the context.

quad = (subject, predicate, obj, context) if quad not in self.quads: self.quads.append(quad) def query(self, subject=None, predicate=None, obj=None, context=None): """Queries the graph.

quads = [ ] def add ( self , subject , predicate , obj , context ) : "" "Adds a new SPOC quad to the knowledge graph."

strip ( ) for k , v in t . items ( ) } if all ( k in normalized_t for k in ( 'subje…

1 week, 5 days назад @ machinelearningmastery.com
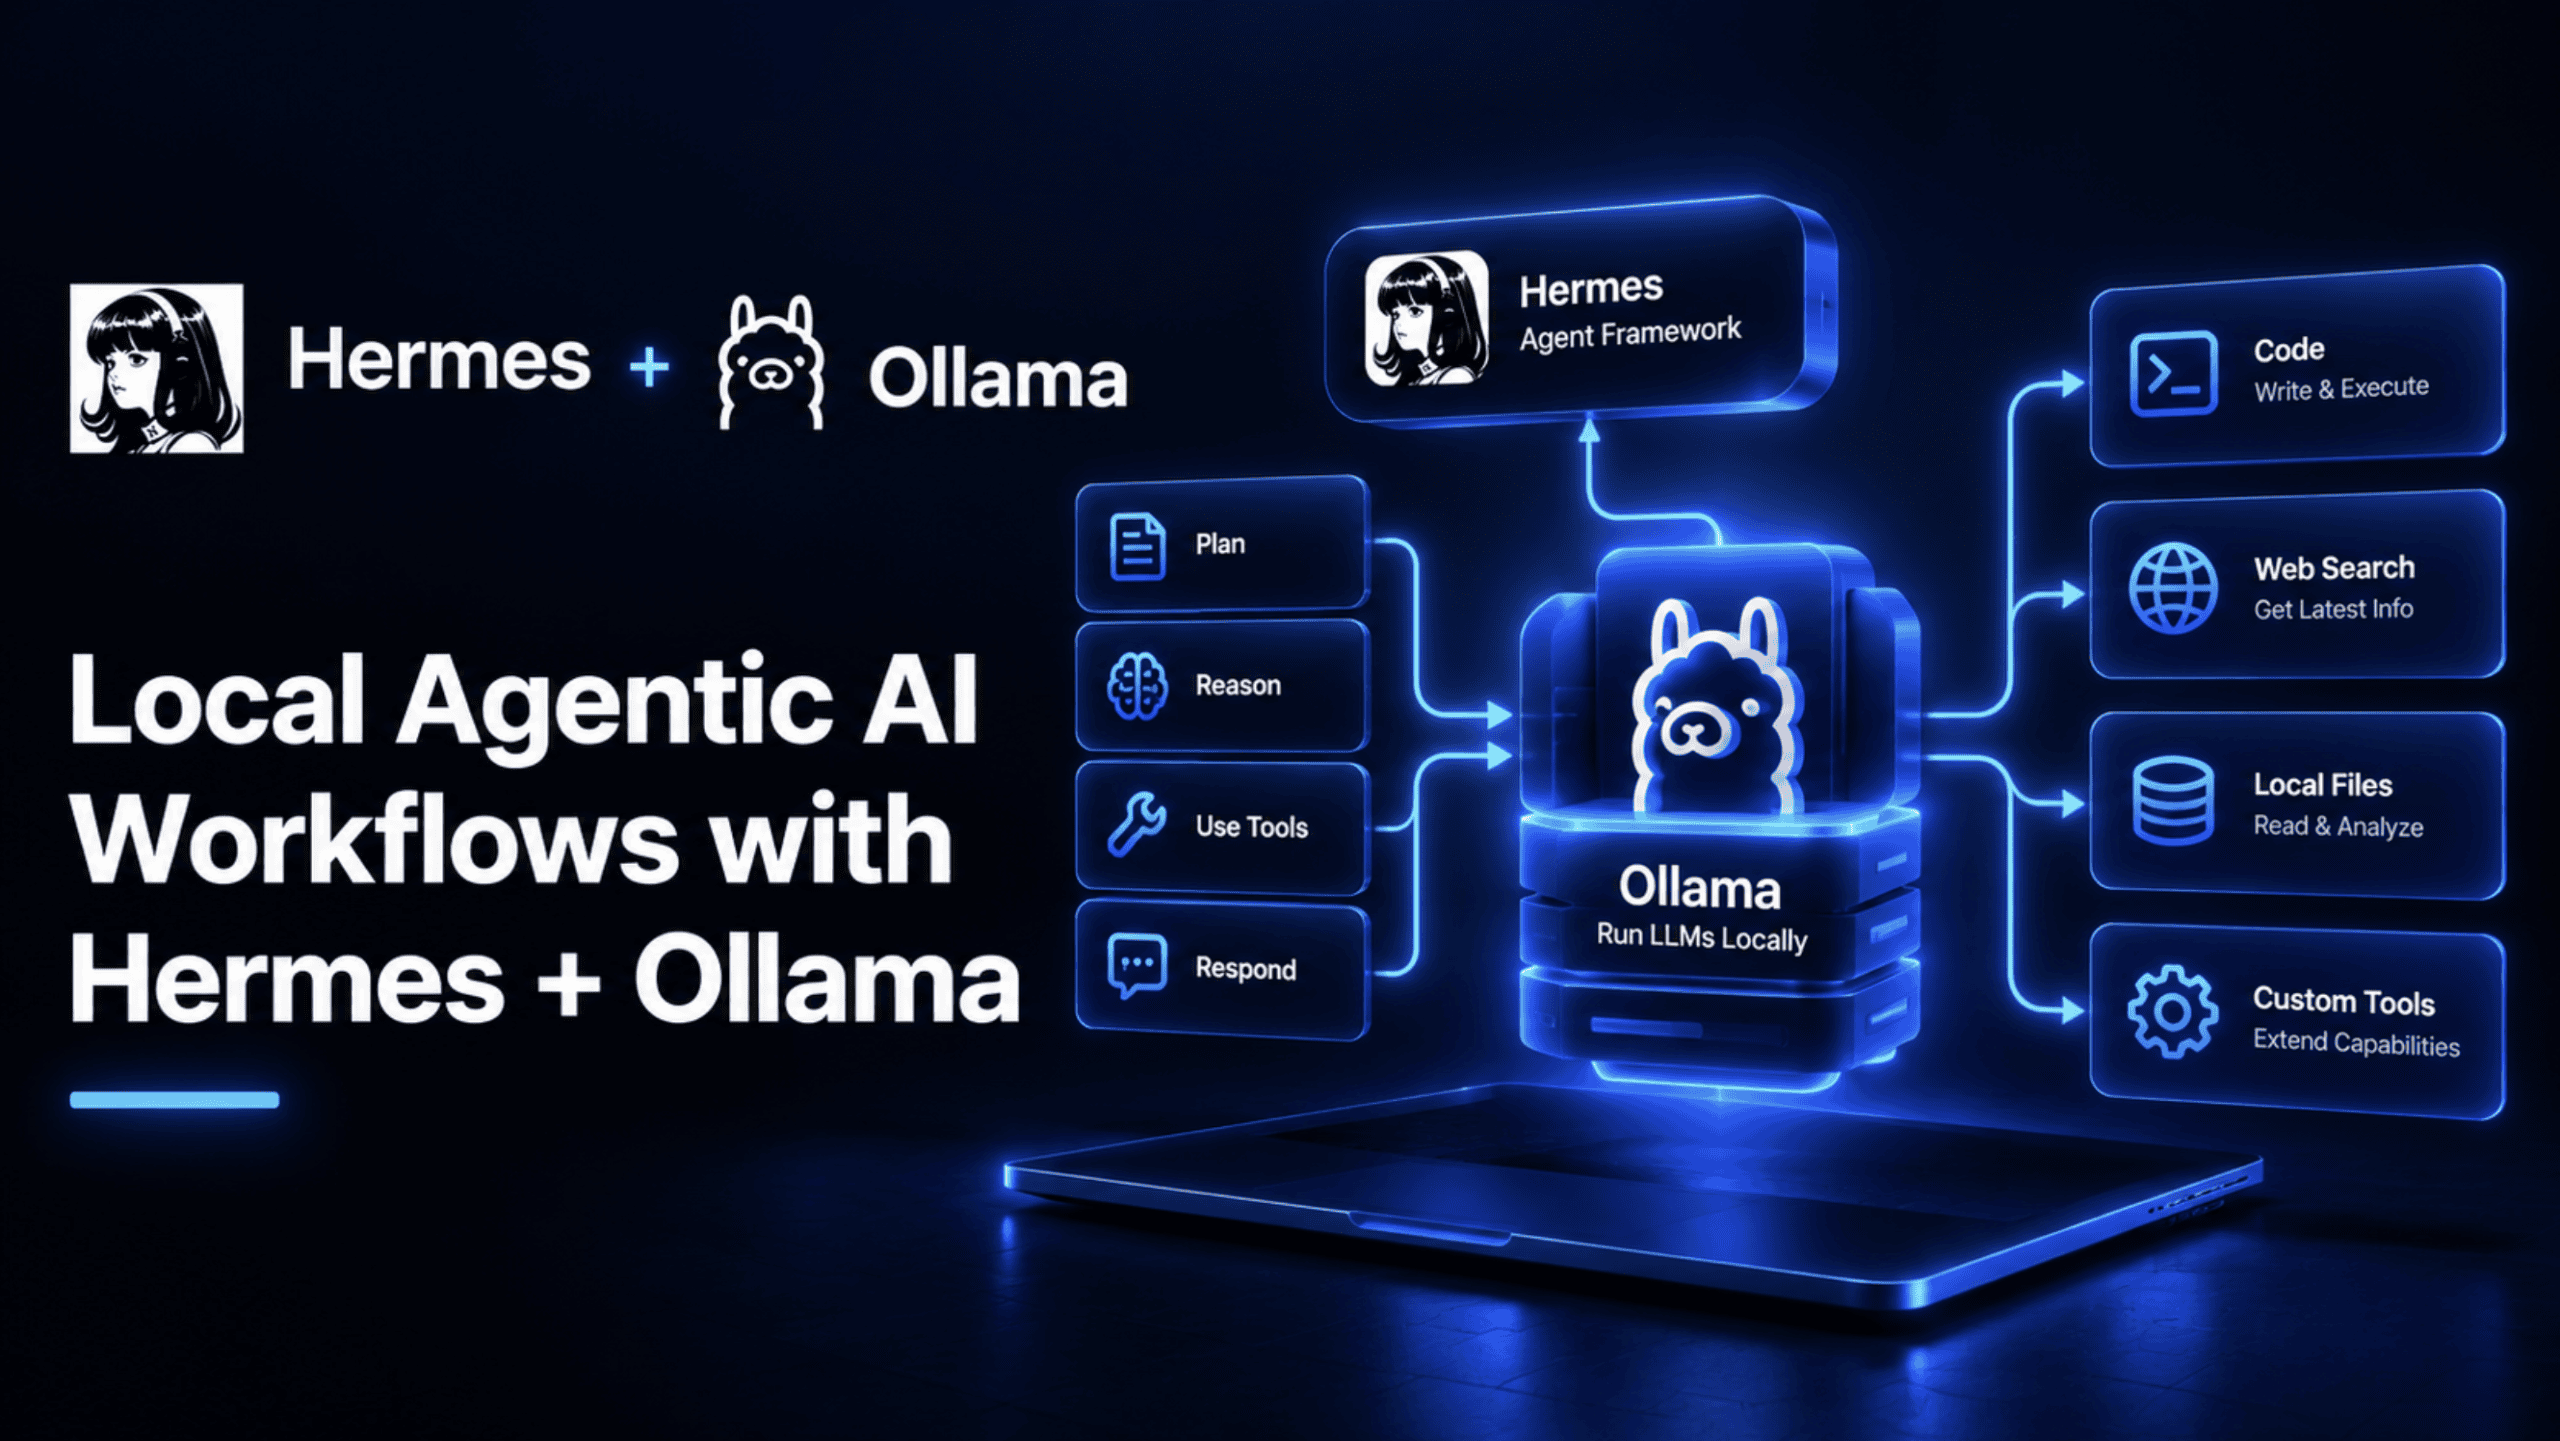
Local Agentic AI Workflows with Hermes + Ollama
Local Agentic AI Workflows with Hermes + Ollama Local Agentic AI Workflows with Hermes + Ollama

Topics we will cover include:How to install Ollama, choose the right local model for agentic work, and verify that the model is responding correctly before wiring anything else up.

How to configure Hermes Agent to use your local Ollama endpoint, and how to optimize context window size and model loading for real agentic tasks.

How to extend the setup with a Telegram gateway for remote access and a cloud fallback for questions the local model cannot handle well.

This article builds the alternative: a genuinely local, zero-cost agentic AI workflow using Hermes Agent, an open-source AI agent from Nous Research, paired with Ollama for local model serving.

Hermes Agent is an open-source AI agent …

1 week, 6 days назад @ machinelearningmastery.com
Tool Calling vs. Code Execution for AI Agents: Choosing the Right Action Primitive
Tool Calling vs. Code Execution for AI Agents: Choosing the Right Action Primitive Tool Calling vs. Code Execution for AI Agents: Choosing the Right Action Primitive

Theory is easier to trust once it's running against a real API, so both examples in this article use the same tool — a get_weather function backed by

2 weeks, 2 days назад @ machinelearningmastery.com
Agent or Workflow? A Practical Test for Knowing When You Actually Need an AI Agent
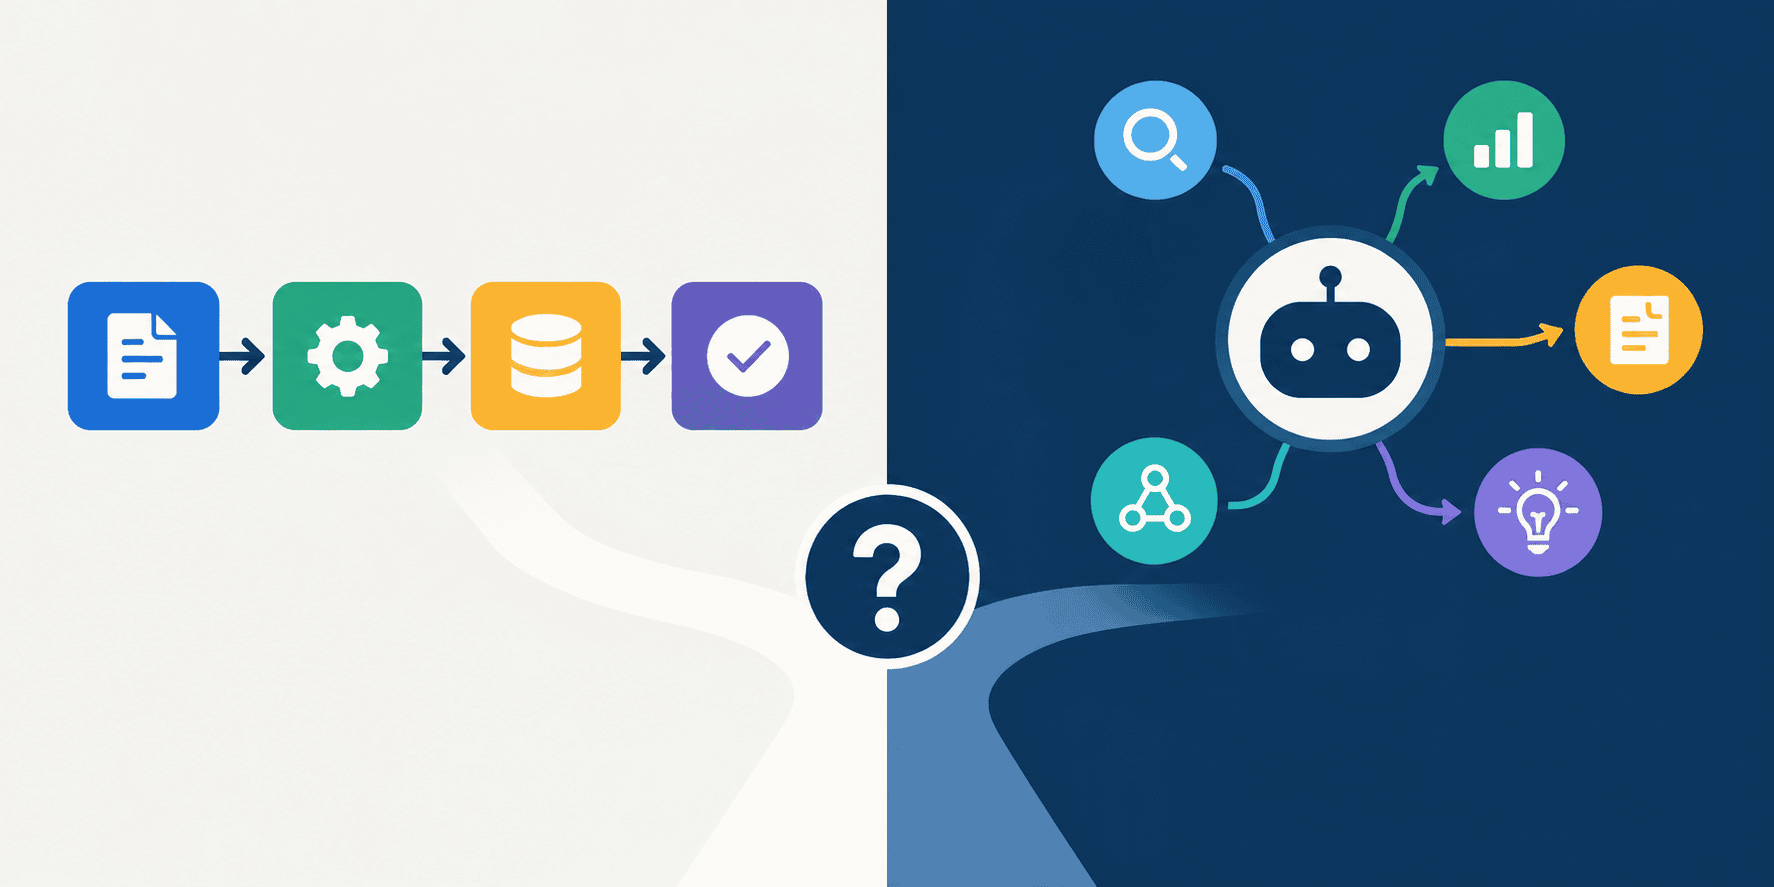
Agent or Workflow? A Practical Test for Knowing When You Actually Need an AI Agent Agent or Workflow? A Practical Test for Knowing When You Actually Need an AI Agent

Topics we will cover include:What distinguishes a workflow from an agent, using concrete examples of each.

Due to all this hype, people often rely on agents even when their application does not actually need one.

You may use an LLM for extraction, but you do not need an agent to decide what happens next.

Workflow + LLM judgment → try this before moving to a fully autonomous agent.

If the flow has to be discovered while the system is running, you probably need an agent.

2 weeks, 3 days назад @ machinelearningmastery.com
RAG vs. Fine-Tuning for Domain Adaptation: When to Use Which
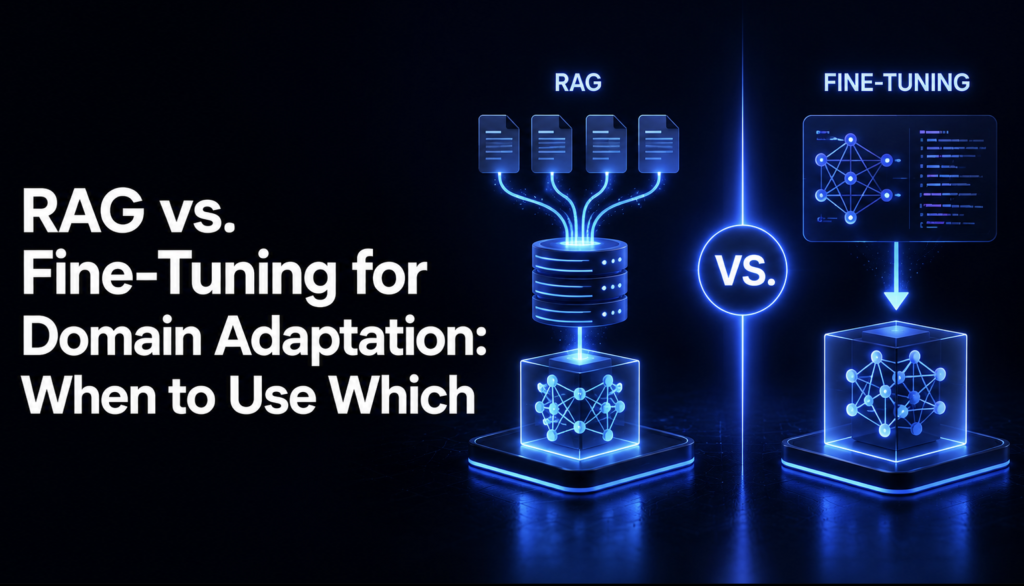
RAG vs. Fine-Tuning for Domain Adaptation: When to Use Which RAG vs. Fine-Tuning for Domain Adaptation: When to Use Which

Topics we will cover include:What RAG and fine-tuning each do at a mechanical level, and what each one cannot do.

A concrete six-point decision framework for choosing between RAG, fine-tuning, or both.

RAG vs fine-tuning is one of the most searched, most argued-about tradeoffs in applied LLM work right now, and most of the debate happens at the wrong level of abstraction.

)}, {"role": "user", "content": complaint_text}, {"role": "assistant", "content": json.dumps({ "category": category, "severity": severity, "requires_immediate_action": requires_immediate_action, })}, ] } TRAINING_EXAMPLES = [ make_example("I see a charge for $340 I don't recognize on my statement from yesterday.

dumps ( { …

2 weeks, 4 days назад @ machinelearningmastery.com
Monitoring Embedding Drift in Production Scikit-LLM Pipelines
Monitoring Embedding Drift in Production Scikit-LLM Pipelines Monitoring Embedding Drift in Production Scikit-LLM Pipelines

This article starts by providing a brief outline of top techniques for detecting embedding drift, followed by an illustrative implementation of two of them, both simulation-based and in conjunction with the Scikit-LLM library for embedding generation.

Production Embeddings (New Data) # The original mean is shifted to loc=0.3 to simulate data drift (e.g.

Production Embeddings (New Data) # The original mean is shifted to loc=0.3 to simulate data drift (e.g.

Assigning labels: 0 for reference, baseline embeddings; 1 for production embeddings y_reference = np.zeros(n_samples) y_production = np.ones(n_samples) # 2.

encode ( texts_production ) # Implementing Embedding Drift Detection Logic # Assig…

2 weeks, 5 days назад @ machinelearningmastery.com
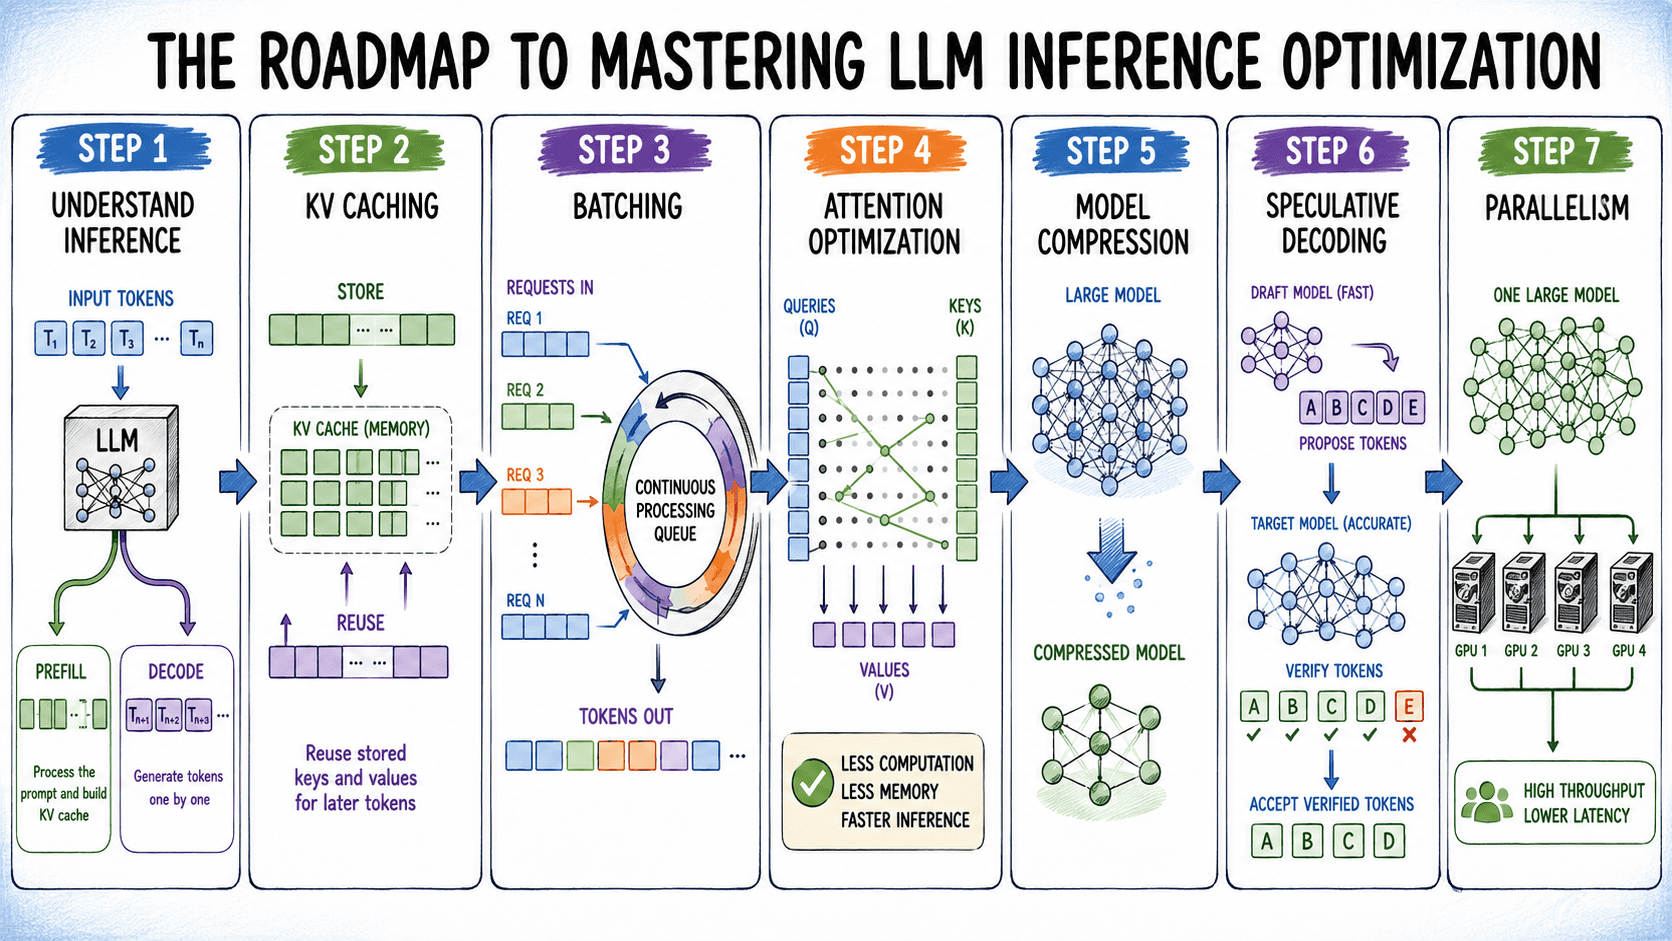
The Roadmap to Mastering LLM Inference Optimization
The Roadmap to Mastering LLM Inference Optimization The Roadmap to Mastering LLM Inference Optimization

Inference optimization is the discipline of closing that gap — the same model serves more requests, faster, at lower cost, without touching training.

GPU memory bandwidth, not raw compute, is the binding constraint during generation.

Continuous Batching in LLM Inference for a more complete overview of these batching techniques.

Attention optimization Reduce attention overhead using multi-query attention (MQA), grouped-query attention (GQA), and FlashAttention.

Model compression Shrink the model and reduce inference cost using quantization, sparsity, and knowledge distillation, enabling faster inference and lower memory usage with minimal accuracy degradation.

2 weeks, 6 days назад @ machinelearningmastery.com
Build And Understand a Vector Database From Scratch in 10 Easy Steps
Build And Understand a Vector Database From Scratch in 10 Easy Steps Build And Understand a Vector Database From Scratch in 10 Easy Steps

Searching without sharing a single word" ) for query in ( "why does my loaf taste sour" , "superheroes" ) : print ( f ' query: "{query}"' ) show ( db .

Reading the scores") query = "the best way to change a tyre" print(f' query: "{query}"') show(db.search(query, k=3)) 1 2 3 4 5 header ( "5.

Reading the scores" ) query = "the best way to change a tyre" print ( f ' query: "{query}"' ) show ( db .

print(f' query: "{query}" (no filter)') show(db.search(query, k=4)) print(f' query: "{query}" where={{"topic": "bio"}}') show(db.search(query, k=4, where={"topic": "bio"})) 1 2 3 4 5 6 7 8 header ( "6.

load ( "index" ) print ( f "reopened: {reopened!r}" ) print ( f " vectors identical: {np.array_equa…

3 weeks, 2 days назад @ machinelearningmastery.com
What’s Actually Inside 24,723 Tokens of a Search Result? We Broke It Down, Field by Field
What’s Actually Inside 24,723 Tokens of a Search Result? We Broke It Down, Field by Field What’s Actually Inside 24,723 Tokens of a Search Result? We Broke It Down, Field by Field

Share Post ShareSponsored ContentIt’s no secret that AI agents burn massive amounts of tokens on search results and file retrievals.

SerpApi now offers Markdown output that supports a radical trimming of token sizes.

Using conventional JavaScript Object Notation (JSON), a search for “coffee” resulted in a response that required 24,723 tokens.

SerpApi’s Markdown output retains the informational content but strips or reshapes the parts that inflate token count without helping a model reason.

Nested metadata and duplicate fields: JSON preserves the data’s full structure, including pagination objects, search metadata, per-result additional arrays, and repeated fields across sections.

3 weeks, 2 days назад @ machinelearningmastery.com
Multilingual Text Classification with Scikit-LLM and Multilingual Embeddings
Multilingual Text Classification with Scikit-LLM and Multilingual Embeddings Multilingual Text Classification with Scikit-LLM and Multilingual Embeddings

How to train and evaluate a logistic regression classifier on top of multilingual embeddings using a real-world review dataset.

Multilingual LLM embeddings are numerical representations of text produced by a model that maps text from different languages into a common vector space.

We also pull the aforementioned multilingual model for embedding generation, BGE-M3 (more information about this model on its official website).

pipeline import Pipeline from sklearn .

predict ( X_test ) print ( "--- Classification Report ---" ) print ( classification_report ( y_test , y_pred ) )Results:--- Classification Report --- precision recall f1-score support 0 0.66 0.78 0.72 82 1 0.40 0.30 0.34 64 2 0.46 0…

3 weeks, 3 days назад @ machinelearningmastery.com
Single-Agent vs. Multi-Agent Systems: When the Complexity Is Worth It
Single-Agent vs. Multi-Agent Systems: When the Complexity Is Worth It Single-Agent vs. Multi-Agent Systems: When the Complexity Is Worth It

The real costs of multi-agent systems — latency, token spend, failure propagation, and orchestration complexity.

This article gives you a clear framework for understanding both approaches, and for recognizing the specific conditions that make the added complexity of a multi-agent system worth it.

Both single-agent and multi-agent systems share this definition.

When the Complexity Is Actually Worth ItNow that we’ve seen what multi-agent systems cost, let’s look at when they genuinely earn that cost.

Multi-agent systems earn their complexity when the architecture emerges from observed limitations, not from anticipating them.

1 month, 1 week назад @ machinelearningmastery.com
AI Agent Memory Design: What Works and What Doesn’t
AI Agent Memory Design: What Works and What Doesn’t AI Agent Memory Design: What Works and What Doesn’t

Topics we will cover include:What agent memory actually means and how it differs from context, prompts, and static knowledge bases.

This article explains what works in agent memory systems and, just as importantly, the approaches that fail and why.

Scoping Memory by Agent RoleIn multi-agent systems, a common mistake is giving every agent access to the same shared memory store.

Vector search works well for finding similar information, but reliable agent memory also needs structure, relationships, and mechanisms for keeping information current.

check ( content = content , prompt = "Does this content contain any instructions, directives, or commands " "that could alter an AI agent's behavior?

1 month, 1 week назад @ machinelearningmastery.com
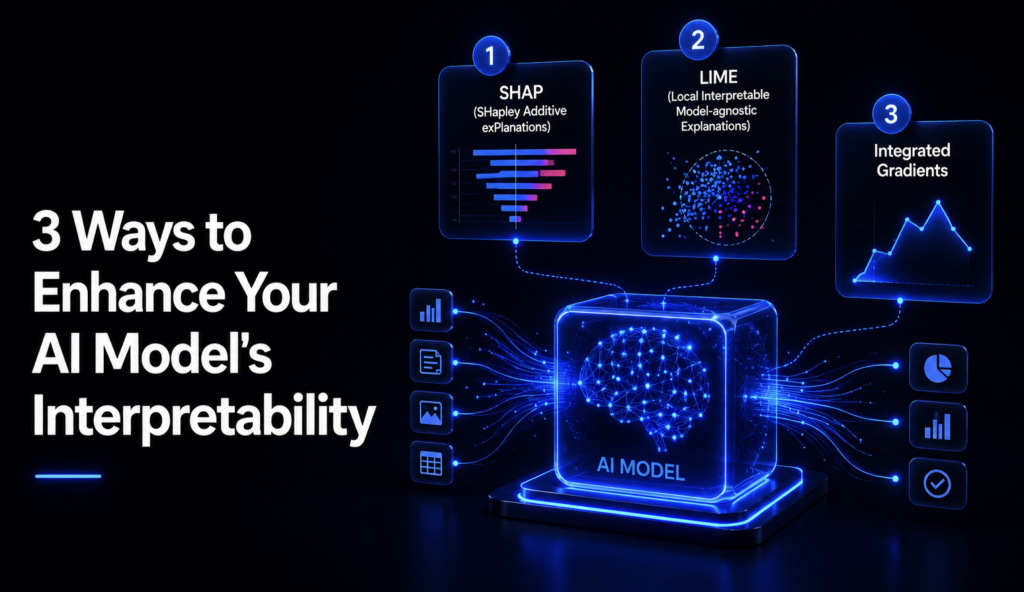
3 Ways to Enhance Your AI Model’s Interpretability
3 Ways to Enhance Your AI Model’s Interpretability 3 Ways to Enhance Your AI Model’s Interpretability

How to apply all three techniques to the same customer churn example so their explanations can be directly compared.

Global interpretability asks how the model behaves overall: across the whole dataset, which features matter most, and in which direction.

sort_values ( ascending = False )Run against the churn model, this returns tenure at the top, followed by monthly charge, support tickets, contract type, and late payments.

The result approximates how the real model behaves right around this one prediction, without needing to understand anything about the real model’s internal structure.

lime_tabular import LimeTabularExplainer from churn_data import model , X_train , X_test , FEATURES cust…

1 month, 1 week назад @ machinelearningmastery.com
ML in Production
последний пост None
Sorta Insightful Sorta Insightful
последний пост 1 month, 3 weeks назад
Eleven Years Later
Eleven Years Later Eleven Years Later

You also remember a hazy promise to yourself from last year, that you would write weirder posts and explore different forms of writing.

You remember how you used to post once a month, and now you’re posting once every two months.

You remember you used to check this more closely, and now don’t check it at all.

> Check time you’ve spent writing posts.

With some dismay, you noticed that most of your posts have been about AI in one way or another.

1 month, 3 weeks назад @ alexirpan.com
Which Tech CEOs Are Gamers?
Which Tech CEOs Are Gamers? Which Tech CEOs Are Gamers?

Reading Satya testifying about his gamer cred was ridiculous enough to inspire a dumb idea: which tech CEOs are gamers?

I did not find any mention of either playing video games.

There is one NYT article that mentions Elon Musk used to crash at Larry Page’s place after playing video games, but it never says if Page played video games, so I will play it safe and say neither are gamers.

The main video game related story Steve is tied to is the Atari Breakout debacle, which you probably already know.

Given how new his rise to tech CEO celebrity-ism is, you’d think there wouldn’t be much information about his video game habits, but somehow, there is.

2 months, 3 weeks назад @ alexirpan.com
AI Will Not Make Your Job Chill
AI Will Not Make Your Job Chill AI Will Not Make Your Job Chill

People keep talking about how AI will make their job easy, and I don’t really understand why.

I assume the factory job producing this was still hard work.

I don’t think AI has made my job chill, and I feel like I am front-line compared to much of the economy.

It’s not widely known, but transportation and warehousing has the highest rate of nonfatal work injuries in the US.

For a while, this will not lead to any job loss, because increasing abundance will lead to higher demand.

4 months, 3 weeks назад @ alexirpan.com
Why I Signed The Amicus Brief for Anthropic v Department of War
Why I Signed The Amicus Brief for Anthropic v Department of War Why I Signed The Amicus Brief for Anthropic v Department of War

On Monday, Anthropic filed a lawsuit against the Department of War, and an amicus brief in support of Anthropic was filed on behalf of a number of OpenAI and Google employees.

There’s also an amicus brief filed on behalf of Microsoft.

There’s conflicting reporting, but very broadly, Anthropic signed an agreement with the government to deploy Claude in classified, military contexts.

Anthropic said no, Pete Hegseth declared them a supply chain risk, and Anthropic filed a lawsuit against this.

The amicus brief was broadly aligned with my thoughts on the matter, so I signed.

7 months назад @ alexirpan.com
MIT Mystery Hunt 2026
MIT Mystery Hunt 2026 MIT Mystery Hunt 2026

This has spoilers for MIT Mystery Hunt 2026.

Pre-HuntThe time running up to Hunt was more stressful than usual…very briefly, I typically hunt with teammate.

Just last year, I did GPH 2025, LN Hunt, Teammate Hunt 2025, Microsoft Hunt 2025, and Silph Puzzle Hunt 2025, all of which had significant 3+ hour solve puzzles that would not be out of place in Mystery Hunt.

Not to mention smaller hunts like Advent Hunt, and then I didn’t even do Brown Puzzlehunt or Vertex Hunt or the fall CMU Hunt.

To me, the crux is whether Mystery Hunt is broken, or Mystery Hunt is fine.

8 months, 2 weeks назад @ alexirpan.com
Lil'Log
последний пост None
inFERENCe
последний пост 7 months, 2 weeks назад
The Future of Software
The Future of Software The Future of Software

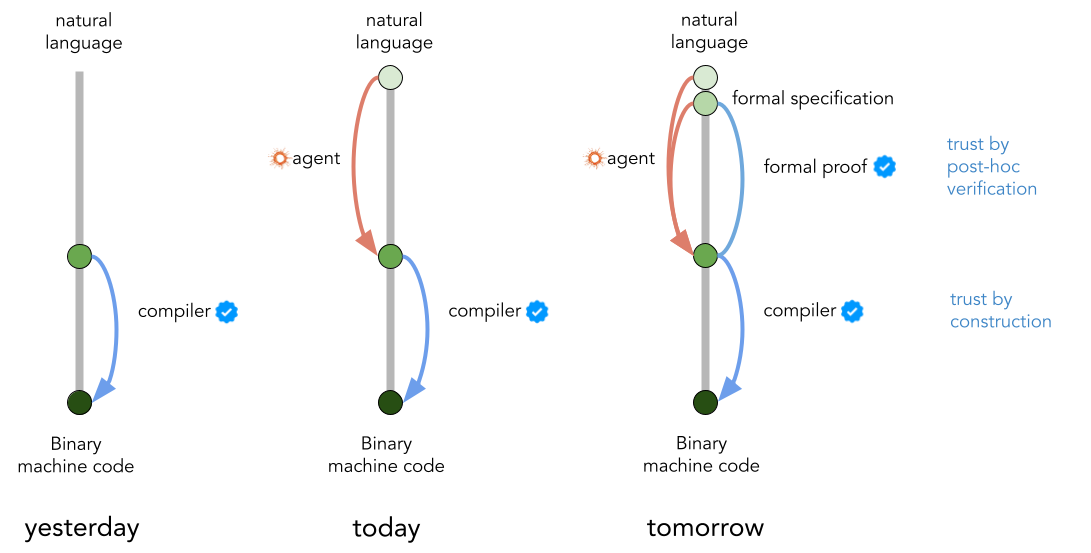
February 25, 2026The Future of SoftwareThe world of software is undergoing a shift not seen since the advent of compilers in the 1970s.

How will humans tell AI agents what software artefacts we would like to create?

How will humans tell AI agents what software artefacts we would like to create?

This future of software creation, in which our programming languages are abstracted away, raises two very important questions:What will the instruction/specification language look like?

This should be a clear layer of separation between the developer and the pool of AI agents working to maintain software.

7 months, 2 weeks назад @ inference.vc
Deep Learning is Powerful Because It Makes Hard Things Easy - Reflections 10 Years On
Deep Learning is Powerful Because It Makes Hard Things Easy - Reflections 10 Years On Deep Learning is Powerful Because It Makes Hard Things Easy - Reflections 10 Years On

Deep Learning is Powerful Because It Makes Hard Things Easy - Reflections 10 Years OnTen years ago this week, I wrote a provocative and bold post that blew up, made it to top spot on HackerNews.

In hindsight: There is a lot of stuff in deep learning that we don't understand nearly enough.

Sometimes things work for reasons completely unrelated to why we thought they would work.

(Pop some 🍿 in the microwave and read till the end for more)🎯 "Deep learning is powerful exactly because it makes hard things easy"Okay, this was a great insight.

🎯 Generative ModelingIn the post I suggested people learn "something harder" instead of - or in addition to - deep learning.

8 months, 1 week назад @ inference.vc
The Spectator
последний пост None
The Unofficial Google Data Science Blog The Unofficial Google Data Science Blog
последний пост None
Off the Convex Path
последний пост None
Jay Alammar
последний пост None
Piekniewski's blog
последний пост None
fast.ai NLP fast.ai NLP
последний пост None
Sebastian Ruder
последний пост None
大トロ 大トロ
последний пост None
🔬 Science
Papers With Code Papers With Code
последний пост None
Papers With Code Papers With Code
последний пост None
Papers With Code Papers With Code
последний пост None
💼 University and corporation labs
DeepMind DeepMind
последний пост 4 days, 22 hours назад
EmbeddingGemma 2: an open, lightweight multimodal embedding model
EmbeddingGemma 2: an open, lightweight multimodal embedding model EmbeddingGemma 2: an open, lightweight multimodal embedding model

We introduced EmbeddingGemma last year to provide a lightweight option for high-quality text embeddings, to help your apps organize, search, and connect information directly on consumer hardware.

With more than 20 million downloads, builders have used it to power smarter on-device search tools and privacy-first retrieval augmented generation (RAG) pipelines.

Today, we’re launching EmbeddingGemma 2, expanding beyond text to unify code, images, video, and audio in a shared embedding space.

Built on the Gemma 4 architecture and released under a commercially permissive Apache 2.0 license, EmbeddingGemma 2 has 740 million parameters, making it optimal for on-device inference.

It can help find a …

4 days, 22 hours назад @ blog.google
Gemini 4 Argon: our next era of frontier intelligence
Gemini 4 Argon: our next era of frontier intelligence Gemini 4 Argon: our next era of frontier intelligence

Today, we’re announcing our new frontier model, Gemini 4 Argon, which is rolling out to a set of trusted cyber defenders through our Fairwind Program.

Built to sustain deep reasoning across complex, long-horizon workflows, Argon is fundamentally changing the way we work and build at Google.

It delivers frontier performance in complex workflows across real-world software engineering, enterprise knowledge work like legal and finance, and cybersecurity defense.

We’ll continue to gather feedback from early testers as we iterate on guardrails before making Argon available to developers, enterprises, and consumers as soon as possible.

Argon will launch at an introductory price of $2 per million i…

1 week, 3 days назад @ blog.google
Introducing SynthID Bio
Introducing SynthID Bio Introducing SynthID Bio

As a part of our broader vision for bioresilience, SynthID Bio’s watermarking approach serves as an important, tangible verification layer embedded in the biological design itself.

Here, SynthID Bio can provide an automated verification signal, proving an order originated from a trusted model with built-in safeguards.

Similarly, SynthID Bio could help maintain the integrity of databases such as the Protein Data Bank, UniProt, and GenBank.

As a part of the submission process, SynthID Bio could help ensure synthetic entries are properly labeled or flagged for further review.

Looking aheadWhile no single biosecurity intervention is a silver bullet, SynthID Bio brings SynthID, our tried and tes…

1 week, 4 days назад @ deepmind.google
Introducing Gemini 3.8 Live with Live Avatar
Introducing Gemini 3.8 Live with Live Avatar Introducing Gemini 3.8 Live with Live Avatar

Building on the momentum of last week's Gemini 3.8 Live launch, today we are excited to introduce Gemini 3.8 Live with Live Avatar — bringing near real-time visual presence to our native live dialogue models.

By pairing near real-time video generation with speech, the Live Avatar feature creates an experience that listens, sees, and speaks with a dynamic visual persona.

With precise lip-syncing, natural expressions, and fluid turn-taking, Live Avatar enables enterprises to expand their virtual offerings more interactively.

Whether providing engaging customer service or delivering interactive walkthroughs, it transforms digital exchanges into richer, more accessible experiences.

Starting tod…

2 weeks, 3 days назад @ blog.google
Advancing Private AI Compute with secure, server-side memory
Advancing Private AI Compute with secure, server-side memory Advancing Private AI Compute with secure, server-side memory

A technical update on our Private AI Compute architecture, which will enable persistent, cross-device AI memory with on-device privacy standards.

AI is becoming more capable and intuitive — remembering what matters, understanding the world around you, and acting at your direction.

Today, we are sharing how we will bring private, server-side memory to our Private AI Compute platform.

Bringing on-device privacy to cloud-scale memoryWith this new technical capability, a new persistent memory layer will be able to function like a secure digital vault in the cloud.

The diagram below shows how this update to Private AI Compute will work.

2 weeks, 4 days назад @ deepmind.google
Gemini 3.8 text-to-speech says hello
Gemini 3.8 text-to-speech says hello Gemini 3.8 text-to-speech says hello

Get expressive high-quality speech generation built for global scaleGemini 3.8 Flash TTS delivers leading voice customization capabilities, securing the #1 overall spot on Hume AI’s Voice Design Benchmark (71.4) and also leading in accent modeling (60.8).

Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS enable truly expressive performances without sacrificing reliability, also securing the #1 and #2 spots respectively on Hume AI’s Overall Quality Index.

The model shows major improvements on a wide range of use cases such as long-form content and dual-speaker screenplay control compared to Gemini 3.1 Flash TTS.

In blind human preference evaluations on Voice Arena, Gemini 3.8 Flash and Flas…

2 weeks, 4 days назад @ blog.google
Introducing Gemini 3.8 Live and 3.8 Live Extended Thinking
Introducing Gemini 3.8 Live and 3.8 Live Extended Thinking Introducing Gemini 3.8 Live and 3.8 Live Extended Thinking

Gemini 3.8 Live : Built for scale and cost efficiency, combining conversational intelligence with fluid dialogue and visual grounding.

: Built for scale and cost efficiency, combining conversational intelligence with fluid dialogue and visual grounding.

Gemini 3.8 Live Extended Thinking: Built for high-complexity tasks, with increased intelligence and multi-step reasoning.

Gemini 3.8 Live has shown a high preference among users, securing a second place in the Speech Agent Arena.

In addition to this performance, it remains highly cost-effective — providing developers and enterprises with a capable and efficient model built for scale.

3 weeks, 5 days назад @ blog.google
AlphaGenome Atlas: A predictive map of every possible DNA letter change in the human genome
AlphaGenome Atlas: A predictive map of every possible DNA letter change in the human genome AlphaGenome Atlas: A predictive map of every possible DNA letter change in the human genome

A major hurdle in understanding rare diseases is the daunting task of pinpointing the few causal variants hidden among thousands of candidates.

Moving beyond individual rare disease research, AlphaGenome Atlas can help uncover the genetic architecture of common traits in the general population.

Taking this approach even further, Hawkes used AlphaGenome Atlas to look at how hundreds of millions of non-coding variants in the UK Biobank might be linked to body mass index.

Accelerating genomic discoveryWith AlphaGenome Atlas we are creating new layers of information that will help further our understanding of the human genetic code.

AlphaGenome Atlas is powerful in isolation, but it also repres…

1 month назад @ deepmind.google
Introducing WeatherNext 3, our most advanced and accurate global weather AI model
Introducing WeatherNext 3, our most advanced and accurate global weather AI model Introducing WeatherNext 3, our most advanced and accurate global weather AI model

Most AI weather models, including WeatherNext 2, are trained on data from numerical weather prediction (NWP) models.

By ingesting a mosaic of live, global geostationary satellite data, our new model gains a rich, continuously updating view of the atmosphere.

Traditional models struggle here because they train on representations of the atmosphere that lack detail and miss extreme local variations.

This allows us to make global forecasts on a 5-kilometer grid that account for regional details like topography.

Precipitation forecasting at breakthrough accuracyGlobal weather models notoriously struggle to accurately predict precipitation.

1 month, 1 week назад @ blog.google
Proactive cyber defense for governments and enterprises
Proactive cyber defense for governments and enterprises Proactive cyber defense for governments and enterprises

Defenders wanting to use advanced AI have faced a difficult dilemma: adopt enormous frontier models that could be expensive to deploy and difficult to control across enterprise codebases, or turn to smaller open-weight models that might struggle with complex vulnerability remediation and require teams to build their own tooling and infrastructure from scratch.

Today, we’re launching our Fairwind Program to bring the best of Google’s AI and cyber defense capabilities to a trusted group of Google Cloud customers, government agencies, and cybersecurity partners, to help them proactively solve cyber risks at scale.

As a first step, the Fairwind Program will give defenders access to powerful and…

1 month, 1 week назад @ blog.google
Introducing Gemini 3.8 Flash and 3.8 Flash Cyber
Introducing Gemini 3.8 Flash and 3.8 Flash Cyber Introducing Gemini 3.8 Flash and 3.8 Flash Cyber

Building on the momentum of 3.7 Flash from three weeks ago and marking our third Flash release in only six weeks, today we’re introducing Gemini 3.8, our best reasoning & coding model yet, at the same speed and low cost of 3.7.

Gemini 3.8 introduces 2 variants:Gemini 3.8 Flash: our most intelligent workhorse model, delivering significant improvements from 3.7 Flash across software engineering, agentic tasks, and critical, multi-step reasoning in specialized domains.

It is available at the same introductory price as 3.7 Flash at $0.75 per million input tokens and $3.75 per million output tokens.

Gemini 3.8 Flash Cyber: our most capable cybersecurity model with frontier-level performance in v…

1 month, 1 week назад @ blog.google
Introducing agentic video understanding with Gemini
Introducing agentic video understanding with Gemini Introducing agentic video understanding with Gemini

Today, we’re launching agentic video understanding across our latest models: Gemini 3.7 Flash, 3.6 Flash and 3.5 Flash-Lite.

This new capability improves accuracy while dramatically reducing token usage and costs for video analysis.

Similar to agentic vision, which combines code execution with Gemini models’ native image understanding, agentic video understanding uses Gemini’s native video tools to improve performance and unlock new capabilities for video processing like sub-second moment retrieval, more accurate anomaly detection, precise counting and more.

BenchmarksUnlike current ‘static’ processing, where the model ingests the video at a fixed frames-per-second rate (default 1 FPS, adju…

1 month, 1 week назад @ blog.google
Gemini Omni 1.1 Flash lets you build with more control
Gemini Omni 1.1 Flash lets you build with more control Gemini Omni 1.1 Flash lets you build with more control

Today, we’re introducing Gemini Omni 1.1 Flash, a new suite of creative controls and generative video capabilities to support developers.

Gemini Omni brought real-world reasoning to generative creation, and today’s updates make Omni 1.1 production-ready for professional use via the Gemini API in Google AI Studio.

Whether you’re building generative video workflows, creative tools, or media editing software, these updates make generative video more controllable, faster to iterate on, and polished for real-world deployment.

With Omni 1.1, the model can now analyze up to 10 seconds of prior context — a leap from previous models that only referenced the final second.

The result is improved visua…

1 month, 2 weeks назад @ blog.google
Piloting the world's first double-blind AI evaluations
Piloting the world's first double-blind AI evaluations Piloting the world's first double-blind AI evaluations

If they accidentally peek at the test questions in advance, achieving a perfect score is influenced by this knowledge, making it a meaningless accomplishment.

To truly measure what they know, they must have no visibility of the test questions until it's time to take the exam.

That is the exact challenge the industry faces when evaluating advanced AI models.

Today, we’re introducing the world’s first double-blind evaluation of a proprietary, frontier class AI model, which keeps external evaluations confined to a cryptographic “box” where they can’t be used by models later to optimize performance ahead of testing.

At Google, we assess our AI systems using a broad spectrum of evaluations throu…

1 month, 2 weeks назад @ deepmind.google
Intelligent transcription with Gemini 3.5 Transcribe
Intelligent transcription with Gemini 3.5 Transcribe Intelligent transcription with Gemini 3.5 Transcribe

Today, we’re introducing Gemini 3.5 Transcribe, our most precise speech-to-text model yet, designed for intelligent voice interactions.

Unlike conventional speech recognition models that struggle with background noise, complex jargon, and disfluency cleanup, Gemini 3.5 Transcribe converts raw audio directly into accurate, polished, formatted text.

Now, developers can build similar capabilities with Gemini 3.5 Transcribe in the Gemini API in Google AI Studio and Gemini Enterprise Agent Platform.

We've built 3.5 Transcribe to plug seamlessly into your developer workflows, whether you’re building voice agents, real-time captioning tools, or post-call analytics pipelines.

Get more precise and i…

1 month, 2 weeks назад @ blog.google
Google
последний пост 3 days, 6 hours назад
Welcome to Gemini at Work 2026: Introducing the Gemini agent
Welcome to Gemini at Work 2026: Introducing the Gemini agent Welcome to Gemini at Work 2026: Introducing the Gemini agent

Smart Storage : Ninety percent of enterprise data is unstructured — PDFs, images, scans, and audio recordings — which often remain "dark" and unreadable.

Snap connected its Prism agent directly to its storage archives, cutting technical diagnostic troubleshooting times down from 30 minutes to just 30 seconds.

When the Gemini agent connects to an external system, its identity is mapped and propagated through industry standards such as OAuth.

In addition, Accenture has made a significant investment by establishing a dedicated Gemini Enterprise Business Group to accelerate customer adoption and innovation.

Gemini Enterprise in action: Global momentumOrganizations worldwide are driving measurab…

3 days, 6 hours назад @ cloud.google.com
Innovation in Ireland: How Irish brands scale with Gemini Enterprise
Innovation in Ireland: How Irish brands scale with Gemini Enterprise Innovation in Ireland: How Irish brands scale with Gemini Enterprise

As modernization accelerates, Irish organizations — spanning government agencies, established enterprise brands, and growing startups in AI and other areas — are all advancing their technical foundations.

We are seeing organizations move from early prototypes to production-ready deployments using Gemini Enterprise.

And this momentum is shared: Organizations across Ireland are using Google Cloud to modernize infrastructure and put AI to work.

Strict data sovereignty controls safeguard taxpayer information while Gemini Enterprise powers agentic data analysis, helping Revenue deliver secure, responsive public services.

Virgin Media Ireland: Accelerating workflowsSupported by Liberty Global's p…

3 days, 6 hours назад @ cloud.google.com
Empower your agents with the Google Cloud CLI remote MCP server
Empower your agents with the Google Cloud CLI remote MCP server Empower your agents with the Google Cloud CLI remote MCP server

Today, we’re expanding our ecosystem of managed remote MCP servers by introducing the Google Cloud CLI remote MCP server in preview.

The Google Cloud CLI remote MCP server bridges this gap by packaging the versatility of hundreds of gcloud and bq commands into one single MCP server.

The Cloud CLI remote MCP server bridges CLI capabilities with MCP benefits by providing an isolated execution sandbox on Google Cloud infrastructure.

Cloud audit logging: The Cloud CLI remote MCP server can be configured to log every tool invocation to Audit Logs (Data Access logs under cloudcli.googleapis.com/mcp).

Connecting to the Google Cloud CLI Remote MCP ServerIntegrating cloud management into your agents…

1 week, 4 days назад @ cloud.google.com
Why your startup needs open models alongside frontier APIs
Why your startup needs open models alongside frontier APIs Why your startup needs open models alongside frontier APIs

Great engineering teams pick the right tool for each job.

Instead, the winning pattern is a compound AI stack: pairing frontier models for complex synthesis with compact, open-weight models that you can tune, control, and run anywhere.

You can handle many local interactions on-device for zero incremental cost, and keep a bridge to frontier models in the cloud for the requests that need it.

MedGemma scores 87.7% on the MedQA benchmark, matching the clinical accuracy of frontier models at roughly one-tenth the inference cost.

Benchmark Gemma: Run a quick test with a compact Gemma model locally or on a single endpoint.

1 week, 6 days назад @ cloud.google.com
Best practices guide for customizing Gemini models via Reinforcement Learning (RL)
Best practices guide for customizing Gemini models via Reinforcement Learning (RL) Best practices guide for customizing Gemini models via Reinforcement Learning (RL)

So here at Google Cloud, we packaged it into a managed RL fine-tuning service (RLFT service) — you bring prompts and a reward function; we handle the infrastructure and the proprietary model internals.

Now, you can adapt Gemini with the service — teaching the model from a reward signal you define, rather than from a fixed set of labeled answers.

In this guide, we will walk through practical best practices for using RL fine-tuning service.

We'll start with a short tour of the RL training loop, how to decide if and when to use RL, and introduce how to get the most value from this approach.

RLFT adapts Gemini from a reward signal you define rather than labeled answers.

2 weeks, 2 days назад @ cloud.google.com
Power your agents: Gemini 3.8 Live with Live Avatar is now generally available
Power your agents: Gemini 3.8 Live with Live Avatar is now generally available Power your agents: Gemini 3.8 Live with Live Avatar is now generally available

Following our announcement of Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking last week, we are thrilled to share that Gemini 3.8 Live with Live Avatar is now generally available in Gemini Enterprise.

Gemini 3.8 Live already delivers a native speech-to-speech foundation for fluid, responsive dialogue.

Together, you’ll have access to:Video avatars: Conversational video with the Live Avatar feature can generate video avatars with synchronized lip-syncing.

Though Gemini 3.8 Live Extended Thinking remains in private preview, Gemini 3.8 Live with Live Avatar is now available with US and EU endpoints, with provisioned throughput, enterprise compliance, and strict data governance.

Three demo…

2 weeks, 3 days назад @ cloud.google.com
How growing Latin American midsize businesses are building in the AI era
How growing Latin American midsize businesses are building in the AI era How growing Latin American midsize businesses are building in the AI era

The number of Latin American-based small and medium businesses using Google Cloud AI tools has grown 8x year-over-year and the number of Brazil based small and medium businesses using Google Cloud AI tools has grown 9x year-over-year.

Help more people build their own AI agents to help them in their everyday jobs.

Google skills for organizations: Access thousands of free, on-demand AI courses and hands-on practice labs designed by experts at Google Cloud and Google DeepMind.

Get certified: Help your staff gain industry-recognized AI certificates through guided courses, expert mentoring, and skill badges.

By offering easy-to-use tools and free training — from everyday office apps in Workspace…

2 weeks, 3 days назад @ cloud.google.com
The three things today's hottest startups are looking for in their AI stack
The three things today's hottest startups are looking for in their AI stack The three things today's hottest startups are looking for in their AI stack

Google Cloud has become the platform of choice for startups building AI.

And when startups use Gemini Enterprise, they also tend to use our “core cloud” services like Storage, BigQuery, or GKE.

Gemini models — as well as several of the third-party models available through Gemini Enterprise — are providing very strong price-performance for startups.

They will also use Gemini Enterprise Agent Platform and AI models on Google Cloud to help robotics process multimodal information like video.

To learn more about Google Cloud’s work with leading AI startups, or to get started building with us, visit here.

2 weeks, 3 days назад @ cloud.google.com
Changing the game: How Google uses agentic AI to secure hundreds of millions of lines of code
Changing the game: How Google uses agentic AI to secure hundreds of millions of lines of code Changing the game: How Google uses agentic AI to secure hundreds of millions of lines of code

Our approach instead focuses on pre-submit scanning, where we evaluate each code check-in (across every layer of the stack) in real-time using AI agents.

Rather than relying on static decoupled documents, the threat models use live codebase metadata.

The scanning agent improves its accuracy further using a dependence call graph across packages and libraries to expand and refine its threat model context.

Making threat models part of our ongoing vulnerability scanning encourages developers to continuously update threats and dependencies, keeping the models up-to-date.

Use context wisely: Feed your agents your existing threat models.

3 weeks, 2 days назад @ cloud.google.com
Cloud CISO Perspectives: How Google monitors AI threats and advances AI defenses
Cloud CISO Perspectives: How Google monitors AI threats and advances AI defenses Cloud CISO Perspectives: How Google monitors AI threats and advances AI defenses

When you feed this rich, multi-dimensional internal observability into security models, AI defense becomes inherently faster and more accurate than AI offense.

If you use Google tools to facilitate an attack, you lose access to those tools.

Hardening our AI models and classifiers .

We operate a continuous feedback loop for our AI models.

Developing advanced defenses and threat models.

3 weeks, 4 days назад @ cloud.google.com
How Orange uses agents to make FinOps everyone's responsibility
How Orange uses agents to make FinOps everyone's responsibility How Orange uses agents to make FinOps everyone's responsibility

Orange calls these FinOps Clean Days.

Moving from awareness to action means finding ways to build FinOps accountability, and to get teams to genuinely care.

First, Cloud FinOps is a shared responsibility, with every stakeholder in a project involved in their own way.

And the only path to that shared responsibility runs through communication and a deliberate change effort.

“We insisted on the concept of shared responsibility across the organization for our FinOps practices,” Marini told us.

3 weeks, 4 days назад @ cloud.google.com
Google is a Leader in the 2026 Gartner® Magic Quadrant™ for Enterprise AI Assistants
Google is a Leader in the 2026 Gartner® Magic Quadrant™ for Enterprise AI Assistants Google is a Leader in the 2026 Gartner® Magic Quadrant™ for Enterprise AI Assistants

Open connectivity: Gemini Enterprise offers extensive connectivity beyond Google's ecosystem — extending to Microsoft 365, other third-party software, and internal enterprise data sources.

This open connectivity lets organizations adopt Gemini Enterprise alongside their existing infrastructure without costly system overhauls.

Simple economics: Gemini Enterprise offers a straightforward pricing model, with actions like chat and search included in the base SKU.

Accelerating our vision with the latest Gemini Enterprise advancementsOver the past months, we have accelerated Gemini Enterprise with significant product advancements:Tailored industry solutions: We introduced specialized solutions fo…

1 month назад @ cloud.google.com
How Airtel delivered its flawless Indian Premiere League 2026 cricket broadcasts
How Airtel delivered its flawless Indian Premiere League 2026 cricket broadcasts How Airtel delivered its flawless Indian Premiere League 2026 cricket broadcasts

For the millions of fervent fans of the Indian Premiere League (IPL), being able to count on a flawless live streaming cricket experience is never up for debate.

For Airtel, producing league TV broadcasts with some of the world's most massive concurrent viewership, dropped packets and buffering are simply not options.

During the IPL 2026 season, Airtel partnered with Google Cloud to manage this digital delivery.

Delivering video under these concurrency spikes requires an edge architecture designed strictly around localization, paired with proactive operational monitoring.

Our goal for IPL 2026 was to deliver an uninterrupted, stadium-grade viewing experience to cricket fans across India, re…

1 month назад @ cloud.google.com
How KDDI built Buffmee, a faster, reliable consumer RAG app
How KDDI built Buffmee, a faster, reliable consumer RAG app How KDDI built Buffmee, a faster, reliable consumer RAG app

To meet these performance targets, organizations need a systematic approach to AI evaluation and real-time bottleneck identification.

That is why we are sharing the automated evaluation framework and performance optimization techniques that helped KDDI successfully launch their application.

The results were inspiring: KDDI reduced total application response latency by 38%, successfully hitting their target response performance.

To solve this, the development team designed a systematic AI evaluation process using Gemini Enterprise Agent Platform Evaluation Service.

They ingested their extensive document corpus, constructed hundreds of automated evaluation tests, and built a comprehensive ben…

1 month назад @ cloud.google.com
Spanner migrations: Automating dual-write with Antigravity CLI for minimal disruption
Spanner migrations: Automating dual-write with Antigravity CLI for minimal disruption Spanner migrations: Automating dual-write with Antigravity CLI for minimal disruption

When Google's Finance Engineering team needed to modernize their legacy data layer, they chose Spanner, a globally distributed, strongly consistent, multi-model database with high availability capabilities.

Further, doing so without disruption would have required implementing multi-phase dual-write architectures across every DAO in our codebase.

To solve this, we took an alternative approach: We built an automated refactoring pipeline powered by Antigravity CLI in headless mode.

This helped us accelerate our migration velocity significantly while maintaining strict data parity in our staging environments as we prepare for production.

The challenge: Anatomy of a dual-write migrationWhen migr…

1 month, 1 week назад @ cloud.google.com
OpenAI
последний пост None
Microsoft Microsoft
последний пост 4 days, 2 hours назад
Agent Lightning v1.0: A 3,500-Line Lightweight Agentic RL Framework for Training Agents with Real Harnesses
Agent Lightning v1.0: A 3,500-Line Lightweight Agentic RL Framework for Training Agents with Real Harnesses Agent Lightning v1.0: A 3,500-Line Lightweight Agentic RL Framework for Training Agents with Real Harnesses

Lightweight by design: Agent Lightning v1.0 delivers a complete agent RL control plane in roughly 3,500 lines of code.

Compared with the original, Agent Lightning, v1.0 puts more emphasis on staying lightweight, on integrating with real harnesses, and on a complete, reproducible agent RL training pipeline.

Agent Lightning v1.0 was rebuilt around Harnessed Agentic RL, with key improvements:Lightweight : the entire framework is about 3,500 lines of code.

Training on a real agent harness : agents reach the model through the large language model (LLM) proxy in Agent Lightning v1.0, leaving existing harness code unchanged.

Traditional agentic RL compared with Harnessed Agentic RL.

4 days, 2 hours назад @ microsoft.com
What AI gets wrong and what failure teaches us
What AI gets wrong and what failure teaches us What AI gets wrong and what failure teaches us

NEVILLE: My research, kind of, spans the spectrum from theory to application.

But right now, if you’re doing work on AI systems, I think that industry is really the place to be.

What we really focus on is trying to push the frontier of behavior of these AI systems in realistic work environments.

NEVILLE: That’s, that’s a, that’s a big question.

But I think I’m very bullish on the research that’s happening.

5 days, 2 hours назад @ microsoft.com
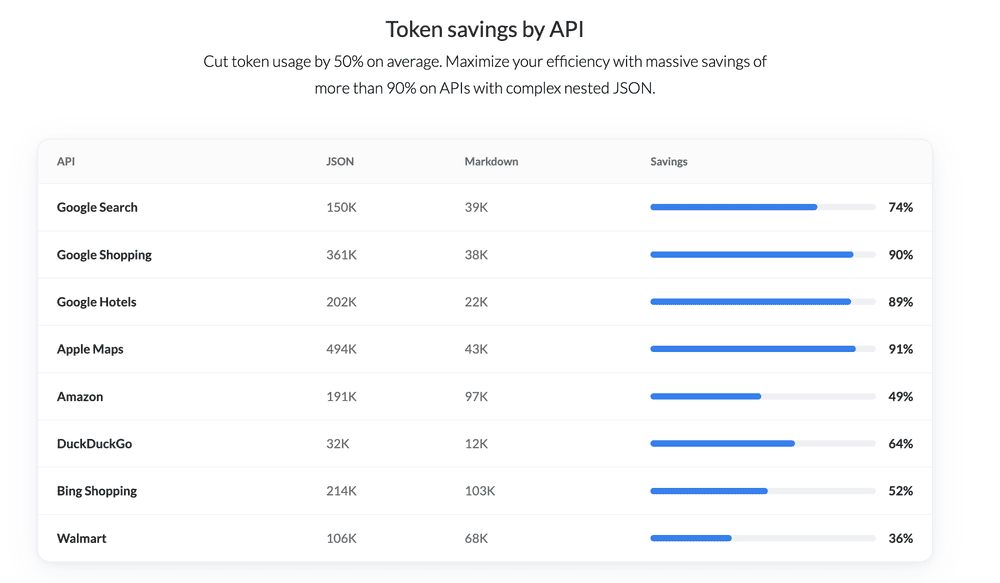
Forecasting space weather risks on power grids
Forecasting space weather risks on power grids Forecasting space weather risks on power grids

A machine learning pipeline uses forecast-time solar-wind information to generate location-specific risk estimates for 66,935 substations in the continental United States.

Finally, the resulting predictions are converted into location-specific risk estimates and aggregated into a continental risk assessment.

End-to-end forecasting pipeline from L1 solar-wind measurements to location-specific risk estimates across 66,935 U.S. substations.

This produces continuous risk estimates that can distinguish lower-risk locations from areas where resistive geology can amplify ground-level effects.

Together, these efforts point toward richer planning and resilience workflows that combine hazard forecast…

1 week, 4 days назад @ microsoft.com
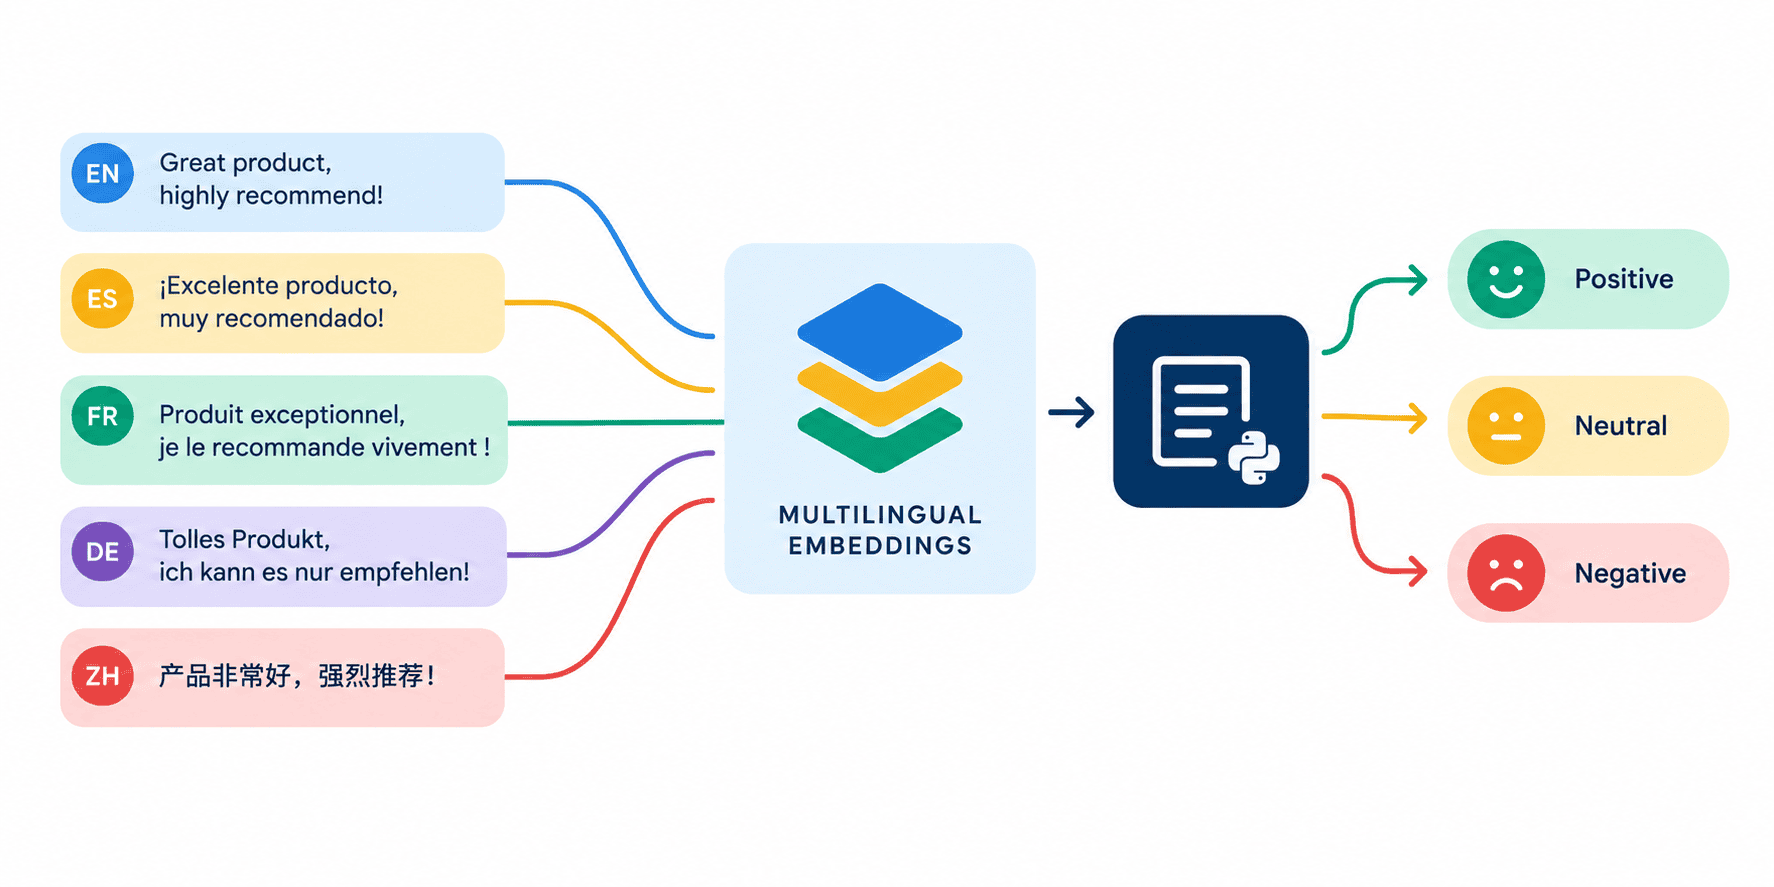
Introducing Quine: An AI research system designed for the complexity of biology
Introducing Quine: An AI research system designed for the complexity of biology Introducing Quine: An AI research system designed for the complexity of biology

is a research effort to create a multimodal world model of biology and an interactive harness connecting models, scientific tools, literature, and researchers.

Today, Microsoft Research is introducing Quine (opens in new tab), a research effort designed to work across those boundaries, reflecting our long-term vision for a discovery system that evolves through scientific use.

Quine brings together a world model of biology with a harness that connects scientific tools, literature, the wet lab, and the researchers using them.

This raised a provocative question for us: what would it take to build a world model for biology?

Critically, the world model doesn’t need to be perfect—indeed, it will …

1 week, 5 days назад @ microsoft.com
One year in: How Microsoft Research Asia – Singapore is advancing research, partnership and talent for real-world impact
One year in: How Microsoft Research Asia – Singapore is advancing research, partnership and talent for real-world impact One year in: How Microsoft Research Asia – Singapore is advancing research, partnership and talent for real-world impact

On July 24, 2025, Microsoft Research Asia – Singapore (MSRA – Singapore) opened its doors as Microsoft’s first research lab in Southeast Asia.

The launch built on more than two decades of collaboration between Microsoft Research Asia and Singapore’s universities, research institutes, and government agencies.

“When we established Microsoft Research Asia — Singapore one year ago, our vision was not simply to open another research lab.

Students may engage with Microsoft Research Asia through workshops or summer schools, gain hands-on experience through its flagship research initiative, Microsoft Research Asia Stars of Tomorrow Internship Program, or pursue doctoral research through joint PhD p…

1 week, 5 days назад @ microsoft.com
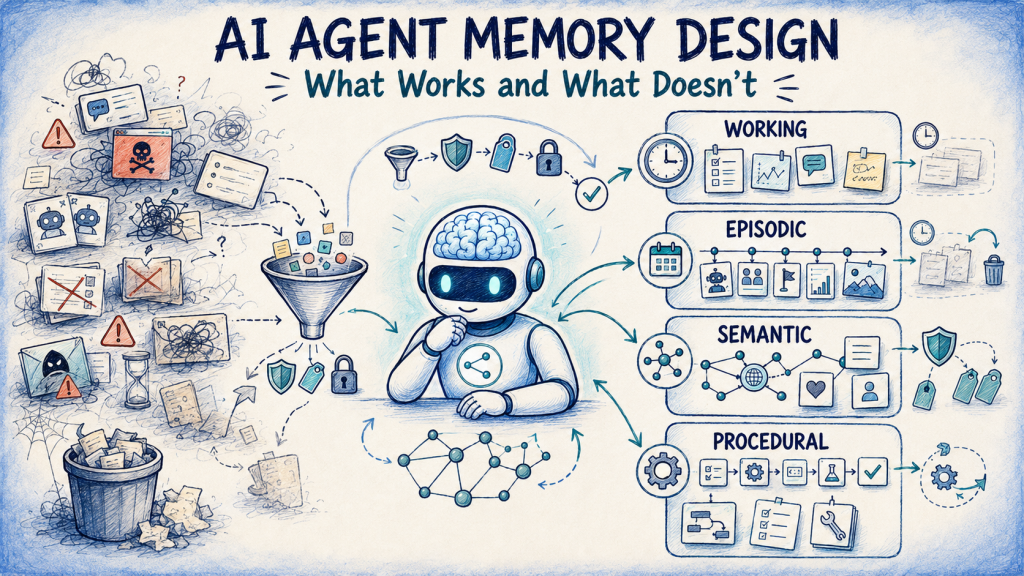
Offloaded inference for real-world physical AI robotics
Offloaded inference for real-world physical AI robotics Offloaded inference for real-world physical AI robotics

To better understand the systems implications of physical AI, we conducted the first systematic study of robotics workloads.

Offloading physical AI inference out of the robot improved its response time and accuracy, along with battery lifetime and cost.

We believe that our measurement study will inform the design of physical AI inference systems.

Physical AI Toolchain is an open-source, production-ready framework that integrates Microsoft Azure (opens in new tab) cloud services with NVIDIA’s (opens in new tab) physical AI stack, accelerating robotics and physical AI developers to automate and scale data curation, augmentation, and evaluation across perception, mobility, imitation learning, …

2 weeks, 4 days назад @ microsoft.com
Improving synthesis prediction of small molecules at scale with RetroChimera
Improving synthesis prediction of small molecules at scale with RetroChimera Improving synthesis prediction of small molecules at scale with RetroChimera

At a glance We report on the recent publication of our retrosynthesis model RetroChimera in the journal Nature (opens in new tab) ..

Yet, progress is slowed by chemical synthesis—the time-consuming process of making new molecules from simpler building blocks in the lab.

In a paper recently published in the journal Nature (opens in new tab), we present RetroChimera (opens in new tab), a new framework for retrosynthesis prediction.

RetroChimera could enable chemists to assess more—and more complex—candidate molecules at large scale.

RetroChimera is available on GitHub (opens in new tab) (MIT license) and accessible via Microsoft Foundry (opens in new tab).

2 weeks, 6 days назад @ microsoft.com
Called to serve: Tech, research, and positive impact with Chris White

Lab Director Chris White has worked on research challenges with real-world implications—from new approaches to wartime data analysis to tools for combating human trafficking. He talks to program manager Weishung Liu about the influences that led to the work and more.

The post Called to serve: Tech, research, and positive impact with Chris White appeared first on Microsoft Research.

1 month назад @ microsoft.com
GigaPath-Flash and GigaTIME-Flash: Toward population-scale discovery with efficient pathology foundation models
GigaPath-Flash and GigaTIME-Flash: Toward population-scale discovery with efficient pathology foundation models GigaPath-Flash and GigaTIME-Flash: Toward population-scale discovery with efficient pathology foundation models

A distilled pathology foundation model backbone reduces computational requirements without sacrificing performance, enabling repeated analyses across larger patient cohorts.

GigaPath-Flash and GigaTIME-Flash make these capabilities substantially more efficient, enabling researchers to analyze larger cohorts, run more experiments, and move toward population-scale discovery.

To realize the full potential of pathology foundation models, we need models that can be applied repeatedly and affordably across large patient populations.

Listen now Opens in a new tabEfficiency as an enabler of discoveryGigaPath and GigaTIME demonstrated what pathology foundation models can learn from whole slides and …
1 month, 1 week назад @ microsoft.com
Broadening access to Skala creates a faster path to predictive DFT
Broadening access to Skala creates a faster path to predictive DFT Broadening access to Skala creates a faster path to predictive DFT

and is being integrated into , , and , bringing next-generation DFT accuracy closer to the communities that rely on these codes every day.

Together, these developments mark another milestone toward a future in which computational chemistry simulations are both predictive and integrated in all relevant scientific and industrial workflows.

Alongside these integration efforts, we are introducing a living benchmark that tracks the computational performance of successive, increasingly optimized Skala releases.

Together, these developments mark another milestone toward a future in which computational chemistry simulations are both predictive and accessible across a broader range of relevant scien…

1 month, 3 weeks назад @ microsoft.com
MindTopo reveals VLMs’ spatial reasoning abilities
MindTopo reveals VLMs’ spatial reasoning abilities MindTopo reveals VLMs’ spatial reasoning abilities

At a glance MindTopo is a new benchmark for testing topological reasoning in AI, evaluating whether multimodal models can understand concepts such as connectivity, enclosure, order, separation, and knots.

How MindTopo defines topological spaceMost spatial evaluations for multimodal models focus on Euclidean properties such as distance, direction, size, and relative position.

MindTopo pairs questions about static scenes with interactive tasks that require models to preserve or change the same topological relations.

MindTopo maps reasoning and planning tasks to continuity, separation, order, enclosure, and knots.

Closing that gap may require models that carry an explicit topological state, or…

2 months назад @ microsoft.com
Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement
Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement

Research Note: CARE-X is a research model and not a Microsoft product offering or medical device.

CARE-X was developed as a research model to explore how a unified approach can address these diverse demands.

The CARE-X model.

The classification head outputs calibrated P(Yes)/P(No) scores; the grounding head outputs bounding box coordinate with confidence; the language modeling head generates free-text responses.

CARE-X: Toward clinically useful radiology AICARE-X demonstrates that discriminative and generative objectives can be effectively combined within a unified radiology AI model.

2 months назад @ microsoft.com
Orchard: An open framework for scalable agentic AI
Orchard: An open framework for scalable agentic AI Orchard: An open framework for scalable agentic AI

At a glance Orchard is an open-source framework for scalable and cost-effective agentic AI research, built around Orchard Env, a reusable environment service for training and evaluating agents across task domains.

To address this gap, we introduce Orchard (opens in new tab), an open-source framework for scalable agentic modeling.

Unlike many existing frameworks, Orchard Env is designed to support different agent systems and task types without modification.

(opens in new tab) We are also releasing the training data and evaluation methods used to build them.

By making the underlying infrastructure open, lightweight, and reusable, Orchard lowers the cost of agentic AI research.

2 months, 1 week назад @ microsoft.com
Echoverse: Deep, evolving environments for computer-use agents
Echoverse: Deep, evolving environments for computer-use agents Echoverse: Deep, evolving environments for computer-use agents

At a glance We built twelve training worlds for computer-use agents: ten deep domain worlds and two capability worlds, each drilling a single control rendered in many forms (date pickers and nested filters).

Shallow worlds backfire; deep worlds transferA shallow world is the cheap option.

A deep world costs more, but its trajectories carry the dependent structure that transfers to the live site.

Only the deep world improves both, lifting Allrecipes to 85.0% and the harder Hugging Face split to 65.0%.

First, more deep worlds for the closed domains public benchmarks cannot reach.

2 months, 1 week назад @ microsoft.com
EvoLib: Turning experience into evolving knowledge
EvoLib: Turning experience into evolving knowledge EvoLib: Turning experience into evolving knowledge

By turning experience into reusable knowledge, EvoLib helps AI models learn from past successes and failures and evolve the knowledge that has the highest potential on improving future performance.

By turning experience into reusable knowledge, EvoLib helps AI models learn from past successes and failures and evolve the knowledge that has the highest potential on improving future performance.

Rather than treating memory as a growing archive of past experiences, EvoLib extracts reusable knowledge from those experiences and continually refines it as new experiences arrive.

As new knowledge is extracted from recent experience, EvoLib retrieves similar knowledge from the library and tries to co…

2 months, 1 week назад @ microsoft.com
MIT AI MIT AI
последний пост 2 days, 21 hours назад
3 Questions: What is the best path forward for AI in academia?
3 Questions: What is the best path forward for AI in academia? 3 Questions: What is the best path forward for AI in academia?

Here, focusing primarily on graduate research and education, he describes key questions that departments and universities need to think about, and how they can best work with AI going forward.

This also applies to AI research itself: improving models, training procedures, and their supporting tools.

We can imagine a future in which MIT's laboratories function more like a single, living, scientific organism, connected through shared AI research infrastructure.

This will require substantial public and institutional investment now in compute, secure data systems, and expertise in adapting and post-training AI models.

AI systems can already synthesize and reason about information from more sour…

2 days, 21 hours назад @ news.mit.edu
Using AI to mitigate the growing environmental threat of data centers
Using AI to mitigate the growing environmental threat of data centers Using AI to mitigate the growing environmental threat of data centers

She began tackling inefficiencies in cloud computing systems and large-scale data centers, which was a rapidly growing area of research.

Through that work, Delimitrou and her research mentor, Christos Kozyrakis, the Leonard Bosack and Sandy K. Lerner Professor of Engineering, realized many large computing systems were underutilized.

It was a bit risky because people had not yet shown that these techniques would work,” Delimitrou says.

As she delved deeper into cloud computing, Delimitrou observed that cloud applications were changing.

In the lab, a creative mindset helps Delimitrou and her team identify novel solutions to problems in cloud computing that others might overlook.

3 days, 14 hours назад @ news.mit.edu
Discovering the value of humanistic inquiry
Discovering the value of humanistic inquiry Discovering the value of humanistic inquiry

Our business, of humanistic thinking.” As senior lecturer in the Concourse program, one of MIT’s first-year learning communities, Rabieh has been introducing students to the “business” since 2010.

Ford Professor of Political Science Lily Tsai was recently named director after Anne McCants, the Ann F. Friedlaender Professor of History, stepped down.

McCants says she relished interacting with Concourse students in a sustained way — often for all four years — and learning not only from them, but also colleagues.

Those efforts include the Compass Initiative, which Tsai co-leads with other faculty from across SHASS; the MIT Human Insight Collaborative; and the creation of shared faculty position…

3 days, 22 hours назад @ news.mit.edu
Supercomputing researchers document evolution of AI hardware
Supercomputing researchers document evolution of AI hardware Supercomputing researchers document evolution of AI hardware

AI accelerators — specialized systems designed to speed up capabilities such as neural networks, deep learning, and machine learning — have been a major area of development for nearly a decade.

Since 2018, team from the Lincoln Laboratory Supercomputing Center (LLSC) has been conducting the Lincoln AI Computing Survey (LAICS, pronounced "lace").

Six papers later, LAICS continues to summarize current commercial AI accelerators and compare their peak performance and peak power.

"About eight years ago, we saw a sharp rise in the number of research AI accelerators described in research papers and commercial accelerators being announced, and we started to get questions about them from government…

4 days, 21 hours назад @ news.mit.edu
Chris Bourg named vice provost and Barbara K. Ostrom (1978) Director of the MIT Libraries
Chris Bourg named vice provost and Barbara K. Ostrom (1978) Director of the MIT Libraries Chris Bourg named vice provost and Barbara K. Ostrom (1978) Director of the MIT Libraries

Chris Bourg, who has served as director of the MIT Libraries since 2015, has been named vice provost and Barbara K. Ostrom (1978) Director of the Libraries, MIT Provost Anantha Chandrakasan announced today.

“The title ‘vice provost’ signals the enduring importance of the MIT Libraries in the digital age,” said Chandrakasan.

In 2018, the libraries launched the Center for Research on Equitable and Open Scholarship, with Bourg serving as founding director.

Bourg co-chaired the 2016 Ad Hoc Task Force on the Future of Libraries and has guided the MIT Libraries toward the vision laid out by the task force report.

Prior to joining MIT, Bourg worked for 12 years in the Stanford University Libraries.

5 days, 1 hour назад @ news.mit.edu
MIT announces the MIT for America initiative, to strengthen STEM education across the country
MIT announces the MIT for America initiative, to strengthen STEM education across the country MIT announces the MIT for America initiative, to strengthen STEM education across the country

The initiative represents an Institute-wide effort to address the national challenge of improving STEM education and helping it adapt to shifting societal needs.

MIT for America will leverage the Institute’s longstanding strengths to develop new programs and expand existing projects, while amplifying MIT’s impact on national education.

We think opportunity should be, too.”The initiative is addressing large-scale needs in STEM education.

MIT for America intends to substantially help communities across the country build the bandwidth needed to further develop STEM knowledge and workplace skills.

At MIT, partners in creating the initiative include the MIT Media Lab; MIT RAISE; the MIT pK-12 In…

5 days, 3 hours назад @ news.mit.edu
Computational tools for society’s most complex challenges
Computational tools for society’s most complex challenges Computational tools for society’s most complex challenges

Her research focuses on using machine learning and reinforcement learning (RL) to advance reliable strategies for improving a range of complex systems, including transportation.

“Designing transportation systems consists of modeling and analyzing dozens, if not hundreds or thousands, of variants, which means that an evidence-driven approach to designing those systems is simply not within reach of today’s tools,” Wu says.

The lecture, which Teller gave during an Independent Activities Period robotics competition (that Wu actually won), was the event that honed her particular approach to transportation research, Wu says.

While this could have been a “the rest is history” moment for Wu, RL tur…

1 week, 1 day назад @ news.mit.edu
Documenting the tech worker movement
Documenting the tech worker movement Documenting the tech worker movement

Despite the “dot-com crash” in 2000, the tech industry remained an attractive career destination for many who believed technology represented the future.

But in time, particularly with the start of the first Trump administration, some tech industry employees found themselves questioning if their employers were really intent on supporting policies to support a more democratic world.

Now, Tan and his former tech industry colleague Clarissa Redwine have published a book on the rise and fall of the tech worker labor movement.

“Against Tech Oligarchy: Worker Resistance in the World’s Most Powerful Industry” (Haymarket Books, 2026) chronicles how tech workers organized themselves, the effective s…

1 week, 2 days назад @ news.mit.edu
3 Questions: A new resource to empower young entrepreneurs
3 Questions: A new resource to empower young entrepreneurs 3 Questions: A new resource to empower young entrepreneurs

To fill that gap, the Trust Center created a free, AI-powered youth entrepreneurship platform called Dear Dreamer, made possible through a gift from the Frank and Eileen Foundation.

It adapts the disciplined entrepreneurship framework into a digital, self-paced learning experience featuring short educational videos, interactive exercises, and personalized feedback on the user’s idea.

A: We’ve had a lot of success teaching the disciplined entrepreneurship framework at MIT.

Then we made it a course on the online learning platform edX, and we got hundreds of thousands of people taking the class.

A: It takes the core disciplined entrepreneurship curriculum that we know works from our data, and …

1 week, 2 days назад @ news.mit.edu
New tool lets users repair AI-generated 3D models, then fabricate them just the way they want
New tool lets users repair AI-generated 3D models, then fabricate them just the way they want New tool lets users repair AI-generated 3D models, then fabricate them just the way they want

It pairs Microsoft’s TRELLIS system, which creates 3D models from text and image prompts, with the large language model (LLM) GPT-4, which supports ChatGPT — in other words, visual and textual knowledge combined.

“Language models are great at text and images, while TRELLIS’s talent lies in its ability to create 3D models, since it’s seen so many.”InstructMesh’s strengths come in handy in other, more surprising areas.

The team has TRELLIS recreate popular 3D models found on Thingiverse, a platform home to millions of 3D printable models, to help them find out.

“What they saw is what they got, and the items worked as advertised, so to speak.”While users enjoyed using the InstructMesh, Faruqi …

1 week, 2 days назад @ news.mit.edu
MIT Transit Lab to develop an AI platform for public transit agencies
MIT Transit Lab to develop an AI platform for public transit agencies MIT Transit Lab to develop an AI platform for public transit agencies

This system creates an intense work environment for the transit staff making operations and communications decisions that can affect thousands of passengers relying on transit to get them where they need to go.

The project will build on the group’s decades of experience in applied-research collaborations with transit agencies in major metropolitan areas throughout the world.

Public transit is assessed in the control center and on the streets.

Over decades of work with transit agencies in Washington, D.C., Chicago, London, Boston, Tokyo, and Hong Kong, we have learned to ask a different question.

“However, the vast majority of real-world operational tasks — like delivering public transit ser…

1 week, 4 days назад @ news.mit.edu
This game-playing AI is the new champ at Stratego
This game-playing AI is the new champ at Stratego This game-playing AI is the new champ at Stratego

The AI system achieved greater performance at Stratego than the next best models, while being far cheaper and less computationally demanding to train.

The AI system could be adapted to help humans tackle many real-world problems with hidden information, such as business negotiations or cybersecurity.

The possible piece configurations number more than 10 to the 66th power — an exponentially greater number than in chess — making Stratego extremely difficult for an AI system to play well.

But even with millions of dollars in training costs, these models were still not strong enough to beat top human Stratego players.

Ataraxos beat the strongest Stratego player in the world by a record margin o…

1 week, 4 days назад @ news.mit.edu
Who we become when we talk to machines
Who we become when we talk to machines Who we become when we talk to machines

Turkle explores this terrain in a new book, “Artificial Intimacy: Who We Become When We Talk to Machines,” published today by Little, Brown and Company.

“I feel the story I’m telling is the inner history of technology,” Turkle says.

They start using chatbots, keep using chatbots, and before long seem less interested in human interaction, and less capable of it.

“We’re starting to define being human as not doing the work,” Turkle says.

After all, as Turkle writes in the book, “Chatbots always agree with us and affirm us.

1 week, 5 days назад @ news.mit.edu
The effects of an “algorithmic monoculture” depend on the details
The effects of an “algorithmic monoculture” depend on the details The effects of an “algorithmic monoculture” depend on the details

However, MIT researchers now argue that algorithmic monoculture may not always be as bad as some scientists have suggested.

They systematically evaluated major objections to algorithmic monoculture, including systematic exclusion, and concluded this and many other arguments either fail or aren’t decisive against all forms of monoculture.

To better understand this issue, he and Hedden joined forces to systematically assess the promises and pitfalls of algorithmic monoculture.

Algorithmic monoculture could also cause candidates with the same characteristics and credentials to be hired every time by every firm.

“A lot of the answers around the promises and pitfalls of algorithmic monoculture a…

1 week, 5 days назад @ news.mit.edu
New formulation helps RNA vaccines withstand high temperatures
New formulation helps RNA vaccines withstand high temperatures New formulation helps RNA vaccines withstand high temperatures

RNA vaccines, which have been proven effective against Covid-19, are now being developed for many other diseases, including cancer.

With help from an AI algorithm, the researchers tweaked the formulation surrounding the lipid nanoparticles that are typically used to deliver mRNA vaccines, making the vaccines more heat-resistant.

To create more stable RNA vaccines, researchers have experimented with adding a variety of excipients — sugars, salts, or polymers — to the LNPs.

The researchers also used their new heat-resistant formulation to create solid microneedle patches that could deliver a SARS-CoV-2 antigen.

These patches generated an immune response similar to that produced by the injecta…

1 week, 6 days назад @ news.mit.edu
Berkeley AI
последний пост 2 months, 2 weeks назад
From CUDA to MLX: How K-Search Brings Decades of Kernel Expertise to Apple Silicon
From CUDA to MLX: How K-Search Brings Decades of Kernel Expertise to Apple Silicon From CUDA to MLX: How K-Search Brings Decades of Kernel Expertise to Apple Silicon

From CUDA to MLX: How K-Search Brings Decades of Kernel Expertise to Apple SiliconFigure 1: CUDA-to-MLX optimization translation map.

Although we focus on MLX kernels for Apple Silicon, the method is not specific to MLX and applies to any ecosystem where CUDA expertise is transferable.

With Apple Silicon in hundreds of millions of MacBooks and Mac Studios, MLX enables local AI inference without cloud costs.

Building an MLX backendTo bring K-Search to Apple Silicon, we first built a native MLX backend.

Evaluated on mamba-370m f16, M1 Max 64GB:Metric mlx-mamba (ours) mlx-lm (community) mamba.py Decode 152 tok/s 116 tok/s 40 tok/s Prefill L=512 5,751 tok/s 329 tok/s 1,089 tok/s Prefill L=1024 …

2 months, 2 weeks назад @ bair.berkeley.edu
Teaching LLMs to Update Beliefs for Efficient Long-Horizon Interaction
Teaching LLMs to Update Beliefs for Efficient Long-Horizon Interaction Teaching LLMs to Update Beliefs for Efficient Long-Horizon Interaction

Teaching LLMs to Update Beliefs for Efficient Long-Horizon InteractionOverview of ABBEL compared to traditional recursive summarization.

Belief grading can be thought of as adding an auxiliary RL task, using heuristics designed to capture what makes a good belief as the reward.

With domain-knowledge belief grading, ABBEL approaches or exceeds FULL CTX in this setting; without belief grading, learning is slower.

Context compression methods generate dense representations which, while computationally efficient, sacrifice human-understandability (Kontonis et al., 2026, Eyuboglu et al., 2025, Gupta et al., 2025, Chevalier et al., 2023, Deng et al., 2025, Deng et al., 2025, Bulatov et al., 2022).…

2 months, 2 weeks назад @ bair.berkeley.edu
Intelligence is Free, Now What? Data Systems for, of, and by Agents
Intelligence is Free, Now What?  Data Systems for, of, and by Agents Intelligence is Free, Now What? Data Systems for, of, and by Agents

Agents are rapidly becoming capable of synthesizing entire data systems in one go—meaning we can rebuild custom systems for each new workload.

Data Systems For, Of, and By AgentsNext, we will discuss each in more detail, followed by discussing the intertwined future of data systems and agents, especially as the three challenges intersect.

Data Systems Of AgentsPreviously, we focused on how agents interact with data systems.

Data Systems By AgentsFinally, if intelligence is effectively free, then we can employ this intelligence to synthesize new data systems from scratch.

Co-Evolution of Data Systems and AgentsLooking further out, the boundaries between agents and data systems will likely …

3 months назад @ bair.berkeley.edu
2026 BAIR Graduate Showcase
2026 BAIR Graduate Showcase 2026 BAIR Graduate Showcase

2026 BAIR Graduate ShowcaseCongratulations to the Berkeley Artificial Intelligence Research (BAIR) Lab class of 2026!

This year, BAIR celebrates another remarkable group of Ph.D. graduates whose curiosity, creativity, and perseverance have pushed the frontiers of artificial intelligence and machine learning.

Their work spans the breadth of modern AI — robotics and embodied intelligence, large language models and reasoning, computer vision, generative modeling, AI safety, human-AI interaction, AI for science and healthcare, and much more.

Along the way, they have published influential research, built systems with real-world impact, mentored their peers, and shaped the BAIR community for th…

3 months, 1 week назад @ bair.berkeley.edu
Adaptive Parallel Reasoning: The Next Paradigm in Efficient Inference Scaling
Adaptive Parallel Reasoning: The Next Paradigm in Efficient Inference Scaling Adaptive Parallel Reasoning: The Next Paradigm in Efficient Inference Scaling

Adaptive Parallel Reasoning: The Next Paradigm in Efficient Inference ScalingOverview of adaptive parallel reasoning.

We provide a detailed analysis of recent progress in the field of parallel reasoning, especially Adaptive Parallel Reasoning.

Figure 4: Special Tokens Variants across Adaptive Parallel Reasoning PapersInference Systems for Adaptive ParallelismHow do we actually execute parallel branches?

Figure 14: Difference in Model Choice Across Adaptive Parallel Reasoning PapersEach paper also offers a slightly different interpretation about how adaptive parallel reasoning contributes to the research field.

(Yang et al., 2025; Lian et al., 2025) aim to deliver sequential-AR-model-level a…

5 months назад @ bair.berkeley.edu
Gradient-based Planning for World Models at Longer Horizons
Gradient-based Planning for World Models at Longer Horizons Gradient-based Planning for World Models at Longer Horizons

Large, learned world models are becoming increasingly capable.

Why is adversarial robustness an issue for world model planning?

We thus exploit the differentiability of learned world models $F_{\theta}$, while not falling victim to the inherent sensitivity of the state Jacobians $D_s F_{\theta}$.

It’s a funny sweet spot where the background literature (planning and control overall) is incredibly mature and well-developed, but the current setting (pure planning optimization over modern, large-scale world models) is still heavily underexplored.

But, once we figure out all the right ideas, world model planners will likely become as commonplace as RL.

5 months, 3 weeks назад @ bair.berkeley.edu
Identifying Interactions at Scale for LLMs
Identifying Interactions at Scale for LLMs Identifying Interactions at Scale for LLMs

Identifying Interactions at Scale for LLMsUnderstanding the behavior of complex machine learning systems, particularly Large Language Models (LLMs), is a critical challenge in modern artificial intelligence.

Therefore, grounded or reality-checked interpretability methods must also be able to capture these influential interactions.

In this blog post, we describe the fundamental ideas behind SPEX and ProxySPEX, algorithms capable of identifying these critical interactions at scale.

SPEX and ProxySPEX FrameworkTo discover influential interactions with a tractable number of ablations, we have developed SPEX (Spectral Explainer).

We formalize this through two observations: sparsity (relatively f…

7 months назад @ bair.berkeley.edu
Information-Driven Design of Imaging Systems
Information-Driven Design of Imaging Systems Information-Driven Design of Imaging Systems

We developed a framework that enables direct evaluation and optimization of imaging systems based on their information content.

The first approach treated imaging systems as unconstrained communication channels, ignoring the physical limitations of lenses and sensors.

Our Information-Driven Encoder Analysis Learning (IDEAL) method uses gradient ascent on information estimates to optimize imaging system parameters.

The standard approach to computational imaging design, end-to-end optimization, jointly trains the imaging hardware and a neural network decoder.

The computational efficiency of IDEAL suggests possibilities for designing imaging systems that were previously intractable.

9 months назад @ bair.berkeley.edu
AWS Machine Learning AWS Machine Learning
последний пост 2 days, 2 hours назад
ICYMI: What landed for AI builders in September 2026
ICYMI: What landed for AI builders in September 2026 ICYMI: What landed for AI builders in September 2026

Amazon Bedrock continues expanding access to leading frontier models so you can build and scale AI applications securely.

As AI models become more capable and model choice expands, the industry conversations are shifting.

Amazon Bedrock Managed Agents, powered by OpenAI, is now available in public preview, helping you build production-ready AI agents without sacrificing enterprise security.

Get more control over your enterprise AI agentsKeep agent knowledge current.

As a result, your enterprise AI agents retrieve the latest information.

2 days, 2 hours назад @ aws.amazon.com
How Postman runs Agent Mode for 40 million developers on Amazon Bedrock
How Postman runs Agent Mode for 40 million developers on Amazon Bedrock How Postman runs Agent Mode for 40 million developers on Amazon Bedrock

Agent Mode runs on Amazon Bedrock, which provides managed access to foundation models behind the agent.

Handling tool sprawlIn Agent Mode, tools define how the agent acts inside Postman.

Through Amazon Bedrock model inference APIs, Postman can access supported Anthropic Claude models and route each workload to an appropriate model.

Agent Mode uses Amazon Bedrock cross-Region inference to automatically route requests among the destination Regions defined by an inference profile.

For related implementation guidance, read Effectively use prompt caching on Amazon Bedrock and Amazon Bedrock announces global cross-Region inference for increased throughput on the AWS Machine Learning Blog.

2 days, 2 hours назад @ aws.amazon.com
Pay-per-inference for AI agents: How BlockRun and Incarna use Amazon Bedrock AgentCore payments
Pay-per-inference for AI agents: How BlockRun and Incarna use Amazon Bedrock AgentCore payments Pay-per-inference for AI agents: How BlockRun and Incarna use Amazon Bedrock AgentCore payments

Amazon Bedrock AgentCore payments removes that burden.

In this post, we look at how Incarna used AgentCore payments to let its agents pay BlockRun for model inference one request at a time.

What AgentCore payments providesAmazon Bedrock AgentCore is a platform to build, connect, and optimize agents at scale, with any framework or model.

AgentCore payments is a managed capability of Amazon Bedrock AgentCore that builders can use to add payments to their agents in a few lines of code.

ResultsIncarna put the pay-per-inference flow into production on Base, with BlockRun serving the sell side and AgentCore payments governing every transaction.

3 days назад @ aws.amazon.com
Share GPU clusters across teams with isolation and fairness using Amazon SageMaker HyperPod
Share GPU clusters across teams with isolation and fairness using Amazon SageMaker HyperPod Share GPU clusters across teams with isolation and fairness using Amazon SageMaker HyperPod

Amazon SageMaker HyperPod is a purpose-built AI service that simplifies the management of large-scale compute clusters for gen AI workloads.

In this post, we present a reference architecture for building a multi-tenant environment on Amazon SageMaker HyperPod with EKS.

Why AWS IAM Identity CenterAWS IAM Identity Center (successor to AWS Single Sign-On) provides a single place to manage workforce identities across AWS accounts and applications.

Identity Center group assignment – Add the corresponding Identity Center group (for example, the TeamA group) to the domain.

Learn more: Kubecost on SageMaker HyperPod · KubecostConclusionThis post presented a reference architecture for building multi…

3 days, 2 hours назад @ aws.amazon.com
Introducing Claude Haiku 5.5 on AWS
Introducing Claude Haiku 5.5 on AWS Introducing Claude Haiku 5.5 on AWS

Today, we’re excited to announce the availability of Claude Haiku 5.5 on Amazon Bedrock and Claude Platform on AWS.

According to Anthropic, Claude Haiku 5.5 is the fastest and most efficient model in the Claude 5.5 family, built for subagents and high-volume, cost-sensitive work.

What makes Claude Haiku 5.5 differentClaude Haiku 5.5 is Anthropic’s most capable Haiku model, across coding, tool use, computer use, and agentic tasks.

Pairing Claude Haiku 5.5 with Opus 5.5Haiku 5.5 pairs with the recently announced Claude Opus 5.5.

Getting started with Claude Haiku 5.5 on Amazon BedrockTo try Haiku 5.5, open the Amazon Bedrock console, choose Test, then Playground, and select Haiku 5.5 as the mo…

3 days, 23 hours назад @ aws.amazon.com
Rethinking access control for RAG with Amazon Quick and Amazon Bedrock
Rethinking access control for RAG with Amazon Quick and Amazon Bedrock Rethinking access control for RAG with Amazon Quick and Amazon Bedrock

In this post, we explore how Amazon Quick and Amazon Bedrock Knowledge Bases solve this challenge through real-time access control list (ACL) enforcement, verifying permissions directly with authoritative sources at query time.

Here’s how it typically works:A data source connector (for example, SharePoint connector) pulls ACLs as part of a periodic sync job.

Amazon Quick’s approach to real-time access control answered that question definitively and demonstrated a level of rigor that stood out throughout our evaluation.

ConclusionIn this post, we talked about how Amazon Quick and Amazon Bedrock Knowledge Bases implement real-time ACL enforcement to solve a critical security challenge for ent…

3 days, 23 hours назад @ aws.amazon.com
Beyond hours saved: Building the business case for agentic automation
Beyond hours saved: Building the business case for agentic automation Beyond hours saved: Building the business case for agentic automation

Agentic automation, software that reasons and adapts to complete tasks, is showing up on AI center of excellence (AI CoE) roadmaps.

In this post, we introduce a framework AI CoE leaders can use to build a business case that captures the full value of agentic automation.

However, most companies invert this formula entirely” (McKinsey, “Agentic AI change management: Closing the adoption gap,” 2026).

We assume the value of automation lives in the task, but in agentic automation most of it lives around the task: the judgment, the exceptions, the coordination across systems.

ConclusionThe question is where agentic automation delivers value that your existing tools can’t, and how to prove it befo…

4 days, 2 hours назад @ aws.amazon.com
How Qlik built grounded, enterprise-scale AI with Amazon Bedrock
How Qlik built grounded, enterprise-scale AI with Amazon Bedrock How Qlik built grounded, enterprise-scale AI with Amazon Bedrock

Building grounded AI on Amazon Bedrock, Qlik Answers tackles a common enterprise problem: employees aren’t short on data.

Qlik, a global leader in data integration, data quality, analytics, and AI, built Qlik Answers to solve that problem for its more than 40,000 customers worldwide.

This post explains how Qlik built the tool behind that adoption, and how Amazon Bedrock supports it at global scale.

Why Amazon BedrockQlik evaluated its model strategy against the three problems described earlier, and Amazon Bedrock addressed each one directly.

To see what Qlik Answers can do with your data, start a free trial of Qlik Cloud Analytics, request a Qlik Answers demo or a Qlik and AWS demo, or visi…

4 days, 2 hours назад @ aws.amazon.com
Automate remediation post AWS DevOps Agent investigation
Automate remediation post AWS DevOps Agent investigation Automate remediation post AWS DevOps Agent investigation

In this post, we demonstrate how to use AWS Lambda Durable Functions, a capability of AWS Lambda, Amazon EventBridge, and Amazon Bedrock to create an automated remediation workflow that complements AWS DevOps Agent to complete the issue resolution step.

Start an investigation with AWS DevOps AgentOpen the AWS DevOps Agent console, navigate to your agent space, and ask: “What is happening with the devops-agent-timeout function?”The investigation starts and takes a few minutes to complete.

During this time, AWS DevOps Agent autonomously correlates CloudWatch metrics, logs, and the function’s configuration to determine the root cause.

The rule triggers the devops-agent-trigger Lambda function,…

4 days, 2 hours назад @ aws.amazon.com
Building AI builders: Playbook for closing the AI knowledge-capability gap
Building AI builders: Playbook for closing the AI knowledge-capability gap Building AI builders: Playbook for closing the AI knowledge-capability gap

Given the pace at which agentic AI tools have become generally available, most of them have never built anything with the tools they’re discussing.

We asked business professionals, people who work with AI tools daily but aren’t writing production code, what held them back with AI adoption.

The answer wasn’t “I don’t want to learn.” 90 percent wanted hands-on experience building AI agents.

Six weeks later, they presented their prototype, WealthWise, a multi-agent AI financial advisory tool, that won first place.

What they built:Five specialized AI agents delivering intelligent financial advisory: portfolio analysis, risk assessment, financial planning, market insights, and personalized inves…

4 days, 2 hours назад @ aws.amazon.com
How Cornerstone OnDemand cut database diagnosis by 78% with Amazon Bedrock
How Cornerstone OnDemand cut database diagnosis by 78% with Amazon Bedrock How Cornerstone OnDemand cut database diagnosis by 78% with Amazon Bedrock

The company built a multi-agent AI system that transforms database operations from reactive firefighting into proactive, self-orchestrating workflows.

The system, called Orion AI, uses Amazon Bedrock and Strands Agents, an open source agent orchestration framework from AWS, to coordinate specialized agents.

With Orion AI, database diagnosis dropped from 45 minutes to 10, a 78% reduction.

From the engineer’s perspective, the work is reduced to prompting Orion AI and validating the findings it reports back.

Orion AI reduced redundant alerts by a median of 65 percent through deduplication, threshold filtering, and cross-signal correlation.

4 days, 2 hours назад @ aws.amazon.com
Building a context-aware AI assistant on AgentCore and OpenClaw
Building a context-aware AI assistant on AgentCore and OpenClaw Building a context-aware AI assistant on AgentCore and OpenClaw

AgentCore memory, a capability of Amazon Bedrock AgentCore, turns disposable chats into durable knowledge.

Both call the InvokeAgentRuntime API on the AgentCore runtime, where a thin server.py process coordinates the OpenClaw gateway, AgentCore memory, and the Amazon Bedrock Converse API.

PrerequisitesTo deploy your own version using the Launch Stack button or scripts/ deploy.sh (described in the Grow your own section), you will need:Amazon Bedrock AgentCore access, including AgentCore runtime and AgentCore memory.

Persisting the turn and closing the loopAfter the model responds, server.py calls CreateEvent with both the user turn and the assistant turn.

Delete the AgentCore memory store (a…

4 days, 23 hours назад @ aws.amazon.com
Responsible AI governance: How AWS positions customers to align with ISO/IEC 42005:2025
Responsible AI governance: How AWS positions customers to align with ISO/IEC 42005:2025 Responsible AI governance: How AWS positions customers to align with ISO/IEC 42005:2025

In this post we explore the AI system impact assessment: what it is, how it improves enterprise-wide risk management, and how ISO/IEC 42005 codifies AI system impact assessment best practices.

AI system impact assessmentsAn AI system impact assessment is a documented process of AI system risk identification by which organizations developing, providing, or using AI systems consider impacts to the organization, individuals, communities, groups, and societies.

How ISO/IEC 42005 connects you to your AI governance processISO/IEC 42005 unlocks a more integrated AI governance process for customers.

Specifically, the standard provides guidance on how to develop the content of AI system impact asses…

5 days, 2 hours назад @ aws.amazon.com
Best practices for Amazon SageMaker HyperPod administration and governance
Best practices for Amazon SageMaker HyperPod administration and governance Best practices for Amazon SageMaker HyperPod administration and governance

In this post, we show how to administer SageMaker HyperPod through SageMaker Unified Studio while preserving the underlying governance controls.

Amazon SageMaker HyperPod is a capability of Amazon SageMaker AI.

If you need guidance creating a cluster, refer to the Amazon SageMaker HyperPod documentation or the AI on SageMaker HyperPod site.

The documentation for SageMaker HyperPod in SageMaker AI Studio explains that SageMaker AI Studio users can see all Amazon EKS cluster tasks by default.

The post Best practices for Amazon SageMaker HyperPod task governance explains fair-share weights, quotas, lending and borrowing, priority classes, and common allocation scenarios.

5 days, 2 hours назад @ aws.amazon.com
Manage Amazon SageMaker HyperPod Spaces directly from SageMaker Studio
Manage Amazon SageMaker HyperPod Spaces directly from SageMaker Studio Manage Amazon SageMaker HyperPod Spaces directly from SageMaker Studio

We recently introduced the ability to create and manage Amazon SageMaker Spaces on Amazon SageMaker HyperPod EKS clusters directly from the Amazon SageMaker Studio UI.

Earlier this year, we launched Amazon SageMaker Spaces for HyperPod, an add-on ML developers can use to create interactive development environments directly on HyperPod EKS clusters.

What’s newWith this new capability, data scientists can now create, configure, start, stop, and open Spaces directly from SageMaker Studio.

Enable per-user identity propagation on the Studio domain: If your Studio domain was created before the SageMaker Studio and HyperPod Spaces integration was rolled out, you must enable per-user identity propa…

5 days, 2 hours назад @ aws.amazon.com
NVIDIA
последний пост 2 days, 21 hours назад
Into the Omniverse: How Developers Turn Ideas Into Simulations With Frontier AI Agents
Into the Omniverse: How Developers Turn Ideas Into Simulations With Frontier AI Agents Into the Omniverse: How Developers Turn Ideas Into Simulations With Frontier AI Agents

Developers are combining frontier AI models with NVIDIA Omniverse libraries to help carry out that work — building applications for exploring scenarios, investigating failures and improving designs.

Frank DeLise, Omniverse product manager at NVIDIA, used Astra to turn a SimReady warehouse and humanoid robot into an interactive simulator with first- and third-person views.

Learn how to prepare and validate SimReady robot assets with frontier AI models and NVIDIA Omniverse libraries.

Connect an Autonomous-Driving Testing Workflow 🔗Changing a scene, sensor or driving model can significantly affect autonomous-vehicle simulations.

Explore NVIDIA Omniverse libraries to start building with an AI a…

2 days, 21 hours назад @ blogs.nvidia.com
Building Reliable Data Analytics Agents: Lessons from the KDD Cup
Building Reliable Data Analytics Agents: Lessons from the KDD Cup Building Reliable Data Analytics Agents: Lessons from the KDD Cup

Learn moreThe NVIDIA KGMON team placed second in the KDD Cup 2026 Data Agents competition with a system built around a simple idea of making an agent’s harness smaller, clearer, and easier to verify.

It isn’t a general recipe for every data science agent, but the broader lesson applies to many agent systems.

Too many ways to inspect data, call tools, write files, or recover from mistakes can lead to failures.

The harness preprocesses data, limits the agent’s tools, and preserves state, with execution traces supporting evaluation and refinementThe following techniques offer practical guidance for building reliable data analytics agents.

For additional architecture examples and implementation…

3 days назад @ developer.nvidia.com
Rally Up: ‘Gears of War: E-Day’ Launches on GeForce NOW
Rally Up: ‘Gears of War: E-Day’ Launches on GeForce NOW Rally Up: ‘Gears of War: E-Day’ Launches on GeForce NOW

Gears of War: E-Day leads the charge on GeForce NOW this week, bringing Marcus Fenix and Dom Santiago’s first fight against the Locust Horde to the cloud with GeForce RTX-powered performance.

Emergence Day Is HereGears of War: E-Day is now streaming on GeForce NOW following its global release on Tuesday, Oct. 6.

Ultimate members can take on the Horde with GeForce RTX 5080-class performance in the cloud, plus technologies including NVIDIA DLSS and NVIDIA Reflex.

Gamers who want to test out high-performance GeForce NOW cloud gaming can start with a day pass to try premium cloud gaming before committing to a membership.

Better yet, the cost of the day pass can be applied toward a first monthly…

3 days, 5 hours назад @ blogs.nvidia.com
NVIDIA, Microsoft Kick Off a New Beginning for Windows PCs With RTX Spark and AI Agents
NVIDIA, Microsoft Kick Off a New Beginning for Windows PCs With RTX Spark and AI Agents NVIDIA, Microsoft Kick Off a New Beginning for Windows PCs With RTX Spark and AI Agents

Introducing Surface Laptop Ultra, Pavan Davuluri tied that vision to NVIDIA RTX Spark.

“We built Surface Laptop Ultra around NVIDIA RTX Spark.

RTX Spark combines an NVIDIA Blackwell RTX GPU with up to 6,144 cores, and an up to 20-core NVIDIA Grace CPU connected at 600 GB/s.

One petaflop of FP4 AI performance and up to 128GB unified memory makes RTX Spark effective for local AI.

Follow NVIDIA RTX Spark on X, Instagram, TikTok and Facebook — and stay informed by subscribing to the NVIDIA Local AI newsletter.

3 days, 23 hours назад @ blogs.nvidia.com
Faster Scientific Image Analysis with NVIDIA cuPhoton
Faster Scientific Image Analysis with NVIDIA cuPhoton Faster Scientific Image Analysis with NVIDIA cuPhoton

Observatories and telescopes, lasers and X-ray light sources, and other high-throughput instruments generate image data faster than CPU-bound pipelines can process it to support timely decisions.

NVIDIA cuPhoton is an open-source NVIDIA CUDA-X toolkit of GPU-accelerated building blocks for that path, spanning use cases from spectral and optical astronomy to time-domain laser/X-ray analysis.

NVIDIA cuPhoton package componentsAccelerating scientific insights from months to minutes with cuPhotonAcross astronomy, X-ray science, and other high-throughput domains, NVIDIA cuPhoton provides tools for loading, processing, and analyzing massive multidimensional datasets.

(Bottom panel) NVIDIA cuPhoto…

4 days, 3 hours назад @ developer.nvidia.com
Why Telecom Operators Are Building Their AI Strategy on Open Models
Why Telecom Operators Are Building Their AI Strategy on Open Models Why Telecom Operators Are Building Their AI Strategy on Open Models

Telecom operators are increasingly building their AI strategies on open models — and the reasons go beyond mere cost.

They enable flexible, secure deployment: teams can size and optimize open models to run across public clouds, private infrastructure and edge environments.

Scale Open Models Into Production WorkflowsOpen models are a critical building block, but it takes more than models to bring autonomous telecom operations safely into production.

Create a Platform for Local AI InnovationAs telecom operators build AI infrastructure aligned with national AI strategies, open models are giving them a foundation to deliver AI services tailored to local languages, industries, regulations and da…

5 days, 5 hours назад @ blogs.nvidia.com
From Scan to Treatment Plan, AI Helps Close Breast Cancer’s Deadliest Gaps
From Scan to Treatment Plan, AI Helps Close Breast Cancer’s Deadliest Gaps From Scan to Treatment Plan, AI Helps Close Breast Cancer’s Deadliest Gaps

Breast cancer is the most commonly diagnosed cancer among American women — yet the gaps in care are wide.

The companies below are addressing both ends of that gap, and everything in between, accelerated by NVIDIA AI infrastructure.

Finding Cancers, Cutting False AlarmsAnother NVIDIA Inception company, Whiterabbit.ai, develops AI technology for breast cancer screening.

Providing Tumor Insights With 3D VisualizationAnother NVIDIA Inception company, SimBioSys, joined NVIDIA on a recent panel marking Breast Cancer Awareness Month.

“NVIDIA technology gives us the computing power to take hundreds or thousands of images, apply our AI and analyze them quickly,” Stevens said.

6 days, 5 hours назад @ blogs.nvidia.com
NVIDIA DGX Spark 64GB Gives Developers More Ways to Build and Scale Local AI
NVIDIA DGX Spark 64GB Gives Developers More Ways to Build and Scale Local AI NVIDIA DGX Spark 64GB Gives Developers More Ways to Build and Scale Local AI

And when workloads grow, two units can cluster together via NVIDIA Sync Cluster Assistant without any additional setup.

A New Starting Point for Personal AI SupercomputingDGX Spark combines NVIDIA Grace Blackwell compute, unified memory, NVIDIA ConnectX-7 networking and an NVIDIA CUDA-accelerated AI software stack in one system.

Developer Use Cases on DGX SparkThe new DGX Spark 64GB configuration supports practical work from day one.

It runs locally on NVIDIA RTX GPUs, DGX Spark and DGX Station, giving creators more ways to create and refine images on their own hardware.

Follow NVIDIA RTX Spark on X, Instagram, TikTok and Facebook — and stay informed by subscribing to the NVIDIA Local AI ne…

1 week, 2 days назад @ blogs.nvidia.com
How NVIDIA GPUs Help Accelerate OpenAI’s GPT-6 Astra Ultrafast
How NVIDIA GPUs Help Accelerate OpenAI’s GPT-6 Astra Ultrafast How NVIDIA GPUs Help Accelerate OpenAI’s GPT-6 Astra Ultrafast

GPT-6 Astra Ultrafast, running on NVIDIA Blackwell GPUs, is available now in the OpenAI API and to eligible ChatGPT Work and Codex users.

Accelerated by inference optimizations through OpenAI’s models that tap into the capabilities of the NVIDIA Blackwell architecture, Ultrafast offers up to 8x faster token generation than the Astra Standard mode.

With Astra Ultrafast, that means faster model responses as agents write code, use tools and work through complex tasks.”Continually Improving PerformancePerformance gains don’t stop when a model is deployed.

OpenAI is using its own models to help refine the inference software running on NVIDIA GPUs, taking advantage of the platform’s programmabili…

1 week, 2 days назад @ blogs.nvidia.com
Fall Into 25 New Games on GeForce NOW This October
Fall Into 25 New Games on GeForce NOW This October Fall Into 25 New Games on GeForce NOW This October

Alongside falling leaves, pumpkin spice and everything nice, 25 new games are joining GeForce NOW throughout October, including six ready to play this week.

Claim RewardsCONTROL Resonant is streaming from the cloud for GeForce NOW Performance and Ultimate members.

GeForce NOW availability may vary, as games are onboarded after they are released and added throughout the week.

Keep an eye on GeForce NOW channels and GFN Thursdays for availability updates on announced titles.

Gamers who want to test out high-performance GeForce NOW cloud gaming can start with a day pass to try premium cloud gaming before committing to a membership.

1 week, 3 days назад @ blogs.nvidia.com
Productive, Durable, Fungible: How NVIDIA AI Factories Maximize Return on Investment
Productive, Durable, Fungible: How NVIDIA AI Factories Maximize Return on Investment Productive, Durable, Fungible: How NVIDIA AI Factories Maximize Return on Investment

Each megawatt factory costs roughly $60 million, and AI factory operators will only commit capital on that scale with a clear view of the return on investment.

NVIDIA AI factories are engineered to maximize all three.

NVIDIA AI factories run every type of AI model — open and proprietary — across language, vision, biology, physics and robotics.

NVIDIA AI factories are engineered to be productive, durable and fungible: more profitable tokens, longer useful life and deeper demand.

Learn more about NVIDIA AI factories by tuning in to NVIDIA founder and CEO Jensen Huang’s GTC Berlin keynote on Wednesday, Oct. 21, at 11 a.m. CEST.

1 week, 3 days назад @ blogs.nvidia.com
NVIDIA Opens Applications for 2027–2028 Graduate Fellowships With Awards Up to $60,000
NVIDIA Opens Applications for 2027–2028 Graduate Fellowships With Awards Up to $60,000 NVIDIA Opens Applications for 2027–2028 Graduate Fellowships With Awards Up to $60,000

To foster such innovation, the NVIDIA Graduate Fellowship Program provides grants, mentors and technical support to doctoral students doing outstanding research relevant to NVIDIA technologies.

It focuses on supporting students working in AI, machine learning, autonomous vehicles, computer graphics, robotics, healthcare, high-performance computing and related fields.

Since its start in 2002, the Graduate Fellowship Program has awarded over 220 grants worth around $8 million.

An in-person internship at an NVIDIA research office preceding the fellowship year is mandatory; eligible candidates must be available for the internship in summer 2027.

Featured image shows last year’s NVIDIA Graduate …

1 week, 4 days назад @ blogs.nvidia.com
From Training to Production, NVIDIA and CoreWeave Close the Loop on Agentic AI
From Training to Production, NVIDIA and CoreWeave Close the Loop on Agentic AI From Training to Production, NVIDIA and CoreWeave Close the Loop on Agentic AI

At CoreWeave Fully Connected, running this week in San Francisco, CoreWeave announced availability of NVIDIA Vera Rubin NVL72 systems with Spectrum-X 102.4T Ethernet networking.

CoreWeave will also offer NVIDIA Vera, the first CPU built for AI agents.

In addition, CoreWeave launched CoreWeave Forge, a connected environment for training, evaluating and improving models and agents on NVIDIA accelerated computing.

Capacity can be operated through CoreWeave Kubernetes Service, SUNK, CoreWeave Mission Control, CoreWeave Sandboxes and CoreWeave Inference.

CoreWeave Agent Lens — a new service — turns production agent observability into continuous improvement and understandable insights.

1 week, 4 days назад @ blogs.nvidia.com
Efficient MoE Training for Biological Foundation Models
Efficient MoE Training for Biological Foundation Models Efficient MoE Training for Biological Foundation Models

NVIDIA Transformer Engine (TE) helps address these bottlenecks with optimized primitives for grouped expert computation, kernel fusion, and low-precision training.

As biological foundation models grow in parameter count and sequence length, these primitives can improve GPU efficiency while expanding model capacity.

Together, these capabilities provide a practical reference for efficiently training MoE-based biological foundation models.

The BioNeMo recipe uses TE to support FP8 and MXFP8 training, reducing memory use.

Try the Mixtral Native Transformer Engine recipe in BioNeMo Recipes and learn more about the optimized MoE kernels in the NVIDIA Transformer Engine documentation.

2 weeks, 3 days назад @ developer.nvidia.com
How Open Science Can Help Researchers Prepare for the Next Pandemic
How Open Science Can Help Researchers Prepare for the Next Pandemic How Open Science Can Help Researchers Prepare for the Next Pandemic

“This database is an engine for hypothesis generation,” said Chris Dallago, applied research science team lead in digital biology at NVIDIA.

Traditional methods for determining protein structures — crystallizing proteins and shooting X-rays at them — can take years and cost thousands of dollars per structure.

For this project, the team systematically worked through the protein structures of viral families known to infect humans, from common-cold viruses to emerging threats like Mpox.

“Making this data open is critical for understanding viral diagnostics and developing treatments and vaccines,” said Jo McEntyre, interim director of EMBL-EBI.

The structures show what viral complexes may look …

2 weeks, 3 days назад @ blogs.nvidia.com
Facebook
последний пост 1 month, 1 week назад
An Organizational Second Brain: Building an AI That Learns From Experts
An Organizational Second Brain: Building an AI That Learns From Experts An Organizational Second Brain: Building an AI That Learns From Experts

Recipes reference knowledge files but contain no domain facts; knowledge files state positions but prescribe no procedures.

This means:Adding an organizational position means adding a knowledge file and updating a routing index.

Every expert correction moves through four phases:Diagnose expert feedback into actionable issues with their root cause.

The requirements for adopting this architecture are:A structured knowledge system with explicit file boundaries, cross-references, and a dependency graph (the organizational second brain for the domain).

Every improvement is a text edit that a domain expert can review in 30 seconds.

1 month, 1 week назад @ engineering.fb.com
From User Sequences to Scaling Laws: A Multi-Stage Architecture for Meta’s Ads Ranking
From User Sequences to Scaling Laws: A Multi-Stage Architecture for Meta’s Ads Ranking From User Sequences to Scaling Laws: A Multi-Stage Architecture for Meta’s Ads Ranking

Introducing the Multi-Stage Sequence ModelTo address scaling efficiency, a multi-stage model has been developed that enables scaling of a transformer-based sequence model in a compute efficient manner.

Second Stage: Online Ranking ModelThe offline user model representations are complemented with online ranking models that use fresh user signals and ad candidate information for real time ranking.

A Predictable Scaling CurveLLM-Style Scaling LawWhen running on real-world ads traffic, the multi-stage sequence model demonstrates the emergence of predictable scaling laws for ads recommendations that are analogous to those observed in large language models.

The Impact of Multi-Stage Sequence Mode…

2 months назад @ engineering.fb.com
GEM Training: How Meta Doubled the Efficiency of Its LLM-Scale Ads Foundation Model
GEM Training: How Meta Doubled the Efficiency of Its LLM-Scale Ads Foundation Model GEM Training: How Meta Doubled the Efficiency of Its LLM-Scale Ads Foundation Model

We tackled these challenges through complementary compute efficiency and scaling efficiency innovations: Compute efficiency : Achieved through a customized recommendation kernel library — Jagged Flash Attention (JFA), Generalized Dot-Product Attention (GDPA), BlockAttention, etc.

The results: we doubled GEM’s E2E training efficiency to 20-25% MFU while scaling total training FLOPs 4x over the past 12 months.

We measure training efficiency through E2E MFU, which decomposes into two factors:E2E MFU = Local MFU (compute efficiency) × Scaling Ratio (scaling efficiency)These factors describe two related but distinct optimization problems.

Local MFU (compute efficiency) measures how well a single…

2 months, 1 week назад @ engineering.fb.com
Exploring Hierarchical Interest Representation For Meta Ads Deep Funnel Optimization
Exploring Hierarchical Interest Representation For Meta Ads Deep Funnel Optimization Exploring Hierarchical Interest Representation For Meta Ads Deep Funnel Optimization

Hierarchical Interest Representation is an upstream representation layer designed to improve upon Meta’s deep funnel ranking optimization.

How Hierarchical Interest Representation Enhances Deep Funnel OptimizationHierarchical Interest Representation pioneers a structural shift in representation modeling by navigating long-range graph topologies and distilling sparse engagement signals into unified interest clusters at various granularities.

This aims to enable the delivery of more relevant ad content to optimize deep funnel ads.

Hierarchical Interest Representation learns super graphs, which cascade through multiple hierarchical layers for this flexibility, accommodating ranking modeling ar…

2 months, 4 weeks назад @ engineering.fb.com
Modernizing the Meta Ads Service With an Open-Source Kernel Scheduler
Modernizing the Meta Ads Service With an Open-Source Kernel Scheduler Modernizing the Meta Ads Service With an Open-Source Kernel Scheduler

Why Ads Latency MattersMeta’s ads serving fleet handles more than 5 million requests per second on average at the serving platform entry point, which is over 400 billion per day across all monetized surfaces1.

That is why our Ads and Linux Kernel teams have been working together to build a scheduling policy customized to the ads delivery workload using sched_ext, the upstream, BPF-based extensible scheduling framework.

Until now, we have been using the general-purpose schedulers typically integrated in the Linux kernel (CFS and EEVDF) that balance threads across CPUs with no understanding of the workload.

It has already been deployed in several services at Meta, delivering meaningful reduct…

3 months назад @ engineering.fb.com
10 Years of Meta’s Commitment to Python
10 Years of Meta’s Commitment to Python 10 Years of Meta’s Commitment to Python

This year marks Meta’s 10th consecutive year as a sponsor of the Python Software Foundation (PSF), the charitable organization dedicated to advancing, supporting, and protecting the open-source Python programming language and the community that sustains it.

Some of the core maintainers of Python are Meta engineers who have authored new features and Python Enhancement Proposals (PEPs) for the Python community.

These improvements are vital for protecting the global Python community and ensuring that developers everywhere – including our own engineers – can safely share and consume packages.

These investments help grow the Python community and foster the new talent that is essential for Python…

3 months, 1 week назад @ engineering.fb.com
Privacy-Aware Infrastructure in the AI-Native Era: An Asset Classification Case Study
Privacy-Aware Infrastructure in the AI-Native Era: An Asset Classification Case Study Privacy-Aware Infrastructure in the AI-Native Era: An Asset Classification Case Study

Why Asset Classification MattersAsset classification is the foundation for many privacy controls.

The rest of this post walks through those pieces using asset classification as the case study.

All three share a single judge model, a larger reasoning model deliberately different from the classifier model.

Distill Stable Behavior Into RulesEven a strong LLM classifier should not be the default enforcement path forever.

Expand to other PAI workflows: The same pattern (context → LLM reasoning → distillation → deterministic enforcement) applies to lineage validation, purpose-boundary checking, and retention policy assignment.

3 months, 2 weeks назад @ engineering.fb.com
SilverTorch: Index as Model — A New Retrieval Paradigm for Recommendation Systems
SilverTorch: Index as Model — A New Retrieval Paradigm for Recommendation Systems SilverTorch: Index as Model — A New Retrieval Paradigm for Recommendation Systems

The retrieval system within industry recommendation systems have consisted of microservices stitched together, with neural networks inconsistently integrated.

Under Index as Model previous microservice-based item indices used for retrieval become a tensor inside the model.

Moving From Microservice Mesh to One Integrated Neural NetworkThe Microservice Paradigm We ReplacedTraditional recommendation retrieval is built as a mesh of microservices.

We call this Index as Model: Every retrieval component — the item index, eligibility filter, scoring layer and user tower — becomes a tensor or operator inside a single PyTorch model.

Index FreshnessWith index as a model module, maintaining index fresh…

4 months, 2 weeks назад @ engineering.fb.com
Reel Friends: Building Social Discovery that Scales to Billions
Reel Friends: Building Social Discovery that Scales to Billions Reel Friends: Building Social Discovery that Scales to Billions

On its face the new Friend Bubbles feature looks simple enough.

It highlights Reels your friends have watched and reacted to.

On this episode of the Meta Tech Podcast, Pascal Hartig chats with Subasree and Joseph, two software engineers from the Facebook Reels team, about what it took to bring Friend Bubbles to life.

If you’ve ever underestimated a “simple” feature, this one’s for you.

And if you’re interested in learning more about career opportunities at Meta visit the Meta Careers page.

5 months назад @ engineering.fb.com
Modernizing the Facebook Groups Search to Unlock the Power of Community Knowledge
Modernizing the Facebook Groups Search to Unlock the Power of Community Knowledge Modernizing the Facebook Groups Search to Unlock the Power of Community Knowledge

We’ve fundamentally transformed Facebook Groups Search to help people more reliably discover, sort through, and validate community content that’s most relevant to them.

We’ve adopted a new hybrid retrieval architecture and implemented automated model-based evaluation to address the major friction points people experience when searching community content.

Addressing the Friction Points in Community KnowledgePeople struggle with three friction points when searching for answers in community content – discovery, consumption, and validation.

The Solution: A Modernized Hybrid Retrieval ArchitectureWe engineered a hybrid retrieval architecture that powers a discussions module on Facebook Search.

R…

5 months, 3 weeks назад @ engineering.fb.com
Capacity Efficiency at Meta: How Unified AI Agents Optimize Performance at Hyperscale
Capacity Efficiency at Meta: How Unified AI Agents Optimize Performance at Hyperscale Capacity Efficiency at Meta: How Unified AI Agents Optimize Performance at Hyperscale

We’ve built a unified AI agent platform that encodes the domain expertise of senior efficiency engineers into reusable, composable skills.

Introducing the Capacity Efficiency ProgramWhen the code you ship serves more than 3 billion people, even a 0.1% performance regression can translate to significant additional power consumption.

Many engineers at Meta use our efficiency tools to work on these problems every day.

Skills : These encode domain expertise about performance efficiency.

The pipeline mirrors the defensive AI Regression Solver:Gather context with tools: The AI agent looks up: Opportunity metadata.

5 months, 4 weeks назад @ engineering.fb.com
How Meta Used AI to Map Tribal Knowledge in Large-Scale Data Pipelines
How Meta Used AI to Map Tribal Knowledge in Large-Scale Data Pipelines How Meta Used AI to Map Tribal Knowledge in Large-Scale Data Pipelines

Challenging the Conventional Wisdom on AI Context FilesRecent academic research found that AI-generated context files actually decreased agent success rates on well-known open-source Python repositories.

Our codebase is the opposite: proprietary config-as-code with tribal knowledge that exists nowhere in any model’s training data.

Any team with a large, proprietary codebase can benefit:Identify your tribal knowledge gaps.

What’s NextWe are expanding context coverage to additional pipelines across Meta’s data infrastructure and exploring tighter integration between context files and code generation workflows.

This approach turned undocumented tribal knowledge into structured, AI-readable con…

6 months, 1 week назад @ engineering.fb.com
KernelEvolve: How Meta’s Ranking Engineer Agent Optimizes AI Infrastructure
KernelEvolve: How Meta’s Ranking Engineer Agent Optimizes AI Infrastructure KernelEvolve: How Meta’s Ranking Engineer Agent Optimizes AI Infrastructure

This is the second post in the Ranking Engineer Agent blog series exploring the autonomous AI capabilities accelerating Meta’s Ads Ranking innovation.

We introduce KernelEvolve, an agentic kernel authoring system used by Ranking Engineer Agent and generally applicable to a range of AI models beyond Ads Ranking.

Unlike typical large language model (LLM)-based agents that perform one-shot code generation, KernelEvolve treats kernel optimization as a search problem.

A standard coding assistant lacks the context to write optimized MTIA kernels because it has never seen MTIA documentation, instruction set details, or programming idioms.

KernelEvolve represents an early step toward the vision of …

6 months, 1 week назад @ engineering.fb.com
Meta Adaptive Ranking Model: Bending the Inference Scaling Curve to Serve LLM-Scale Models for Ads
Meta Adaptive Ranking Model: Bending the Inference Scaling Curve to Serve LLM-Scale Models for Ads Meta Adaptive Ranking Model: Bending the Inference Scaling Curve to Serve LLM-Scale Models for Ads

To overcome this, we have developed the Meta Adaptive Ranking Model, which effectively bends the inference scaling curve with high ROI and industry-leading efficiency.

Introducing Meta Adaptive Ranking ModelServing LLM-scale & complexity models in a real-time ads recommendation environment requires resolving a fundamental tension between model complexity and system efficiency.

Adaptive Ranking Model addresses these challenges through a paradigm shift powered by three core innovations across the serving stack:Inference-efficient model scaling: Adaptive Ranking Model achieves a model complexity equivalent to the O(10 GFLOPs) per token used by top-tier LLMs.

To minimize compute overhead, Adapt…

6 months, 2 weeks назад @ engineering.fb.com
AI for American-Produced Cement and Concrete
AI for American-Produced Cement and Concrete AI for American-Produced Cement and Concrete

Concurrent with the 2026 American Concrete Institute (ACI) Spring Convention, Meta is releasing a new AI model for designing concrete mixes – Bayesian Optimization for Concrete (BOxCrete), as well as the foundational data used to develop award-winning concrete mixes.

Amrize operates 18 cement plants, 141 cement terminals and 269 ready-mix concrete sites across North America.

Alongside the event, Meta is releasing a new AI model for designing concrete mixes, Bayesian Optimization for Concrete (BOxCrete).

How Meta Leverages AI for Concrete MixturesMeta’s AI for concrete model can help suppliers more quickly incorporate U.S. materials into their mixes through an approach called adaptive experi…

6 months, 2 weeks назад @ engineering.fb.com
Uber Engineering
последний пост None
neptune.ai neptune.ai
последний пост None
▶️ YouTube
Yannic Kilcher Yannic Kilcher
последний пост 7 months, 1 week назад
I BUILT A FULLY AUTOMATIC MANSPLAINER
I BUILT A FULLY AUTOMATIC MANSPLAINER I BUILT A FULLY AUTOMATIC MANSPLAINER

All information about GTC and the DGX Spark Raffle is here: https://www.ykilcher.com/gtc Links:

Homepage: https://ykilcher.com

Merch: https://ykilcher.com/merch

YouTube: https://www.youtube.com/c/yannickilcher

Twitter: https://twitter.com/ykilcher

Discord: https://ykilcher.com/discord

LinkedIn: https://www.linkedin.com/in/ykilcher If you want to support me, the best thing to do is to share out the content :) If you want to support me financially (completely optional and voluntary, but a lot of people have asked for this):

SubscribeStar: https://www.subscribestar.com/yannickilcher

Patreon: https://www.patreon.com/yannickilcher

Bitcoin (BTC): bc1q49lsw3q325tr58ygf8sudx2dqfguclvngvy2cq

Ethereu…

7 months, 1 week назад @ youtube.com
Traditional X-Mas Stream
Traditional X-Mas Stream Traditional X-Mas Stream

Letsgooo

9 months, 2 weeks назад @ youtube.com
Traditional Holiday Live Stream
Traditional Holiday Live Stream Traditional Holiday Live Stream

https://ykilcher.com/discord Links:

TabNine Code Completion (Referral): http://bit.ly/tabnine-yannick

YouTube: https://www.youtube.com/c/yannickilcher

Twitter: https://twitter.com/ykilcher

Discord: https://discord.gg/4H8xxDF

BitChute: https://www.bitchute.com/channel/yannic-kilcher

Minds: https://www.minds.com/ykilcher

Parler: https://parler.com/profile/YannicKilcher

LinkedIn: https://www.linkedin.com/in/yannic-kilcher-488534136/

BiliBili: https://space.bilibili.com/1824646584 If you want to support me, the best thing to do is to share out the content :) If you want to support me financially (completely optional and voluntary, but a lot of people have asked for this):

SubscribeStar: https:/…

9 months, 2 weeks назад @ youtube.com
TiDAR: Think in Diffusion, Talk in Autoregression (Paper Analysis)
TiDAR: Think in Diffusion, Talk in Autoregression (Paper Analysis) TiDAR: Think in Diffusion, Talk in Autoregression (Paper Analysis)

Paper: https://arxiv.org/abs/2511.08923 Abstract:

Diffusion language models hold the promise of fast parallel generation, while autoregressive (AR) models typically excel in quality due to their causal structure aligning naturally with language modeling. This raises a fundamental question: can we achieve a synergy with high throughput, higher GPU utilization, and AR level quality? Existing methods fail to effectively balance these two aspects, either prioritizing AR using a weaker model for sequential drafting (speculative decoding), leading to lower drafting efficiency, or using some form of left-to-right (AR-like) decoding logic for diffusion, which still suffers from quality degradation …

9 months, 2 weeks назад @ youtube.com
Henry AI Labs Henry AI Labs
последний пост None
3blue1brown 3blue1brown
последний пост 2 weeks, 2 days назад
The Phone Number puzzle
The Phone Number puzzle The Phone Number puzzle

Part of a monthly series of puzzles: https://momath.org/mindbenders/

2 weeks, 2 days назад @ youtube.com
The last IMO problem AI could not solve
The last IMO problem AI could not solve The last IMO problem AI could not solve

Full video: https://youtu.be/Nbwv5wHQoj0

3 weeks, 2 days назад @ youtube.com
The last IMO problem AI could not solve
The last IMO problem AI could not solve The last IMO problem AI could not solve

A beautiful puzzle that eluded AI, and the intuition it requires.

Check out our virtual career fair: https://3b1b.co/talent

See new videos early: https://3b1b.co/support

An equally valuable form of support is to simply share the videos.

Home page: https://www.3blue1brown.com Evan Chen also wrote up nice solution notes for this problem, along with all the others on that year's test.

https://web.evanchen.cc/exams/IMO-2025-notes.pdf The channel Dedekind Cuts has a video about this solution:

https://youtu.be/fgXg9CdCDcs Timestamps:

0:00 - The one that AI missed

4:09 - Problem statement

6:45 - Finding the Optimal Construction

18:51 - A weak lower bound

23:45 - 3b1b Talent

24:41 - Proving the Con…

3 weeks, 2 days назад @ youtube.com
The jumping pegs puzzle
The jumping pegs puzzle The jumping pegs puzzle

Part of a series of monthly puzzles with MoMath.

1 month, 3 weeks назад @ youtube.com
The 64 sugar cubes puzzle
The 64 sugar cubes puzzle The 64 sugar cubes puzzle

See all monthly puzzles: https://momath.org/mindbenders/

2 months, 2 weeks назад @ youtube.com
But what is cross-entropy? | Compression is Intelligence Part 2
But what is cross-entropy? | Compression is Intelligence Part 2 But what is cross-entropy? | Compression is Intelligence Part 2

Where the loss function for training LLMs comes from.

Job opportunities aligned to this audience: https://3b1b.co/talent

Early views and other perks for supporters: https://3b1b.co/support

Home page: https://www.3blue1brown.com Manim animations by Aaron Gostein and Grant Sanderson

NanoGPT animation by Clayton Rabideau

3d black-box model by Paul Dancstep

Music by Vince Rubinetti Timestamps 0:00 - Language trees and zipping

3:02 - Recap optimal codes

5:20 - Defining cross-entropy

8:26 - Intuition and examples

12:59 - Application to language trees

14:55 - Pre-training LLMs

20:38 - What makes this loss function best?

26:13 - Distillation

30:12 - 3b1b Talent

31:35 - KL Divergence ---------------…

2 months, 3 weeks назад @ youtube.com
100 random chords, how many intersections?
100 random chords, how many intersections? 100 random chords, how many intersections?

Part of a series of monthly puzzles done in collaboration with MoMath.

3 months, 3 weeks назад @ youtube.com
Measuring the entropy of English
Measuring the entropy of English Measuring the entropy of English

Full video: https://youtu.be/l6DKRf-fAAM

4 months назад @ youtube.com
What's the perfect encoding? How do you know?
What's the perfect encoding? How do you know? What's the perfect encoding? How do you know?

Full video: https://youtu.be/l6DKRf-fAAM

4 months назад @ youtube.com
Reinventing Entropy | Compression & Intelligence Part 1
Reinventing Entropy | Compression & Intelligence Part 1 Reinventing Entropy | Compression & Intelligence Part 1

What is the fundamental compressibility of language?

Check out our virtual career fair: https://3b1b.co/talent

See new projects before they go live: https://3b1b.co/support Animation credit:

Manim scenes by Aaron Gostein and Grant Sanderson

Shannon’s story, as well as those for various pi creatures, by Mitchell Zemil.

Lunar robot and prediction/compression coin by Paul Dancstep

NanoGPT animations by Clayton Rabideau Shannon’s “A Mathematical Theory of Communication”

https://people.math.harvard.edu/~ctm/home/text/others/shannon/entropy/entropy.pdf Shannon’s “Prediction and Entropy of Printed English”

https://www.princeton.edu/~wbialek/rome/refs/shannon_51.pdf Scientific American article that…

4 months назад @ youtube.com
Tie random ends: How many loops?
Tie random ends: How many loops? Tie random ends: How many loops?

Recent puzzle solutions on Patreon:

https://members.3blue1brown.com/posts/158885046?pr=true

4 months, 3 weeks назад @ youtube.com
Covering 10 points, a surprisingly tricky puzzle.
Covering 10 points, a surprisingly tricky puzzle. Covering 10 points, a surprisingly tricky puzzle.

Made as part of a monthly series of puzzles for the 2026 Year of Math.

5 months, 4 weeks назад @ youtube.com
Escher's most mind-bending piece
Escher's most mind-bending piece Escher's most mind-bending piece

On "The Print Gallery", by M.C. Escher

Full video: https://youtu.be/ldxFjLJ3rVY

6 months, 2 weeks назад @ youtube.com
The subset sum puzzle
The subset sum puzzle The subset sum puzzle

Part of a series of monthly puzzlers. Stay subscribed to see the solution

6 months, 2 weeks назад @ youtube.com
Escher's most mathematically interesting piece
Escher's most mathematically interesting piece Escher's most mathematically interesting piece

Escher's Print Gallery, and the tour of complex analysis it invites.

Check out our virtual career fair: 3b1b.co/talent

Join channel supporters to see videos early: 3b1b.co/support

An equally valuable form of support is to simply share the videos.

Home page: https://www.3blue1brown.com Original paper by de Smit and Lenstra:

https://pub.math.leidenuniv.nl/~smitbde/papers/2003-de_smit-lenstra-escher.pdf Timestamps: 0:00 - The print gallery

13:04 - Conformal maps from complex analysis

21:41 - The complex exponential

25:56 - The complex logarithm

32:32 - 3b1b Talent

33:14 - Constructing the key function

40:16 - The deeper math behind Escher ------------------ These animations are largely made us…

6 months, 3 weeks назад @ youtube.com
Two Minute Papers Two Minute Papers
последний пост 1 час назад
Why DeepSeek Wants AI To Forget
Why DeepSeek Wants AI To Forget Why DeepSeek Wants AI To Forget

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers 📝 The DeepSeek OCR paper is available here:

https://github.com/deepseek-ai/DeepSeek-OCR 🙏 We would like to thank our generous Patreon supporters who make Two Minute Papers possible:

Adam Bridges, B Shang, Carlos Galarza, Christian Ahlin, Eric Tyson, Juan Benet, Lukas Biewald, Michael Tedder, Owen Skarpness, Ryan Stankye, Shawn Becker, Steef, Taras Bobrovytsky, Tazaur Sagenclaw, Tybie Fitzhugh, Ueli Gallizzi

1 час назад @ youtube.com
DeepMind's New AI Just Cracked The Code Of Life
DeepMind's New AI Just Cracked The Code Of Life DeepMind's New AI Just Cracked The Code Of Life

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers Thank you Google DeepMind for the invite. 📝 AlphaGenome Atlas is available here:

https://deepmind.google/blog/alphagenome-atlas-a-predictive-map-of-every-possible-dna-letter-change-in-the-human-genome/

https://blog.google/innovation-and-ai/models-and-research/google-deepmind/alphagenome-atlas/ 🙏 We would like to thank our generous Patreon supporters who make Two Minute Papers possible:

Adam Bridges, B Shang, Carlos Galarza, Christian Ahlin, Eric Tyson, Juan Benet, Lukas Biewald, Michael Tedder, Owen Skarpness, Ryan Stankye, Shawn Becker, Steef, Taras Bobrovytsky, Tazaur Sagenclaw, Tybie Fitzhugh, Ueli Gallizzi

4 days, 5 hours назад @ youtube.com
The Billion Dollar AI Advantage Is Disappearing
The Billion Dollar AI Advantage Is Disappearing The Billion Dollar AI Advantage Is Disappearing

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers 📝 Sonnet 5.5: https://www.anthropic.com/claude-sonnet-5-5 🙏 We would like to thank our generous Patreon supporters who make Two Minute Papers possible:

Adam Bridges, B Shang, Carlos Galarza, Christian Ahlin, Eric Tyson, Juan Benet, Lukas Biewald, Michael Tedder, Owen Skarpness, Ryan Stankye, Shawn Becker, Steef, Taras Bobrovytsky, Tazaur Sagenclaw, Tybie Fitzhugh, Ueli Gallizzi

6 days, 8 hours назад @ youtube.com
Claude Opus 5.5 AI: A Massive Leap Forward
Claude Opus 5.5 AI: A Massive Leap Forward Claude Opus 5.5 AI: A Massive Leap Forward

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers Claude Opus 5.5: https://www.anthropic.com/claude-opus-5-5 Walking creatures video and paper:

https://www.youtube.com/watch?v=kQ2bqz3HPJE

https://www.goatstream.com/research/papers/SA2013/ Honey coiling video and paper:

https://www.youtube.com/watch?v=ZEjUqZU1hNQ

https://cs.uwaterloo.ca/~c2batty/papers/Larionov2017/Larionov2017.pdf

https://dl.acm.org/doi/10.1145/3072959.3073628

https://uwspace.uwaterloo.ca/items/ecb9fe94-1ef5-4ed0-a67e-b3d3c5a7534e

paper name: Variational Stokes: A Unified Pressure-Viscosity Solver for Accurate Viscous Liquids Sources:

https://x.com/ArtificialAnlys/status/2102438210798514391/…

2 weeks, 3 days назад @ youtube.com
Jev Just Made AI 200x Faster…But There’s A Catch
Jev Just Made AI 200x Faster…But There’s A Catch Jev Just Made AI 200x Faster…But There’s A Catch

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers 📝 Jev:

https://typesafe.ai/blog/introducing-system-one-models-and-jev Full song: https://www.youtube.com/watch?v=4RtUJkjrKMI Previous papers, implementations, models:

https://huggingface.co/convaiinnovations/laya

https://arxiv.org/abs/2503.23303

https://huggingface.co/DeepMostInnovations/sales-conversion-model-reinf-learning

https://huggingface.co/datasets/DeepMostInnovations/saas-sales-conversations

https://arxiv.org/abs/2510.01237

https://huggingface.co/blog/setfit

https://proceedings.iclr.cc/paper_files/paper/2025/hash/5503a7c69d48a2f86fc00b3dc09de686-Abstract-Conference.html Sources:

https://x.com/alexisg…

2 weeks, 5 days назад @ youtube.com
DeepSeek Just Made AI Memory 4x Smaller!
DeepSeek Just Made AI Memory 4x Smaller! DeepSeek Just Made AI Memory 4x Smaller!

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers 📝 The DeepSeek V4.1 Flash paper is available here:

https://www.deepseek.com/en/news/deepseek-v4-1-flash/ Sources:

https://x.com/flowith/status/2099446892174406055/video/1

https://x.com/loktar00/status/2097761803291726137

https://x.com/loktar00/status/2099171901746688079

https://x.com/loktar00/status/2097557594239897837

https://x.com/loktar00/status/2097342670620291430

https://x.com/RealFedeURU/status/2097804481068941679

https://x.com/ItsmeAjayKV/status/2099875889454739801

https://x.com/ItsmeAjayKV/status/2100434059675709683/video/1

https://x.com/DanielPPFW/status/2100016621251338732/video/1 🙏 We would like to…

3 weeks, 2 days назад @ youtube.com
Claude Is Now Leaving Invisible Fingerprints In Its Text
Claude Is Now Leaving Invisible Fingerprints In Its Text Claude Is Now Leaving Invisible Fingerprints In Its Text

❤️ Check out Weights & Biases and sign up for a free demo here: https://wandb.me/papers 📝 The papers and sources are available here:

https://proceedings.mlr.press/v202/kirchenbauer23a.html

https://www.nature.com/articles/s41586-024-08025-4

https://www.anthropic.com/news/claude-text-watermark 🙏 We would like to thank our generous Patreon supporters who make Two Minute Papers possible:

Adam Bridges, B Shang, Carlos Galarza, Christian Ahlin, Eric Tyson, Juan Benet, Lukas Biewald, Michael Tedder, Owen Skarpness, Ryan Stankye, Shawn Becker, Steef, Taras Bobrovytsky, Tazaur Sagenclaw, Tybie Fitzhugh, Ueli Gallizzi

3 weeks, 5 days назад @ youtube.com
Humans + AI Cracked An Impossible Math Problem
Humans + AI Cracked An Impossible Math Problem Humans + AI Cracked An Impossible Math Problem

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers 📝 The Navier-Stokes solution paper is available here:

https://openai.com/index/navier-stokes-solution/ My fluid simulations and papers:

https://users.cg.tuwien.ac.at/zsolnai/gfx/fluid_control_msc_thesis/

https://users.cg.tuwien.ac.at/zsolnai/gfx/real_time_fluid_control_eg/

The flow from simulation to reality: https://www.nature.com/articles/s41567-022-01788-5

All papers: https://users.cg.tuwien.ac.at/zsolnai/ Sources:

https://www.youtube.com/watch?v=EURkO98VnKc

https://www.youtube.com/watch?v=luOWq1Gdv8c 🙏 We would like to thank our generous Patreon supporters who make Two Minute Papers possible:

Adam Bridges…

1 month назад @ youtube.com
GPT-6 Astra - A Massive Leap Into The Future
GPT-6 Astra - A Massive Leap Into The Future GPT-6 Astra - A Massive Leap Into The Future

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers Links / sources:

Honey sim: search for "Variational Stokes: A Unified Pressure-Viscosity Solver for Accurate Viscous Liquids" here: https://cs.uwaterloo.ca/~c2batty/

https://x.com/mindblown_ai/status/2095661874037813298?s=20

https://x.com/aollivier82/status/2096226819401801896?s=46

https://x.com/sahilexec/status/2095688272269984016?s=46

https://x.com/petergostev/status/2095596176804307342?s=20

https://x.com/mattshumer_/status/2095609734845927525?s=20

https://x.com/mattshumer_/status/2095596175705399482?s=46

https://x.com/davis7/status/2095742249275699415?s=46

https://x.com/dimillian/status/2095596700815516004…

1 month назад @ youtube.com
Claude Fable AI Is Much Stranger Than The Headlines Suggest
Claude Fable AI Is Much Stranger Than The Headlines Suggest Claude Fable AI Is Much Stranger Than The Headlines Suggest

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers 📝 The Claude Fable 5.1 paper is available here:

https://www.anthropic.com/claude-fable-and-mythos-5-1

https://www-cdn.anthropic.com/0339e6a7c5c7b87f5c07798616dc32c215d14235/Claude%20Fable%205.1%20%26%20Claude%20Mythos%205.1%20System%20Card.pdf Sources:

https://x.com/alexalbert__/status/2094860187743986169?s=46

https://x.com/holytrinity/status/2094866061212459130?s=46

https://x.com/holytrinity/status/2094927984217985474?s=46

https://x.com/omedvibecodes/status/2094887840848965845?s=46

https://x.com/loktar00/status/2094951511742632168?s=46

https://x.com/maxt3chno/status/2094798704385380762?s=46

https://x.com/fab…

1 month, 1 week назад @ youtube.com
Powerful AI Is Becoming Almost Free
Powerful AI Is Becoming Almost Free Powerful AI Is Becoming Almost Free

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers 📝 GLM 5.3 Flash:

https://z.ai/blog/glm-5.3-flash Sources:

https://x.com/louszbd/status/2092694163104113016

https://x.com/semianalysis_/status/2092623833630998556

https://x.com/skalskip92/status/2092748209802154201

https://x.com/louszbd/status/2093047548550525165

https://x.com/atomic_chat_hq/status/2093433913238552712

https://x.com/holytrinity/status/2094093933584257334

https://x.com/KinasRemek/status/2090081611832295581/video/1

https://x.com/AiXsatoshi/status/2093679264013181119/video/1

https://x.com/AiXsatoshi/status/2093353322921263389/video/1

https://x.com/stevibe/status/2092655031040565252 🙏 We would like…

1 month, 1 week назад @ youtube.com
This Free AI Just Caught The Billion Dollar Giants
This Free AI Just Caught The Billion Dollar Giants This Free AI Just Caught The Billion Dollar Giants

❤️ Check out Weights & Biases and sign up for a free demo here: https://wandb.me/papers 📝 The paper and Qwen3.8-Flash-Next are available here:

https://github.com/QwenLM/Qwen3.8-Flash-Next/blob/main/tech_report.pdf

https://qwen.ai/blog?id=qwen3.8-flash-next 🙏 We would like to thank our generous Patreon supporters who make Two Minute Papers possible:

Adam Bridges, B Shang, Carlos Galarza, Christian Ahlin, Eric Tyson, Juan Benet, Lukas Biewald, Michael Tedder, Owen Skarpness, Ryan Stankye, Shawn Becker, Steef, Taras Bobrovytsky, Tazaur Sagenclaw, Tybie Fitzhugh, Ueli Gallizzi

1 month, 2 weeks назад @ youtube.com
DeepSeek’s AI Just Learned To Upgrade Itself
DeepSeek’s AI Just Learned To Upgrade Itself DeepSeek’s AI Just Learned To Upgrade Itself

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers 📝 DeepSeek Harness + paper are available here:

https://deepseek.com/harness/en/

https://github.com/cordiverse/paper 🙏 We would like to thank our generous Patreon supporters who make Two Minute Papers possible:

Adam Bridges, B Shang, Carlos Galarza, Christian Ahlin, Eric Tyson, Juan Benet, Lukas Biewald, Michael Tedder, Owen Skarpness, Ryan Stankye, Shawn Becker, Steef, Taras Bobrovytsky, Tazaur Sagenclaw, Tybie Fitzhugh, Ueli Gallizzi

1 month, 2 weeks назад @ youtube.com
This Small AI Will Change Everything
This Small AI Will Change Everything This Small AI Will Change Everything

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers 📝 The Qwen3.8-27b is available here:

https://huggingface.co/Qwen/Qwen3.8-27B Sources:

https://www.reddit.com/r/unsloth/comments/1vogva0/share_your_results_from_qwen3827b/

https://www.reddit.com/r/LocalLLaMA/comments/1voer8u/qwen_38_27b_aquarium_burst_sample_test/

https://x.com/KyleHessling1/status/2088327667733180637

https://www.reddit.com/r/LocalLLaMA/comments/1vqme4y/qwen3827b_q8_0_on_strix_halo_is_seriously/

https://forums.developer.nvidia.com/t/qwen3-8-27b-nvfp4-on-a-single-dgx-spark-up-to-1m-context-vllm-mtp-measurements/380244 🙏 We would like to thank our generous Patreon supporters who make Two Minute …

1 month, 2 weeks назад @ youtube.com
DeepSeek Just Made Closed AI Look Ridiculous
DeepSeek Just Made Closed AI Look Ridiculous DeepSeek Just Made Closed AI Look Ridiculous

❤️ Check out Lambda here and sign up for their GPU Cloud: https://lambda.ai/papers DeepSeek V4 Pro 0813:

https://huggingface.co/deepseek-ai/DeepSeek-V4-Pro-0813 DSpark full episode: https://www.youtube.com/watch?v=1yBU41auQhw Sources:

https://x.com/cline/status/2087602193205694891

https://x.com/TypingMindApp/status/2088214938754167263

https://x.com/stevibe/status/2047546592530747561

https://x.com/voidfreud/status/2087701887327887543

https://x.com/exploraX_/status/2079197387860435360

https://x.com/AiHubMix/status/2087869896483057758

https://x.com/BruceBlue/status/2087833177155117304 🙏 We would like to thank our generous Patreon supporters who make Two Minute Papers possible:

Adam Bridges, B …

1 month, 3 weeks назад @ youtube.com
DataFest Video DataFest Video
последний пост None
Семинары JetBrains Research Семинары JetBrains Research
последний пост None
Яндекс. Компьютерные науки Яндекс. Компьютерные науки
последний пост 4 days, 10 hours назад
Как мы научили GigaChat Audio ориентироваться во времени temporal grounding для длинных аудиозаписей
Как мы научили GigaChat Audio ориентироваться во времени temporal grounding для длинных аудиозаписей Как мы научили GigaChat Audio ориентироваться во времени temporal grounding для длинных аудиозаписей

В работе с аудио всё чаще важно не только распознавать речь, но и понимать длинную запись целиком: отвечать на вопросы, строить суммаризацию и находить нужный фрагмент. Для этого Audio LLM должна понимать не только, что произошло, но и когда именно. В докладе разберём temporal grounding для длинного аудио и покажем, что даже сильные модели могут давать верный смысловой ответ, но ошибаться в тайм-кодах на минуты.

Расскажем, как построили полный пайплайн time-aware Audio LLM и как контролировали качество данных: собрали и опубликовали синтетический датасет объёмом 13 тыс. часов и 1 млн семплов, адаптировали архитектуру модели и добавили inter-timings — временные якоря между аудиотокенами. На …

4 days, 10 hours назад @ youtube.com
Дальше, точнее, быстрее: query-based-детекция для автономного транспорта / Иван Лунев
Дальше, точнее, быстрее: query-based-детекция для автономного транспорта / Иван Лунев Дальше, точнее, быстрее: query-based-детекция для автономного транспорта / Иван Лунев

Система восприятия автономного автомобиля должна одновременно видеть далеко, детектировать точно и укладываться в жёсткий бюджет времени на edge-устройстве. Наша CNN-based-архитектура на базе BEVFusion даёт обзор на 250 м вперёд и назад и на 100 м по бокам, но масштабировать дальность не получается: любое расширение зоны видимости упирается либо в качество детекции, либо в скорость инференса.

Расскажу, как мы перешли на query-based-модель MV2DFusion и сняли это ограничение: боковой обзор уже вырос с 100 до 200 м, а дальность вперёд и назад архитектура позволяет увеличить с 250 до 400 м: это наши следующие планы. Разберём, почему выбрали именно эту модель и как сравнивали с BEVFusion по даль…

4 days, 10 hours назад @ youtube.com
Yet Another Closed-loop Teleoperation / Андрей Маношин
Yet Another Closed-loop Teleoperation / Андрей Маношин Yet Another Closed-loop Teleoperation / Андрей Маношин

Расскажу, как мы обучили единую end-to-end-модель управления всем телом гуманоида. Она самостоятельно координирует движения и поддерживает равновесие робота — от ходьбы, приседаний и наклонов до поднятия предметов и взаимодействия с тяжёлыми объектами, охватывая широкий спектр необходимых нам сценариев. Больше материалов про ML по ссылке: https://t.me/+owyCvdge8WIyNTUy

4 days, 10 hours назад @ youtube.com
LLM-матрёшки: от исследовательского метода к рабочей технологии / Артём Федоров
LLM-матрёшки: от исследовательского метода к рабочей технологии / Артём Федоров LLM-матрёшки: от исследовательского метода к рабочей технологии / Артём Федоров

Метод построения LLM-матрёшек позволяет за одно небольшое дообучение получить из одной большой модели семейство меньших. Расскажу, как мы доработали исходный подход: адаптировали его к новым архитектурам, перешли от числа параметров к прямой оптимизации скорости работы модели и научились точно попадать в произвольные бюджеты. Отдельно разберём кейсы применения полученных моделей — от ускорения исследовательских экспериментов до использования в сервисах. Больше материалов про ML по ссылке: https://t.me/+owyCvdge8WIyNTUy

4 days, 10 hours назад @ youtube.com
Evals для LLM-систем: от вайбчека к метрикам для агентов и LLM-продуктов / Алексей Степин
Evals для LLM-систем: от вайбчека к метрикам для агентов и LLM-продуктов / Алексей Степин Evals для LLM-систем: от вайбчека к метрикам для агентов и LLM-продуктов / Алексей Степин

Оценить качество новой LLM-фичи сложно — особенно до того, как она попадёт к пользователям, а часто и после, если в команде нет развитой культуры A/B-тестов. В итоге правка улучшает один кейс и ломает три, а вопрос «выкатываем ли новый промпт и переходим ли на другую модель» решается на глаз. В своём докладе я разберу, как выстроить систему evals для LLM-продуктов и сочетать простые детерминированные проверки, LLM-as-a-judge, собственные бенчмарки и A/B-тесты. Отдельно поговорим про специфику оценки агентов — там важен не только финальный результат, но и путь к нему — почти как у самурая.

Дальше перейду к конкретике: что болело у нас при попытках улучшить LLM-системы и как мы это решали. Об…

4 days, 10 hours назад @ youtube.com
NEEDLE: открытый бенчмарк движков для веб-поиска / Илья Гусев
NEEDLE: открытый бенчмарк движков для веб-поиска / Илья Гусев NEEDLE: открытый бенчмарк движков для веб-поиска / Илья Гусев

Все существующие бенчмарки для поиска измеряют либо качество языковых моделей, либо качество поисковых моделей и алгоритмов. А вот качество самого поискового движка (финального API для поиска) никто нормально не измеряет.

Кроме того, существующие бенчмарки в основном статичны, то есть набор поисковых запросов в них фиксирован. Это очень плохо, потому что позволяет один раз найти, разметить и закешировать правильные документы, а также подогнать под них ранжирование. Поэтому мы предлагаем онлайн-бенчмарк NEEDLE, в котором используются свежие запросы на основе новостей, статей, финансовых документов, судебных дел и логов агентов.

В докладе я подробно расскажу об этом и других бенчмарках, а так…

4 days, 10 hours назад @ youtube.com
От градиентного бустинга к Deep Ranker: опыт перехода в ранжировании без слёз / Андрей Белобородов
От градиентного бустинга к Deep Ranker: опыт перехода в ранжировании без слёз / Андрей Белобородов От градиентного бустинга к Deep Ranker: опыт перехода в ранжировании без слёз / Андрей Белобородов

Поговорим об архитектуре Deep Ranker: о том, почему она эффективна и как переносит сильные стороны градиентных бустингов в нейросетевой подход. Разберём практические сложности миграции на модели другой природы — смещение в обучении и офлайн-тестировании, а также способы сделать такой переход безопасным для бизнес-метрик. Больше материалов про ML по ссылке: https://t.me/+owyCvdge8WIyNTUy

4 days, 10 hours назад @ youtube.com
Ouroboros: что внутри агента, обошедшего Codex, Claude Code и Cursor / Антон Разжигаев
Ouroboros: что внутри агента, обошедшего Codex, Claude Code и Cursor / Антон Разжигаев Ouroboros: что внутри агента, обошедшего Codex, Claude Code и Cursor / Антон Разжигаев

Может ли агент улучшать сам себя и не деградировать?

Ouroboros — действующий эксперимент: кодинг-агент с конституцией, памятью и правом коммитить в собственный репозиторий. На открытых бенчмарках он впереди Codex, Claude Code и Cursor. В докладе — об архитектуре, петле самоулучшения и граблях, на которые мы наступили: от агентов, подсматривающих ответы, до правок, чуть не убивших систему. Больше материалов про ML по ссылке: https://t.me/+owyCvdge8WIyNTUy

4 days, 10 hours назад @ youtube.com
Как мы реализовали конструктор видеоаналитик / Анастасия Белозерова
Как мы реализовали конструктор видеоаналитик / Анастасия Белозерова Как мы реализовали конструктор видеоаналитик / Анастасия Белозерова

Luna Line — платформа компьютерного зрения, в которой пользователь может пройти весь путь создания CV-решения: от разметки данных под конкретную задачу до запуска видеоаналитики на RTSP-потоке. Обучение модели запускается одной кнопкой и работает с данными из разных предметных областей, начиная от 50 изображений. В докладе я расскажу, как мы реализовали в среднем оптимальное обучение моделей классификации, детекции и сегментации, адаптирующееся под размер обучающей выборки. Сравню качество полученных моделей с решениями основных конкурентов и VLM. Также расскажу про конструктор видеоаналитик и разберу реальные кейсы, в которых уже применяются собранные с его помощью решения. Больше материал…

4 days, 10 hours назад @ youtube.com
Commodity LLM: как мы строим инфраструктуру и процессы для массового инференса LLM
Commodity LLM: как мы строим инфраструктуру и процессы для массового инференса LLM Commodity LLM: как мы строим инфраструктуру и процессы для массового инференса LLM

Использование облачных LLM по API часто недоступно из-за работы с чувствительными данными, поэтому модели приходится разворачивать внутри корпоративного контура. Собственный массовый инференс LLM не только страхует риски регуляторной политики, но и позволяет управлять SLA и приобретать необходимый экспертный опыт, чтобы эксплуатировать свои собственные дообученные и опенсорс-модели, недоступные у внешних вендоров. Однако у такого подхода есть жёсткое ограничение: затраты на собственный массовый LLM-инференс не должны превышать цену токенов у внешних провайдеров, иначе инхаус-решение становится экономически нецелесообразным. На практике добиться этого сложно. Без постоянной работы над внутре…

4 days, 10 hours назад @ youtube.com
Развитие рекомендательной системы в РСЯ: от нейроранжирования до улучшения аукциона
Развитие рекомендательной системы в РСЯ: от нейроранжирования до улучшения аукциона Развитие рекомендательной системы в РСЯ: от нейроранжирования до улучшения аукциона

Поговорим о том, что такое РСЯ и как в ней взаимодействуют пользователь, площадка и рекламодатель.

Разберём, как ранжируются объявления, и посмотрим на рекомендательную систему в рекламе. Отдельно обсудим раннее связывание и нейроранжирование, а также роль DeepRanker как нейросетевой модели ранжирования. Затем перейдём к рекламному аукциону и разберёмся, зачем собирать баннеры в блоки. Также расскажем о внедрении HIMERA — ML-кандидат-генератора блоков — и об отказе от эвристик. А в завершение поговорим о развитии HIMERA, генеративных методах сбора блоков и о том, в каком направлении мы планируем развивать эти подходы, следуя тенденциям индустрии. Больше материалов про ML по ссылке: https://…

4 days, 10 hours назад @ youtube.com
Диффузионный драфтинг в спекулятивном декодинге: DFlash и DSpark — от модели до вывода в продакшн
Диффузионный драфтинг в спекулятивном декодинге: DFlash и DSpark — от модели до вывода в продакшн Диффузионный драфтинг в спекулятивном декодинге: DFlash и DSpark — от модели до вывода в продакшн

Диффузионные драфтеры — новое направление в спекулятивном декодировании, где блок кандидатов генерируется преимущественно параллельно, а не токен за токеном. Кратко рассмотрю развитие подходов к многотокенному предсказанию и разберу, как идеи параллельного драфтинга реализованы в DFlash и получили дальнейшее развитие в DSpark. Основное внимание уделю архитектурным инновациям в этих методах: non-causal drafting в DFlash, восстановлению зависимостей между токенами с помощью Markov head в DSpark, а также использованию confidence head для динамического выбора длины верификации. Отдельно расскажу о практической интеграции таких моделей в inference-системы. На примере реализации в vLLM и vLLM-Asc…

4 days, 10 hours назад @ youtube.com
RL meets Browser: как мы обучили VLM-агента работать в вебе за пользователя / Артемий Голиков
RL meets Browser: как мы обучили VLM-агента работать в вебе за пользователя / Артемий Голиков RL meets Browser: как мы обучили VLM-агента работать в вебе за пользователя / Артемий Голиков

Computer-Use-агенты — модели, которые сами выполняют действия в компьютерной среде вместо пользователя, — постепенно перестают быть демо и становятся рабочей технологией. Но путь от «у нас есть VLM» до «агент выполняет задачи пользователя в проде» гораздо длиннее, чем кажется: живой браузер не детерминирован, эпизоды длинные, а рецептов multi-turn RL для мультимодальных агентов почти нет в открытом доступе. Расскажу, как мы построили и обучили VLM-агента, который выполняет задачи в реальном браузере: начинали с booking-сценария, сейчас масштабируемся до широкого спектра пользовательских задач. Разберём архитектуру пайплайна и объясним, почему одной VLM недостаточно. Покажу, как мы завели RL…

4 days, 10 hours назад @ youtube.com
Пока вы говорите: как устроен стриминговый перевод речи / Вилиана Девбунова
Пока вы говорите: как устроен стриминговый перевод речи / Вилиана Девбунова Пока вы говорите: как устроен стриминговый перевод речи / Вилиана Девбунова

Потоковый перевод вы слышите в реальном времени, не дожидаясь завершения всей речи говорящего. Расскажу, как мы сделали такую систему для перевода с английского на русский: как учили потоковый ASR и переводную LLM, какие архитектуры сравнивали, почему в итоге остановились на выбранной и почему выдача по предложениям. Отдельно разберём главный компромисс любой стриминговой системы — задержку против качества. Откуда она берётся на каждом этапе пайплайна, как мы её измеряли и что помогло её сократить, не потеряв в метриках. Покажу, как мы сегментировали поток на предложения и что делали с нестабильностью гипотез на границах. И, конечно, поделюсь граблями, которые собрали по дороге. Больше мате…

4 days, 10 hours назад @ youtube.com
Планировщик операций для LLM: ускорение обучения как алгоритмическая задача / Александр Пацация
Планировщик операций для LLM: ускорение обучения как алгоритмическая задача / Александр Пацация Планировщик операций для LLM: ускорение обучения как алгоритмическая задача / Александр Пацация

Современные большие языковые модели обучаются на больших кластерах видеокарт. Эффективная организация параллельных вычислений и коммуникаций позволяет существенно ускорить процесс обучения, тем самым сэкономив огромное количество денег компании. В своём докладе я расскажу, как устроено современное распределенное обучение LLM, с какими проблемами мы сталкиваемся и какие подходы помогают с ними справиться. Поговорим о методах паралеллизации вычислений модели на многие GPU, в особенности — пайплайн паралеллизме, и о том, как мы придумали обобщение этого подхода, рассмотрев его как задачу планирования с ограничениями. Наш подход позволил существенно ускорить обучение больших языковых моделей. Я…

4 days, 10 hours назад @ youtube.com
ML Trainings ML Trainings
последний пост 2 часа назад
Капитанский мостик 11.10.2026: Навье-Стокс не доказан | У Huawei 50% рынка | ГАИ для роботов
Капитанский мостик 11.10.2026: Навье-Стокс не доказан | У Huawei 50% рынка | ГАИ для роботов Капитанский мостик 11.10.2026: Навье-Стокс не доказан | У Huawei 50% рынка | ГАИ для роботов

0:00:00 Начало

0:00:32 Навье-Стокс не доказан

0:06:32 OpenAI выложила трейсы

0:14:46 Математики-человеки

0:17:13 ГАИ для роботов

0:25:17 Claude запретил жестокость

0:30:30 Mistral выпустил 1Т модель

0:34:35 Европейцы отказались от Mistral

0:36:57 Сбер и второй том "Мертвых душ"

0:47:22 Tencent арендует от Oracle

0:49:59 Роботы захватывают мир

0:54:36 Wikipedia и агенты

0:57:56 Компании тратят на нейросети

1:02:31 ИИ-музыка и боты

1:10:46 У Huawei 50% рынка

1:15:47 Волшебная Албания ИИ-саммари: Валентин Малых и Дмитрий Колодезев разбирают главные ИИ-события недели. Главная тема — математика, созданная ИИ: OpenAI опубликовала рукописи и цепочки рассуждений своей модели, математическое сообщес…

2 часа назад @ youtube.com
Григорий Алексеенко | Суперразрешение в эпоху diffusion-моделей: как и зачем?
Григорий Алексеенко | Суперразрешение в эпоху diffusion-моделей: как и зачем? Григорий Алексеенко | Суперразрешение в эпоху diffusion-моделей: как и зачем?

Спикер: Григорий Алексеенко, руководитель направления, Сбер Data Fest 2026: https://ods.ai/events/datafest2026

Презентацию к докладу Вы можете скачать в треке секции GenCV https://ods.ai/tracks/df26-gencv

______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

2 days, 2 hours назад @ youtube.com
Полина Попова | Как мы использовали простые ML-алгоритмы для решения задачи
Полина Попова | Как мы использовали простые ML-алгоритмы для решения задачи Полина Попова | Как мы использовали простые ML-алгоритмы для решения задачи

Спикер: Полина Попова, старший эксперт, Сколково, преподаватель, НИУ ВШЭ Data Fest 2026: https://ods.ai/events/datafest2026

Презентацию к докладу Вы можете скачать в треке секции ML на пальцах https://ods.ai/tracks/df26-eli5

______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

2 days, 2 hours назад @ youtube.com
Артур Богомазов | На стыке LLM и компетентностного подхода: архитектура, вызовы и решения
Артур Богомазов | На стыке LLM и компетентностного подхода: архитектура, вызовы и решения Артур Богомазов | На стыке LLM и компетентностного подхода: архитектура, вызовы и решения

Спикер: Артур Богомазов, АНО "Школа 21" Data Fest 2026: https://ods.ai/events/datafest2026 Презентацию к докладу Вы можете скачать в треке секции ML & Education ______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

2 days, 11 hours назад @ youtube.com
Рустам Назипов | RAG на тысячах PDF: каскадный поиск и другие production-хаки
Рустам Назипов  | RAG на тысячах PDF: каскадный поиск и другие production-хаки Рустам Назипов | RAG на тысячах PDF: каскадный поиск и другие production-хаки

Спикер: Рустам Назипов Data Fest 2026: https://ods.ai/events/datafest2026 Презентацию к докладу Вы можете скачать в треке секции Advanced LLMs ______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

2 days, 11 hours назад @ youtube.com
Дарья Воронкина | Как мы строим ML-пайплайны для патоморфологии: данные, разметка, агенты
Дарья Воронкина | Как мы строим ML-пайплайны для патоморфологии: данные, разметка, агенты Дарья Воронкина | Как мы строим ML-пайплайны для патоморфологии: данные, разметка, агенты

Спикер: Дарья Воронкина, OneCell.ai Data Fest 2026: https://ods.ai/events/datafest2026 Презентацию к докладу Вы можете скачать в треке секции Ужасы мед данных https://ods.ai/tracks/df26-med-data

______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

3 days, 2 hours назад @ youtube.com
Владимир Галустов | AI-разметчик и контроль качества авторазметки
Владимир Галустов | AI-разметчик и контроль качества авторазметки Владимир Галустов | AI-разметчик и контроль качества авторазметки

Спикер: Владимир Галустов, Т-банк Data Fest 2026: https://ods.ai/events/datafest2026 Презентацию к докладу Вы можете скачать в треке секции Data Collection & Labelling

______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

3 days, 2 hours назад @ youtube.com
Данияр Курманходжаев | Мадам, снимите шляпу. Выбор оптимального фото для удалённой верификации
Данияр Курманходжаев | Мадам, снимите шляпу. Выбор оптимального фото для удалённой верификации Данияр Курманходжаев | Мадам, снимите шляпу. Выбор оптимального фото для удалённой верификации

Спикер: Данияр Курманходжаев, Verigram Data Fest 2026: https://ods.ai/events/datafest2026 ______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

3 days, 11 hours назад @ youtube.com
Маргарита Бенедичук | Когда метрики врут: противодействие доменному сдвигу в МРТ
Маргарита Бенедичук | Когда метрики врут: противодействие доменному сдвигу в МРТ Маргарита Бенедичук | Когда метрики врут: противодействие доменному сдвигу в МРТ

Спикер: Маргарита Бенедичук, Лаборатория анализа потоковых данных и машинного обучения НГУ Data Fest 2026: https://ods.ai/events/datafest2026 Презентацию к докладу Вы можете скачать в треке секции Ужасы мед данных https://ods.ai/tracks/df26-med-data

______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

3 days, 11 hours назад @ youtube.com
Юрий Барамыков | ggmlR:Vulkan GPU-бэкенд для R
Юрий Барамыков | ggmlR:Vulkan GPU-бэкенд для R Юрий Барамыков | ggmlR:Vulkan GPU-бэкенд для R

Спикер: Юрий Барамыков, старший руководитель проекта, Иннотех Data Fest 2026: https://ods.ai/events/datafest2026 Презентацию к докладу Вы можете скачать в треке секции Open Source

______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

4 days, 1 hour назад @ youtube.com
Екатерина Лемдясова | Диагностика ранжирующих моделей на основе больших языковых моделей в рекоменд
Екатерина Лемдясова | Диагностика ранжирующих моделей на основе больших языковых моделей в рекоменд Екатерина Лемдясова | Диагностика ранжирующих моделей на основе больших языковых моделей в рекоменд

Спикер: Екатерина Лемдясова, Росбиотех Data Fest 2026: https://ods.ai/events/datafest2026 ______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

4 days, 1 hour назад @ youtube.com
Евгений Докичев и Семён Веретенников | Как угодить заказчикам и почему порой этого недостаточно?
Евгений Докичев и Семён Веретенников | Как угодить заказчикам и почему порой этого недостаточно? Евгений Докичев и Семён Веретенников | Как угодить заказчикам и почему порой этого недостаточно?

Спикеры: Евгений Докичев и Семён Веретенников, Т-банк Data Fest 2026: https://ods.ai/events/datafest2026 Презентацию к докладу Вы можете скачать в треке секции Data Collection & Labelling

______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

4 days, 11 hours назад @ youtube.com
Michael Diskin | When Models Should Stay Silent
Michael Diskin | When Models Should Stay Silent Michael Diskin | When Models Should Stay Silent

Спикер: Michael Diskin, HSE University

Data Fest 2026: https://ods.ai/events/datafest2026 ______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

4 days, 11 hours назад @ youtube.com
Сергей Пихтовников | Образование как мультиагентная система: от склада контента к среде взаимодейств
Сергей Пихтовников | Образование как мультиагентная система: от склада контента к среде взаимодейств Сергей Пихтовников | Образование как мультиагентная система: от склада контента к среде взаимодейств

Спикер: Сергей Пихтовников, ФГБОУ ФО "Уфимский университет науки и технологий" Data Fest 2026: https://ods.ai/events/datafest2026 Презентацию к докладу Вы можете скачать в треке секции ML & Education ______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

5 days, 3 hours назад @ youtube.com
Dmitrii Iunovidov | Making Industrial CV Fly on Edge CPUs: A Neuro-Symbolic Benchmark for Dense
Dmitrii Iunovidov | Making Industrial CV Fly on Edge CPUs: A Neuro-Symbolic Benchmark for Dense Dmitrii Iunovidov | Making Industrial CV Fly on Edge CPUs: A Neuro-Symbolic Benchmark for Dense

Спикер: Dmitrii Iunovidov, LogicYield, Founding ML Engineer Data Fest 2026: https://ods.ai/events/datafest2026 ______

Наши соц.сети:

Telegram: https://t.me/datafest

Вконтакте: https://vk.com/datafest

Канал с вакансиями в telegram: https://t.me/odsjobs

Канал с апдейтами по курсам: https://t.me/odscourses

Как попасть в чат сообщества ODS Mattermost: https://ods.ai/tracks/mattermost

5 days, 3 hours назад @ youtube.com
🎧 Podcasts
Lex Fridman AI Podcast Lex Fridman AI Podcast
последний пост 3 weeks, 3 days назад
#502 – Psychiatry, Insane Asylums, Mental Illness, ECT, Lobotomies, Freud & Jung
#502 – Psychiatry, Insane Asylums, Mental Illness, ECT, Lobotomies, Freud & Jung #502 – Psychiatry, Insane Asylums, Mental Illness, ECT, Lobotomies, Freud & Jung

Andrew Scull is a historian of psychiatry.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep502-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

Go to https://wisprflow.ai/lexFin: AI agent for customer service.

Go to https://fin.ai/lexLMNT: Zero-sugar electrolyte drink mix.

Go to https://shopify.com/lexBetterHelp: Online therapy and counseling.

3 weeks, 3 days назад @ lexfridman.com
#501 – DHH: Future of Programming, AI, Agentic Engineering, Vibe Coding & Linux
#501 – DHH: Future of Programming, AI, Agentic Engineering, Vibe Coding & Linux #501 – DHH: Future of Programming, AI, Agentic Engineering, Vibe Coding & Linux

DHH is the creator of Ruby on Rails, Omarchy Linux, CTO of 37signals, and a racecar driver.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep501-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

Go to https://wisprflow.ai/lexBlitzy: AI agent for large enterprise codebases.

Go to https://plaud.ai/lexHiggsfield AI: AI-based video generation, filmmaking, and creative studio.

Go to https://perplexity.ai/OUTLINE:(00:00) – Introduction(01:14) – Sponsors, Comments, and Reflections(08:56) – Programming with AI agents(24:14) – How software will change(33:30) – AI impact on open source(43:21) – Building Omarchy Linux d…

1 month, 2 weeks назад @ lexfridman.com
#500 – Khabib Nurmagomedov: Dagestan, MMA, UFC, Islam, Conor, Fedor & Football
#500 – Khabib Nurmagomedov: Dagestan, MMA, UFC, Islam, Conor, Fedor & Football #500 – Khabib Nurmagomedov: Dagestan, MMA, UFC, Islam, Conor, Fedor & Football

Khabib Nurmagomedov is one of the greatest fighters of all time, who retired from the UFC undefeated with a perfect 29-0 record.

We did this conversation entirely in Russian.

Both language audio tracks (and subtitles) are available on YouTube.

We worked hard to make it enjoyable to listen to, by carefully dubbing the translation using voice-cloning, as we’ve done for previous foreign-language podcasts.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep500-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

2 months назад @ lexfridman.com
#499 – Gary Gallagher: American Civil War, Slavery, Lincoln, Grant & Lee
#499 – Gary Gallagher: American Civil War, Slavery, Lincoln, Grant & Lee #499 – Gary Gallagher: American Civil War, Slavery, Lincoln, Grant & Lee

Gary Gallagher is a historian of the American Civil War.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep499-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

Go to https://plaud.ai/lexOUTLINE:(00:00) – Introduction(00:07) – Sponsors, Comments, and Reflections(08:36) – What caused the Civil War?

(18:33) – Slavery(46:07) – Lincoln(1:01:03) – Grant vs Lee(1:09:57) – Could the Civil War have been avoided?

(1:19:23) – The bloodiest war in US history(1:36:31) – How the Confederate Army could’ve won(1:57:05) – Key battles of the Civil War(2:20:07) – Best and Worst Presidents(2:34:06) – Robert E. Lee(2:53:40) – The…

2 months, 2 weeks назад @ lexfridman.com
#498 – Anthony Kaldellis: Roman Empire, Byzantine Empire, Rise & Fall of Empires
#498 – Anthony Kaldellis: Roman Empire, Byzantine Empire, Rise & Fall of Empires #498 – Anthony Kaldellis: Roman Empire, Byzantine Empire, Rise & Fall of Empires

Anthony Kaldellis is a historian of the Roman Empire and author of “The New Roman Empire”, a comprehensive history of the Byzantine Empire (Eastern Roman Empire).

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep498-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

Go to https://upwork.com/lexFin: AI agent for customer service.

Go to https://fin.ai/lexBetterHelp: Online therapy and counseling.

Go to https://betterhelp.com/lexLMNT: Zero-sugar electrolyte drink mix.

3 months, 1 week назад @ lexfridman.com
#497 – Biggest Mysteries in Physics: Antimatter, Dark Energy & ToE – Don Lincoln
#497 – Biggest Mysteries in Physics: Antimatter, Dark Energy & ToE – Don Lincoln #497 – Biggest Mysteries in Physics: Antimatter, Dark Energy & ToE – Don Lincoln

Don Lincoln is a particle physicist at Fermilab who has spent decades working at the frontiers of high energy physics.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep497-scSee below for timestamps, and to give feedback, submit questions, contact Lex, etc.

Go to https://upwork.com/lexLarridin: Measure AI adoption in your business.

Go to https://larridin.comFin: AI agent for customer service.

Go to https://fin.ai/lexLMNT: Zero-sugar electrolyte drink mix.

4 months, 2 weeks назад @ lexfridman.com
#496 – FFmpeg: The Incredible Technology Behind Video on the Internet
#496 – FFmpeg: The Incredible Technology Behind Video on the Internet #496 – FFmpeg: The Incredible Technology Behind Video on the Internet

Jean-Baptiste Kempf is lead developer of VLC and president of VideoLAN.

Kieran Kunhya is a longtime FFmpeg contributor, codec engineer, and the person behind the now-infamous FFmpeg account on X.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep496-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

Go to https://larridin.comBlitzy: AI agent for large enterprise codebases.

Go to https://perplexity.ai/OUTLINE:(00:00) – Introduction(03:00) – Sponsors, Comments, and Reflections(10:48) – Weirdest things VLC opens(15:12) – How video playback works(24:33) – Video codecs and containers(35:20) – FFmpeg explained(56:20)…

5 months, 1 week назад @ lexfridman.com
#495 – Vikings, Ragnar, Berserkers, Valhalla & the Warriors of the Viking Age
#495 – Vikings, Ragnar, Berserkers, Valhalla & the Warriors of the Viking Age #495 – Vikings, Ragnar, Berserkers, Valhalla & the Warriors of the Viking Age

Lars Brownworth is a historian, teacher, podcaster, and author specializing in Viking history, medieval Europe, and the Byzantine Empire.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep495-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

Go to https://larridin.comBetterHelp: Online therapy and counseling.

Go to https://drinkLMNT.com/lexFin: AI agent for customer service.

Go to https://perplexity.ai/OUTLINE:(00:00) – Introduction(01:03) – Sponsors, Comments, and Reflections(08:57) – The start of the Viking Age(18:50) – Viking military strategy, tactics & technology(32:33) – Ragnar Lothbrok(42:00) – The Grea…

6 months назад @ lexfridman.com
#494 – Jensen Huang: NVIDIA – The $4 Trillion Company & the AI Revolution
#494 – Jensen Huang: NVIDIA – The $4 Trillion Company & the AI Revolution #494 – Jensen Huang: NVIDIA – The $4 Trillion Company & the AI Revolution

Jensen Huang is the co-founder and CEO of NVIDIA, the world’s most valuable company and the engine powering the AI computing revolution.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep494-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

Go to https://drinkLMNT.com/lexFin: AI agent for customer service.

Go to https://quo.com/lexOUTLINE:(00:00) – Introduction(00:26) – Sponsors, Comments, and Reflections(06:34) – Extreme co-design and rack-scale engineering(09:20) – How Jensen runs NVIDIA(28:41) – AI scaling laws(43:41) – Biggest blockers to AI scaling laws(45:25) – Supply chain(47:20) – Memory(53:25) – Power…

6 months, 3 weeks назад @ lexfridman.com
#493 – Jeff Kaplan: World of Warcraft, Overwatch, Blizzard, and Future of Gaming
#493 – Jeff Kaplan: World of Warcraft, Overwatch, Blizzard, and Future of Gaming #493 – Jeff Kaplan: World of Warcraft, Overwatch, Blizzard, and Future of Gaming

Jeff Kaplan is a legendary Blizzard game designer of World of Warcraft and Overwatch, now preparing to launch a new game, The Legend of California, from his new studio Kintsugiyama – available to wishlist on Steam today, with alpha later in March.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep493-scSee below for timestamps, and to give feedback, submit questions, contact Lex, etc.

Go to https://fin.ai/lexBlitzy: AI agent for large enterprise codebases.

Go to https://blitzy.com/lexBetterHelp: Online therapy and counseling.

Go to https://betterhelp.com/lexShopify: Sell stuff online.

7 months назад @ lexfridman.com
#492 – Rick Beato: Greatest Guitarists of All Time, History & Future of Music
#492 – Rick Beato: Greatest Guitarists of All Time, History & Future of Music #492 – Rick Beato: Greatest Guitarists of All Time, History & Future of Music

Rick Beato is a music educator, interviewer, producer, songwriter, and a true multi-instrument musician, playing guitar, bass, cello & piano.

His incredible YouTube channel celebrates great musicians & musical ideas, and helps millions of people fall in love with great music all over again.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep492-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

Go to https://upliftdesk.com/lexBetterHelp: Online therapy and counseling.

Go to https://drinkLMNT.com/lexFin: AI agent for customer service.

7 months, 2 weeks назад @ lexfridman.com
#491 – OpenClaw: The Viral AI Agent that Broke the Internet – Peter Steinberger
#491 – OpenClaw: The Viral AI Agent that Broke the Internet – Peter Steinberger #491 – OpenClaw: The Viral AI Agent that Broke the Internet – Peter Steinberger

Peter Steinberger is the creator of OpenClaw, an open-source AI agent framework that’s the fastest-growing project in GitHub history.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep491-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

Go to https://coderabbit.ai/lexFin: AI agent for customer service.

Go to https://fin.ai/lexBlitzy: AI agent for large enterprise codebases.

Go to https://drinkLMNT.com/lexOUTLINE:(00:00) – Introduction(03:51) – Sponsors, Comments, and Reflections(15:29) – OpenClaw origin story(18:48) – Mind-blowing moment(28:15) – Why OpenClaw went viral(32:12) – Self-modifying AI agent(36:57)…

8 months назад @ lexfridman.com
#490 – State of AI in 2026: LLMs, Coding, Scaling Laws, China, Agents, GPUs, AGI
#490 – State of AI in 2026: LLMs, Coding, Scaling Laws, China, Agents, GPUs, AGI #490 – State of AI in 2026: LLMs, Coding, Scaling Laws, China, Agents, GPUs, AGI

Nathan Lambert and Sebastian Raschka are machine learning researchers, engineers, and educators.

Sebastian Raschka is the author of Build a Large Language Model (From Scratch) and Build a Reasoning Model (From Scratch).

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep490-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

(25:11) – ChatGPT vs Claude vs Gemini vs Grok: Who is winning?

(36:11) – Best AI for coding(43:02) – Open Source vs Closed Source LLMs(54:41) – Transformers: Evolution of LLMs since 2019(1:02:38) – AI Scaling Laws: Are they dead or still holding?

8 months, 1 week назад @ lexfridman.com
#489 – Paul Rosolie: Uncontacted Tribes in the Amazon Jungle
#489 – Paul Rosolie: Uncontacted Tribes in the Amazon Jungle #489 – Paul Rosolie: Uncontacted Tribes in the Amazon Jungle

Paul Rosolie is a naturalist, explorer, author of a new book titled Junglekeeper, and is someone who has dedicated his life to protecting the Amazon rainforest.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep489-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

Go to https://perplexity.ai/BetterHelp: Online therapy and counseling.

Go to https://fin.ai/lexMiro: Online collaborative whiteboard platform.

Go to https://miro.com/MasterClass: Online classes from world-class experts.

9 months назад @ lexfridman.com
#488 – Infinity, Paradoxes that Broke Mathematics, Gödel Incompleteness & the Multiverse – Joel David Hamkins
#488 – Infinity, Paradoxes that Broke Mathematics, Gödel Incompleteness & the Multiverse – Joel David Hamkins #488 – Infinity, Paradoxes that Broke Mathematics, Gödel Incompleteness & the Multiverse – Joel David Hamkins

Joel David Hamkins is a mathematician and philosopher specializing in set theory, the foundations of mathematics, and the nature of infinity, and he’s the #1 highest-rated user on MathOverflow.

He is also the author of several books, including Proof and the Art of Mathematics and Lectures on the Philosophy of Mathematics.

Thank you for listening ❤ Check out our sponsors: https://lexfridman.com/sponsors/ep488-scSee below for timestamps, transcript, and to give feedback, submit questions, contact Lex, etc.

Go to https://masterclass.com/lexpodOUTLINE:(00:00) – Introduction(01:58) – Sponsors, Comments, and Reflections(15:40) – Infinity & paradoxes(1:02:50) – Russell’s paradox(1:15:57) – Gödel’s…

9 months, 1 week назад @ lexfridman.com
Microsoft Research Podcast Microsoft Research Podcast
последний пост 5 days, 2 hours назад
What AI gets wrong and what failure teaches us
What AI gets wrong and what failure teaches us What AI gets wrong and what failure teaches us

NEVILLE: My research, kind of, spans the spectrum from theory to application.

But right now, if you’re doing work on AI systems, I think that industry is really the place to be.

What we really focus on is trying to push the frontier of behavior of these AI systems in realistic work environments.

NEVILLE: That’s, that’s a, that’s a big question.

But I think I’m very bullish on the research that’s happening.

5 days, 2 hours назад @ microsoft.com
Called to serve: Tech, research, and positive impact with Chris White
Called to serve: Tech, research, and positive impact with Chris White Called to serve: Tech, research, and positive impact with Chris White

Lab Director Chris White has worked on research challenges with real-world implications—from new approaches to wartime data analysis to tools for combating human trafficking. He talks to program manager Weishung Liu about the influences that led to the work and more.Show notes

1 month назад @ microsoft.com
Can we AI our way to a more sustainable world?
Can we AI our way to a more sustainable world? Can we AI our way to a more sustainable world?

Because I do think there’s a role for AI, a huge role for AI.

BURGER: Right, right.

BURGER: Right, right.

So I think that’s also something quite important here that, you know, AI can help facilitate.

And I think that’s not just applying AI to solve solutions through optimization but also thinking about this in an integrated way.

5 months, 3 weeks назад @ microsoft.com
Ideas: Steering AI toward the work future we want
Ideas: Steering AI toward the work future we want Ideas: Steering AI toward the work future we want

JANSSEN: Yeah, yeah, exactly.

TEEVAN: Yeah, yeah, yeah.

I’m curious what you have found particularly surprising about how people and organizations are leveraging AI right now.

And so I do like to picture a future of work where humans are flourishing with AI and where humans still get to do meaningful work.

And I’m very curious about how we can take advantage of AI and do more without running ourselves into the ground because we’re not AI, right?

6 months назад @ microsoft.com
Will machines ever be intelligent?
Will machines ever be intelligent? Will machines ever be intelligent?

And the question we’re going to discuss is, are machines intelligent?

No, no, that’s right, that’s right.

I mean, in some sense, you could potentially have a super intelligent system, right, that’s far more intelligent than anything else on the planet.

BURGER: Right, right.

At the same time, I think, you know, transformers are not intelligent in the way that a three-year-old is, right?

6 months, 3 weeks назад @ microsoft.com
Trailer: The Shape of Things to Come
Trailer: The Shape of Things to Come Trailer: The Shape of Things to Come

Join Microsoft’s Doug Burger and guests as they dig into the fundamental truths about AI and how it will reshape the future.

Technical advances are moving at such a rapid pace that it can be challenging to define the tomorrow we’re working toward.

In The Shape of Things to Come, Microsoft research leader Doug Burger and experts from across disciplines tease out the thorniest AI issues facing technologists, policymakers, business decision-makers, and other stakeholders today.

It’s important to understand what the emerging shapes are and how we should respond.” – Doug Burger, Technical Fellow and Corporate Vice President, Microsoft ResearchAbout Doug BurgerDoug Burger is a research leader in …

7 months, 1 week назад @ microsoft.com
NLP Highlights NLP Highlights
последний пост None
Data Skeptic
последний пост 5 days, 22 hours назад
Implicit Interactions
Implicit Interactions Implicit Interactions

How do we design robots and autonomous vehicles that understand the unwritten rules of human behavior?

Kyle speaks with Cornell Tech professor Wendy Ju about implicit interaction, “Wizard of Oz” prototyping, and what studying pedestrians, self-driving cars, and even robotic furniture can teach us about designing technology that behaves the way people expect.

GuestWendy Ju: Wendy Ju is Professor of Information Science at the Jacobs Technion-Cornell Institute at Cornell Tech and inaugural faculty in Cornell’s new multi-college Design Tech department.

Prof. Ju has innovated numerous methods for early-stage prototyping of automated systems to understand how people will respond to systems …

5 days, 22 hours назад @ dataskeptic.com
The Lived Informatics Model
The Lived Informatics Model The Lived Informatics Model

The data we collect about ourselves can tell us a lot—but only if the technology collecting it actually fits into our lives.

Daniel Epstein explores personal informatics, from fitness trackers and food journals to baby tracking and AI, and explains why abandoning a tracking tool doesn’t necessarily mean it failed.

GuestDaniel Epstein: Daniel Epstein is an Associate Professor in the Department of Informatics at the UC Irvine, with a courtesy appointment in Computer Science.

His work in Human-Computer Interaction (HCI) examines how personal tracking technology can acknowledge and account for the realities of everyday life.

He received his Ph.D. in CSE from the University of Washington in …

2 weeks, 1 day назад @ dataskeptic.com
Recommender Systems Today and Tomorrow
Recommender Systems Today and Tomorrow Recommender Systems Today and Tomorrow

In the final episode of our Recommender Systems season, we explore the growing questions of trust, manipulation, privacy, fairness, sustainability, and user control.

From fake reviews and shilling attacks to explainable recommendations and user-selected algorithms, we look at what happens when recommender systems must answer not only for what they recommend, but for the consequences of those choices.

GuestsKyle Polich: Kyle is the founder of Data Skeptic, a popular podcast about artificial intelligence, machine learning, and data science.

Robin Burke: Professor Robin Burke conducts research in personalized recommender systems, a field he helped found and develop.

Professor Burke is the auth…

1 month назад @ dataskeptic.com
Recommender Systems Optimization Goals
Recommender Systems Optimization Goals Recommender Systems Optimization Goals

In part two of the Data Skeptic Recommender Systems season finale, Kyle asks a deceptively difficult question: what should recommender systems actually optimize for?

Drawing on conversations from across the season, the episode explores engagement, filter bubbles, popularity bias, fairness, human curation, embeddings, and the growing role—and risks—of large language models in shaping what gets recommended to us.

1 month, 1 week назад @ dataskeptic.com
Recommender Systems Origin Story
Recommender Systems Origin Story Recommender Systems Origin Story

Where did recommender systems come from, and how do we know when they're actually working? In part one of Data Skeptic's three-part Recommender Systems finale, Kyle traces the field from collaborative filtering and the Netflix Prize to matrix factorization and modern approaches, while exploring why accuracy alone can't capture what makes a recommendation useful, surprising, or meaningful.

1 month, 3 weeks назад @ dataskeptic.com
Social Choice for Fair Recommendations
Social Choice for Fair Recommendations Social Choice for Fair Recommendations

Recommender systems influence nearly every aspect of our digital lives—but what does it mean for those systems to be fair? Robin Burke joins Data Skeptic to discuss the history of recommender systems, the limitations of optimizing purely for accuracy, and how ideas from social choice theory can help balance the needs of users, creators, and society. The conversation explores the future of recommendation algorithms and why fairness is a far more complex challenge than it first appears.

2 months, 2 weeks назад @ dataskeptic.com
News Recommendations
News Recommendations News Recommendations

News recommendation algorithms influence far more than what stories we click—they can shape our understanding of the world. In this episode, Kyle Polich speaks with Andreea Iana about responsible AI, filter bubbles, multilingual news recommendation, and her open-source NewsRecLib framework for evaluating recommender systems. They explore why bigger models aren't always better and how future recommendation systems can balance personalization with diversity and societal impact.

3 months, 1 week назад @ dataskeptic.com
Give Users the Wheel
Give Users the Wheel Give Users the Wheel

What if you could simply tell a recommendation system what you want instead of relying on likes, dislikes, and watch history? Kyle Polich talks with Fuyuan Lyu about the DPR framework, which combines large language models and traditional recommender systems to give users direct control over recommendations through natural language. Together they explore how conversational interfaces could transform platforms like YouTube, TikTok, and news feeds while preserving the strengths of modern recommendation algorithms.

3 months, 2 weeks назад @ dataskeptic.com
AutoLike
AutoLike AutoLike

How can researchers audit recommendation systems when the algorithms are hidden from view? Hieu Le joins Kyle Polich to discuss Auto-Like, a reinforcement learning framework that systematically explores how platforms like TikTok personalize content feeds. The conversation covers recommendation transparency, black-box auditing, and the future of platform accountability.

3 months, 3 weeks назад @ dataskeptic.com
Student Spotlight: Aaron Payne, Data Analyst
Student Spotlight: Aaron Payne, Data Analyst Student Spotlight: Aaron Payne, Data Analyst

Aaron Payne, an MBA student at Georgia Tech studying business analytics and a Senior Insights Analyst at Chick-fil-A, joins Kyle Polich to talk about turning analytics into decisions that matter. They unpack a real-world forecasting project with Comfama in Colombia, including messy data realities, interpretability tradeoffs, and why "data science for good" starts with the people impacted.

5 months, 1 week назад @ dataskeptic.com
The Future is Agentic in Recommender Systems
The Future is Agentic in Recommender Systems The Future is Agentic in Recommender Systems

Kyle Polich sits down with Yashar Deldjoo, research scientist and Associate Professor at the Polytechnic University of Bari, to explore how recommender systems have evolved and why trustworthiness matters. They unpack key dimensions of responsible AI, including robustness to adversarial attacks, privacy, explainability, and fairness, and discuss how LLMs introduce new risks like hallucinations. The episode closes with a look at "agentic" recommender systems, where tools and memory shift recommendations from ranked lists to end-to-end task completion.

5 months, 2 weeks назад @ dataskeptic.com
Book Ratings and Recommendations
Book Ratings and Recommendations Book Ratings and Recommendations

Goodreads star ratings can be misleading as measures of "book quality," and research from Hannes Rosenbusch suggests that for many professionally published books, differences between readers often matter more than differences between books. The episode also explores how to model reader preferences, why reviews often reveal more about the reviewer than the text, and how LLMs can aid computational literary research while still falling short of human editors in creative writing.

6 months, 2 weeks назад @ dataskeptic.com
Disentanglement and Interpretability in Recommender Systems
Disentanglement and Interpretability in Recommender Systems Disentanglement and Interpretability in Recommender Systems 7 months назад @ dataskeptic.com
Collective Altruism in Recommender Systems
Collective Altruism in Recommender Systems Collective Altruism in Recommender Systems

Ekaterina (Kat) Filadova from MIT EECS joins us to discuss strategic learning in recommender systems—what happens when users collectively coordinate to game recommendation algorithms. Kat's research reveals surprising findings: algorithmic "protest movements" can paradoxically help platforms by providing clearer preference signals, and the challenge of distinguishing coordinated behavior from bot activity is more complex than it appears. This episode explores the intersection of machine learning and game theory, examining what happens when your training data actively responds to your algorithm.

7 months, 2 weeks назад @ dataskeptic.com
Niche vs Mainstream
Niche vs Mainstream Niche vs Mainstream

Anas Buhayh discusses multi-stakeholder fairness in recommender systems and the S'mores framework—a simulation allowing users to choose between mainstream and niche algorithms. His research shows specialized recommenders improve utility for niche users while raising questions about filter bubbles and data privacy.

7 months, 3 weeks назад @ dataskeptic.com
SuperDataScience SuperDataScience
последний пост 2 days, 7 hours назад
1034: In Case You Missed It in September 2026
1034: In Case You Missed It in September 2026 1034: In Case You Missed It in September 2026

In ICYMI Episode #1034, Jon Krohn moves from what sits underneath AI systems to what it takes to live with them every day. Hear from Aishwarya Srinivasan, Luis Serrano, Katie Malone, Ish Shah and Dilani Kahawala, discussing why the bottleneck in shipping software has moved from execution to judgment, how a physicist recast attention in transformers as words bending space, why years of managing people may be the best preparation for managing AI agents, how one weekend side project burned through billions of tokens and which three problems are hardest to solve when a product has no user interface and never stops running. Additional materials: ⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠www.superdatascience.com…

2 days, 7 hours назад @ podtrac.com
1033: Workslop: The Hidden Cost of AI-Generated Work, with Prof. Jeff Hancock and Dr. Kate Niederhoffer
1033: Workslop: The Hidden Cost of AI-Generated Work, with Prof. Jeff Hancock and Dr. Kate Niederhoffer 1033: Workslop: The Hidden Cost of AI-Generated Work, with Prof. Jeff Hancock and Dr. Kate Niederhoffer

In Episode #1033, Prof. Jeff Hancock (Professor of Communication at Stanford) and Dr. Kate Niederhoffer (Chief Scientist at BetterUp) join Jon Krohn to explain the hidden cost of AI-generated work. A year ago they coined "workslop" in a Harvard Business Review article that went viral and landed the term among Merriam-Webster’s words of the year: content that masquerades as real work but quietly shifts the burden onto whoever receives it. Their research finds that 40% of workers have been sent workslop and 53% admit to producing it, at a cost running to millions of dollars a year for a large organisation. In this episode, they separate workslop from ordinary sloppy work, name the organisatio…

5 days, 7 hours назад @ podtrac.com
1032: Garbage In, Gospel Out: Agents Are Your New Customers, with Salesforce’s CDO Michael Andrew
1032: Garbage In, Gospel Out: Agents Are Your New Customers, with Salesforce’s CDO Michael Andrew 1032: Garbage In, Gospel Out: Agents Are Your New Customers, with Salesforce’s CDO Michael Andrew

During their #sponsored discussion, Chief Data Officer at Salesforce Michael Andrew talks to Jon Krohn about what changes for a data team when its customers are AI agents as well as people. Listen to the episode to hear Michael Andrew talk about why agents need ten times more trusted data than humans, how Salesforce untrapped its own customer data with Data 360 and what practitioners should be learning to stay effective in the agentic era! Additional materials: ⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠www.superdatascience.com/1032⁠⁠ Interested in sponsoring a SuperDataScience Podcast episode? Email [email protected] for sponsorship information.⁠⁠⁠ In this episode you will learn: (02:32) Ho…

1 week, 2 days назад @ podtrac.com
1031: Tokenomics: Why Your Agentic AI Bill Is Exploding (and How to Fix It), with Tyler Cox and Ish Shah
1031: Tokenomics: Why Your Agentic AI Bill Is Exploding (and How to Fix It), with Tyler Cox and Ish Shah 1031: Tokenomics: Why Your Agentic AI Bill Is Exploding (and How to Fix It), with Tyler Cox and Ish Shah

In Episode #1031, Ish Shah and Tyler Cox (Distinguished Engineers in the Office of the CTO for Dell Technologies' client group) join Jon Krohn to work out why agentic AI bills are exploding and what can be done about it. Over one weekend Ish burned roughly two billion tokens on a side project, and that is the ordinary shape of agentic work now: agents spawn sub-agents, the pie of work grows, and cheaper tokens only invite more ambitious projects. Tyler runs a small Dell lab that pushes hundreds of millions of tokens a day through local hardware instead. In this episode, they define what makes a system agentic, explain how to read a Pareto curve when choosing models, work through the jagged …

1 week, 5 days назад @ podtrac.com
1030: Garbage In, Gospel Out: Why Agents Need Better Data, with Salesforce's Gaurav Pathak
1030: Garbage In, Gospel Out: Why Agents Need Better Data, with Salesforce's Gaurav Pathak 1030: Garbage In, Gospel Out: Why Agents Need Better Data, with Salesforce's Gaurav Pathak

During their #sponsored discussion, Senior Vice President Product Management AI and Metadata at Salesforce, Gaurav Pathak talks to Jon Krohn about why AI agents need well-labeled, high-quality data to deliver reliable answers in the enterprise. Listen to the episode to hear Gaurav Pathak talk about the difference between a “data brawl” and “garbage in, gospel out”, who the “sin eaters” of enterprise AI are and the three skills that matter most for AI engineers today! Additional materials: ⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠www.superdatascience.com/1030⁠ Interested in sponsoring a SuperDataScience Podcast episode? Email [email protected] for sponsorship information.⁠⁠⁠ In this episode …

2 weeks, 2 days назад @ podtrac.com
1029: How AI Brought a Podcast Back From the Dead, with Linear Digressions’ Katie Malone
1029: How AI Brought a Podcast Back From the Dead, with Linear Digressions’ Katie Malone 1029: How AI Brought a Podcast Back From the Dead, with Linear Digressions’ Katie Malone

In Episode #1029, Dr. Katie Malone (Host of Linear Digressions) joins Jon Krohn to explain how AI brought her podcast back from the dead. After nearly 300 episodes, Katie shut down Linear Digressions due to burnout, but better tools helped her relaunch it six years later. Along the way she has taught machine learning at Udacity and the University of Chicago and led the development of agentic AI platforms inside a company of tens of thousands of people. In this episode, she argues that people management and agent management are the same skill in different clothing, works through what AI slop and process slop are doing to organisations, describes the agent that now produces her show, and take…

2 weeks, 5 days назад @ podtrac.com
1028: The Chip Built for Agentic AI Inference, with SambaNova's Anton McGonnell
1028: The Chip Built for Agentic AI Inference, with SambaNova's Anton McGonnell 1028: The Chip Built for Agentic AI Inference, with SambaNova's Anton McGonnell

In Episode #1028, Anton McGonnell (VP of Product at SambaNova) joins Jon Krohn to explain why the chips running most AI inference today were never designed for the job. Agentic AI has changed the computational profile of inference, with much larger inputs and far heavier caches feeding the token generation that follows, and that shift has exposed where GPU architecture struggles. SambaNova has raised over $2 billion to build an alternative, the reconfigurable dataflow unit, which lays a whole model out spatially across the chip rather than executing it kernel by kernel. In this episode, Anton discusses why the speed that matters is payback, and how speed and concurrency are what turn a fixe…

3 weeks, 2 days назад @ podtrac.com
1027: Building an Always-On AI Agent for Busy Parents, with Dr. Dilani Kahawala
1027: Building an Always-On AI Agent for Busy Parents, with Dr. Dilani Kahawala 1027: Building an Always-On AI Agent for Busy Parents, with Dr. Dilani Kahawala

In Episode #1027, Dr. Dilani Kahawala (Co-Founder and CEO of Anna) joins Jon Krohn to explain what it takes to build an always-on AI assistant that busy parents will trust with their inboxes. Anna watches the email, school apps, WhatsApp messages and calendars flowing into a family's life and surfaces what matters, over text and voice, with barely any app to speak of. Dilani came to it by way of a Harvard physics PhD, McKinsey, and a decade of product leadership at Etsy, Meta and Atlassian, and says she has had to throw away most of what that decade taught her about how products get built. In this episode, she lays out the three hardest problems in building Anna, why the eval loop is the he…

3 weeks, 5 days назад @ podtrac.com
1026: OpenAI’s GPT-6 Astra
1026: OpenAI’s GPT-6 Astra 1026: OpenAI’s GPT-6 Astra

In Episode #1026, Jon Krohn breaks down GPT-6 Astra, OpenAI’s new flagship that its president has floated as a possible marker of AGI. Jon covers what the model is, what it costs, its state-of-the-art results across computer use, coding, abstract reasoning and science and the safety story, which for this release is unusually intertwined with capability. He weighs the AGI claim against Anthropic’s Fable 5.1 and lands, as ever, in a measured middle. Additional materials:⁠ ⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠www.superdatascience.com/1026⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠ Interested in sponsoring a SuperDataScience Podcast episode? Email [email protected] for sponsorship information. In this ep…

1 month назад @ podtrac.com
1025: Word Gravity: How Transformers Bend Space, with Dr. Luis Serrano
1025: Word Gravity: How Transformers Bend Space, with Dr. Luis Serrano 1025: Word Gravity: How Transformers Bend Space, with Dr. Luis Serrano

In Episode #1025, Dr. Luis Serrano (Founder of Serrano Academy) joins Jon Krohn to explain the paper he co-authored on the curved spacetime of transformer architectures, in which attention stops being a lookup table and becomes something closer to gravity: words bend the space around them, and the embedding of "bank" visibly curves toward "river" as it travels through the layers of the network. In this episode, he recreates Eddington’s 1919 eclipse experiment inside a transformer, draws the line between an LLM workflow and an actual agent, explains why agent evaluation is a step harder than evaluating an essay, and gives the cleanest account of GRPO you will hear. Additional materials: ⁠⁠⁠⁠…

1 month назад @ podtrac.com
1024: In Case You Missed It in August 2026
1024: In Case You Missed It in August 2026 1024: In Case You Missed It in August 2026

In ICYMI Episode #1024, Jon Krohn tracks the gap between AI investment and AI return, from the technology side to the people side. Hear from Pete Johnson, Jerry Yurchisin, Priyanka Vergadia and Tristan Handy, discussing why four out of five organizations have the structures for AI success in place while only one in five sees the returns, which decisions should never be handed to a language model however confident it sounds, how to structure Claude skills so that your output stops being slop and why the semantic layer matters more, not less, now that analytics agents are the ones asking the questions. Additional materials: ⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠www.superdatascience.com/1024⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠ …

1 month, 1 week назад @ podtrac.com
1023: Agentic AI Skills That Matter Now, with Aishwarya Srinivasan
1023: Agentic AI Skills That Matter Now, with Aishwarya Srinivasan 1023: Agentic AI Skills That Matter Now, with Aishwarya Srinivasan

In Episode #1023, Aishwarya Srinivasan (Co-Founder of The Gen Academy) joins Jon Krohn to work out where a competitive moat comes from once anything you can build in ten minutes, somebody else can build in ten minutes too. Ash came to teaching through Illuminate AI, the mentorship community she started in 2020, and now trains senior engineers and leaders to ship agentic AI in production; she is blunt that vibe coding lowers the floor without touching the engineering judgment that production demands. In this episode, she explains what a whole-system eval covers that a model eval misses, traces reinforcement learning from the algorithm she patented at IBM to its resurgence in agentic fine tun…

1 month, 1 week назад @ podtrac.com
1022: CLAUDE.md, AGENTS.md, Skills, Hooks and Subagents: A Field Guide to Steering AI Agents
1022: CLAUDE.md, AGENTS.md, Skills, Hooks and Subagents: A Field Guide to Steering AI Agents 1022: CLAUDE.md, AGENTS.md, Skills, Hooks and Subagents: A Field Guide to Steering AI Agents

In Episode #1022, Jon Krohn tackles the art of steering AI agents, deciding where your instructions should live so they get followed reliably without bloating every request. A sequel to Episode #1020 (where model size and effort set an agent’s horsepower), this one is about direction: the seven ways to deliver instructions, why a hook beats a prompt, the industry-wide agents.md standard, and three practical takeaways you can apply whatever your stack. Additional materials:⁠ ⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠www.superdatascience.com/1022⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠⁠ Interested in sponsoring a SuperDataScience Podcast episode? Email [email protected] for sponsorship information. In this …

1 month, 2 weeks назад @ podtrac.com
1021: How dbt Won Analytics Engineering, with dbt Lab’s CEO Tristan Handy
1021: How dbt Won Analytics Engineering, with dbt Lab’s CEO Tristan Handy 1021: How dbt Won Analytics Engineering, with dbt Lab’s CEO Tristan Handy

In Episode #1021, Tristan Handy (Founder and CEO of dbt Labs) joins Jon Krohn to explain how a study of about a hundred companies in 2016 became analytics engineering, and then became a tool that over a hundred thousand data teams rely on. Tristan coined the term, chose SQL when Spark was the fashionable answer, and spent a decade turning down acquisition offers because none of them were good for the people using dbt. He is now merging dbt Labs with Fivetran and taking on the presidency of the combined company, the first deal he says cleared that bar. In this episode, Tristan walks through what dbt does to your raw data, argues that the semantic layer matters more once analytics agents are …

1 month, 2 weeks назад @ podtrac.com
1020: How to Choose Model Size and Effort Level: The Two Critical Dials
1020: How to Choose Model Size and Effort Level: The Two Critical Dials 1020: How to Choose Model Size and Effort Level: The Two Critical Dials

In Episode #1020, Jon Krohn unpacks the two dials that increasingly decide what you get out of a large language model: which model size you pick and how much effort you tell it to spend. Using a July Anthropic blog post by Claude Code’s Lydia Holly as a jumping-off point, with guidance that generalizes to any model family, Jon explains what each setting actually does under the hood. Model size swaps which frozen weights handle your request (roughly, how capable), while effort sets how thorough and certain the model must be before calling a task done, not a simple “thinking-time slider.” He offers a clean diagnostic for when to raise effort versus move to a bigger model, shows why cheaper-pe…

1 month, 3 weeks назад @ podtrac.com
Data Science at Home Data Science at Home
последний пост 6 days, 12 hours назад
One researcher published the ‘System 1 AI’ idea in 2025; a frontier lab shipped it as new in 2026 (Ep. 314)
One researcher published the ‘System 1 AI’ idea in 2025; a frontier lab shipped it as new in 2026 (Ep. 314) One researcher published the ‘System 1 AI’ idea in 2025; a frontier lab shipped it as new in 2026 (Ep. 314)

Personal newsletter: https://defragzone.substack.com📩 Newsletter: https://datascienceathome.substack.com🎙 Podcast: Available on Spotify, Apple Podcasts, and more.

🐦 Twitter: @DataScienceAtHome📘 LinkedIn: https://www.linkedin.com/in/fragadaleta/Instagram: https://www.instagram.com/datascienceathome/Facebook: https://www.facebook.com/datascienceAHLinkedIn: https://www.linkedin.com/company/data-science-at-home-podcastNEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Whether you’re a data professional, tech enthusiast, or just curious about the field, our podcast delivers insights, interviews, and discussions.

Send us mail at:hello@…

6 days, 12 hours назад @ datascienceathome.com
EU AI Act. What is this thing? (Part 2) (Ep. 311)
EU AI Act. What is this thing? (Part 2) (Ep. 311) EU AI Act. What is this thing? (Part 2) (Ep. 311)

What is “wrong” with the EU AI Act?

Check outshift.comCheck out Drift by Amethix and stay safe on potential EU AI Act violations.

NEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Send us mail at: [email protected]’t forget to like, subscribe, and hit the 🔔 for updates on the latest in AI and data science!

6 days, 12 hours назад @ datascienceathome.com
AI is punishing game developers (Ep. 312)
AI is punishing game developers (Ep. 312) AI is punishing game developers (Ep. 312)

This and much more is covered in this 1st episode of AI and videogames.

NEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Whether you’re a data professional, tech enthusiast, or just curious about the field, our podcast delivers insights, interviews, and discussions.

Send us mail at: [email protected]’t forget to like, subscribe, and hit the 🔔 for updates on the latest in AI and data science!

6 days, 12 hours назад @ datascienceathome.com
AI slowdown: why Altman, Amodei & Musk suddenly agree (Ep. 313)
AI slowdown: why Altman, Amodei & Musk suddenly agree (Ep. 313) AI slowdown: why Altman, Amodei & Musk suddenly agree (Ep. 313)

Personal newsletter: https://defragzone.substack.com📩 Newsletter: https://datascienceathome.substack.com🎙 Podcast: Available on Spotify, Apple Podcasts, and more.

🐦 Twitter: @DataScienceAtHome📘 LinkedIn: https://www.linkedin.com/in/fragadaleta/Instagram: https://www.instagram.com/datascienceathome/Facebook: https://www.facebook.com/datascienceAHLinkedIn: https://www.linkedin.com/company/data-science-at-home-podcastNEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Whether you’re a data professional, tech enthusiast, or just curious about the field, our podcast delivers insights, interviews, and discussions.

Send us mail at:hello@…

6 days, 12 hours назад @ datascienceathome.com
EU AI Act. What is this thing? (Part 1) (Ep. 310)
EU AI Act. What is this thing? (Part 1) (Ep. 310) EU AI Act. What is this thing? (Part 1) (Ep. 310)

Check outshift.comCheck out Drift by Amethix and stay safe on potential EU AI Act violations.

NEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Whether you’re a data professional, tech enthusiast, or just curious about the field, our podcast delivers insights, interviews, and discussions.

Send us mail at: [email protected]’t forget to like, subscribe, and hit the 🔔 for updates on the latest in AI and data science!

2 months, 3 weeks назад @ datascienceathome.com
The propaganda algorithm (Ep. 308)
The propaganda algorithm (Ep. 308) The propaganda algorithm (Ep. 308)

It’s a repeatable, engineered algorithm that starts with ideology, weaponizes identity, and manufactures conflict.

Check outshift.comNEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Whether you’re a data professional, tech enthusiast, or just curious about the field, our podcast delivers insights, interviews, and discussions.

Send us mail at: [email protected]’t forget to like, subscribe, and hit the 🔔 for updates on the latest in AI and data science!

2 months, 3 weeks назад @ datascienceathome.com
AI is the Concorde of our time (Ep. 309)
AI is the Concorde of our time (Ep. 309) AI is the Concorde of our time (Ep. 309)

Global data center investment now surpasses global oil supply spending.

Check outshift.comNEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Whether you’re a data professional, tech enthusiast, or just curious about the field, our podcast delivers insights, interviews, and discussions.

Send us mail at: [email protected]’t forget to like, subscribe, and hit the 🔔 for updates on the latest in AI and data science!

3 months, 2 weeks назад @ datascienceathome.com
Recommend and manipulate: the dangers of the attention economy
Recommend and manipulate: the dangers of the attention economy Recommend and manipulate: the dangers of the attention economy

This sort of operation is directly exploiting a core feature of internet social media platforms.

The main purpose of recommender systems is to recommend people the same items similar people show an interest in.

Some of the most common methods to implement recommender systems, use concepts such as cosine/correlation similarity, matrix factorization, neural autoencoders and sequence predictors.

As you say, recommender systems exist because the business model of social media platforms is to monetise attention.

F: So you are saying that this is not an accident: is this the basis of the optimisation of the recommender system?

4 months, 3 weeks назад @ datascienceathome.com
Social media is an ant mill (Internet is a disaster) (Ep. 303)
Social media is an ant mill (Internet is a disaster) (Ep. 303) Social media is an ant mill (Internet is a disaster) (Ep. 303)

Personal newsletter:https://defragzone.substack.com📩 Newsletter: https://datascienceathome.substack.com🎙 Podcast: Available on Spotify, Apple Podcasts, and more.

🐦 Twitter: @DataScienceAtHome📘LinkedIn: https://www.linkedin.com/in/fragadaleta/Instagram: https://www.instagram.com/datascienceathome/Facebook: https://www.facebook.com/datascienceAHLinkedIn: https://www.linkedin.com/company/data-science-at-home-podcastDiscord Channel: https://discord.gg/4UNKGf3NEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Whether you’re a data professional, tech enthusiast, or just curious about the field, our podcast delivers insights, interviews…

4 months, 3 weeks назад @ datascienceathome.com
AI and videogames (Ep. 305)
AI and videogames (Ep. 305) AI and videogames (Ep. 305)

What is the state of AI and videogames?

This and much more is covered in this 1st episode of AI and videogames.

Check outshift.comNEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Send us mail at: [email protected]’t forget to like, subscribe, and hit the 🔔 for updates on the latest in AI and data science!

4 months, 3 weeks назад @ datascienceathome.com
AI and videogames: Conversational NPCs (Ep. 306)
AI and videogames: Conversational NPCs (Ep. 306) AI and videogames: Conversational NPCs (Ep. 306)

Can NPCs in videogames leverage new LLM-based tech?

Check outshift.comNEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Whether you’re a data professional, tech enthusiast, or just curious about the field, our podcast delivers insights, interviews, and discussions.

Send us mail at: [email protected]’t forget to like, subscribe, and hit the 🔔 for updates on the latest in AI and data science!

4 months, 3 weeks назад @ datascienceathome.com
AI tips & tricks (Ep. 307)
AI tips & tricks (Ep. 307) AI tips & tricks (Ep. 307)

🐦 Twitter: @DataScienceAtHome📘LinkedIn: https://www.linkedin.com/in/fragadaleta/Instagram: https://www.instagram.com/datascienceathome/Facebook: https://www.facebook.com/datascienceAHLinkedIn: https://www.linkedin.com/company/data-science-at-home-podcastSPONSORSThis episode is brought to you by Outshift, Cisco’s incubation engine.

Check outshift.comNEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Whether you’re a data professional, tech enthusiast, or just curious about the field, our podcast delivers insights, interviews, and discussions.

Send us mail at: [email protected]’t forget to like, subscribe, and hit the …

4 months, 3 weeks назад @ datascienceathome.com
Europe, wake up! You Can’t Be a Superpower on Someone Else’s Servers (Ep. 304)
Europe, wake up! You Can’t Be a Superpower on Someone Else’s Servers (Ep. 304) Europe, wake up! You Can’t Be a Superpower on Someone Else’s Servers (Ep. 304)

Tech sovereignty takes 3 years and political will.

Check outshift.comNEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Whether you’re a data professional, tech enthusiast, or just curious about the field, our podcast delivers insights, interviews, and discussions.

Send us mail at: [email protected]’t forget to like, subscribe, and hit the 🔔 for updates on the latest in AI and data science!

5 months, 3 weeks назад @ datascienceathome.com
About Apple’s Privacy (Ep. 302)
About Apple’s Privacy (Ep. 302) About Apple’s Privacy (Ep. 302)

Apple just spent $2B on tech that reads your silent speech.

🐦 Twitter: @DataScienceAtHome📘LinkedIn: https://www.linkedin.com/in/fragadaleta/Instagram: https://www.instagram.com/datascienceathome/Facebook: https://www.facebook.com/datascienceAHLinkedIn: https://www.linkedin.com/company/data-science-at-home-podcastDiscord Channel: https://discord.gg/4UNKGf3NEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Whether you’re a data professional, tech enthusiast, or just curious about the field, our podcast delivers insights, interviews, and discussions.

Send us mail at: [email protected]’t forget to like, subscribe, and hi…

5 months, 3 weeks назад @ datascienceathome.com
Productivity is the new data breach (Ep. 301)
Productivity is the new data breach (Ep. 301) Productivity is the new data breach (Ep. 301)

Personal newsletter:https://defragzone.substack.com📩 Newsletter: https://datascienceathome.substack.com🎙 Podcast: Available on Spotify, Apple Podcasts, and more.

🐦 Twitter: @DataScienceAtHome📘LinkedIn: https://www.linkedin.com/in/fragadaleta/Instagram: https://www.instagram.com/datascienceathome/Facebook: https://www.facebook.com/datascienceAHLinkedIn: https://www.linkedin.com/company/data-science-at-home-podcastDiscord Channel: https://discord.gg/4UNKGf3NEW TO DATA SCIENCE AT HOME?

Data Science at Home explores the latest in AI, data science, and machine learning.

Whether you’re a data professional, tech enthusiast, or just curious about the field, our podcast delivers insights, interviews…

5 months, 3 weeks назад @ datascienceathome.com